Computing measures of explained variation for logistic regression models
Related Experiment Video
Updated: Oct 23, 2026

Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
1Department of Medical Computer Sciences, University of Vienna, Austria. Martina.Mittlboeck@AKH-Wien.AC.AT

Abstract:
The proportion of explained variation (R2) is frequently used in the general linear model but in logistic regression no standard definition of R2 exists. We present a SAS macro which calculates two R2-measures based on Pearson and on deviance residuals for logistic regression. Also, adjusted versions for both measures are given, which should prevent the inflation of R2 in small samples.
Related Concept Videos
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:14
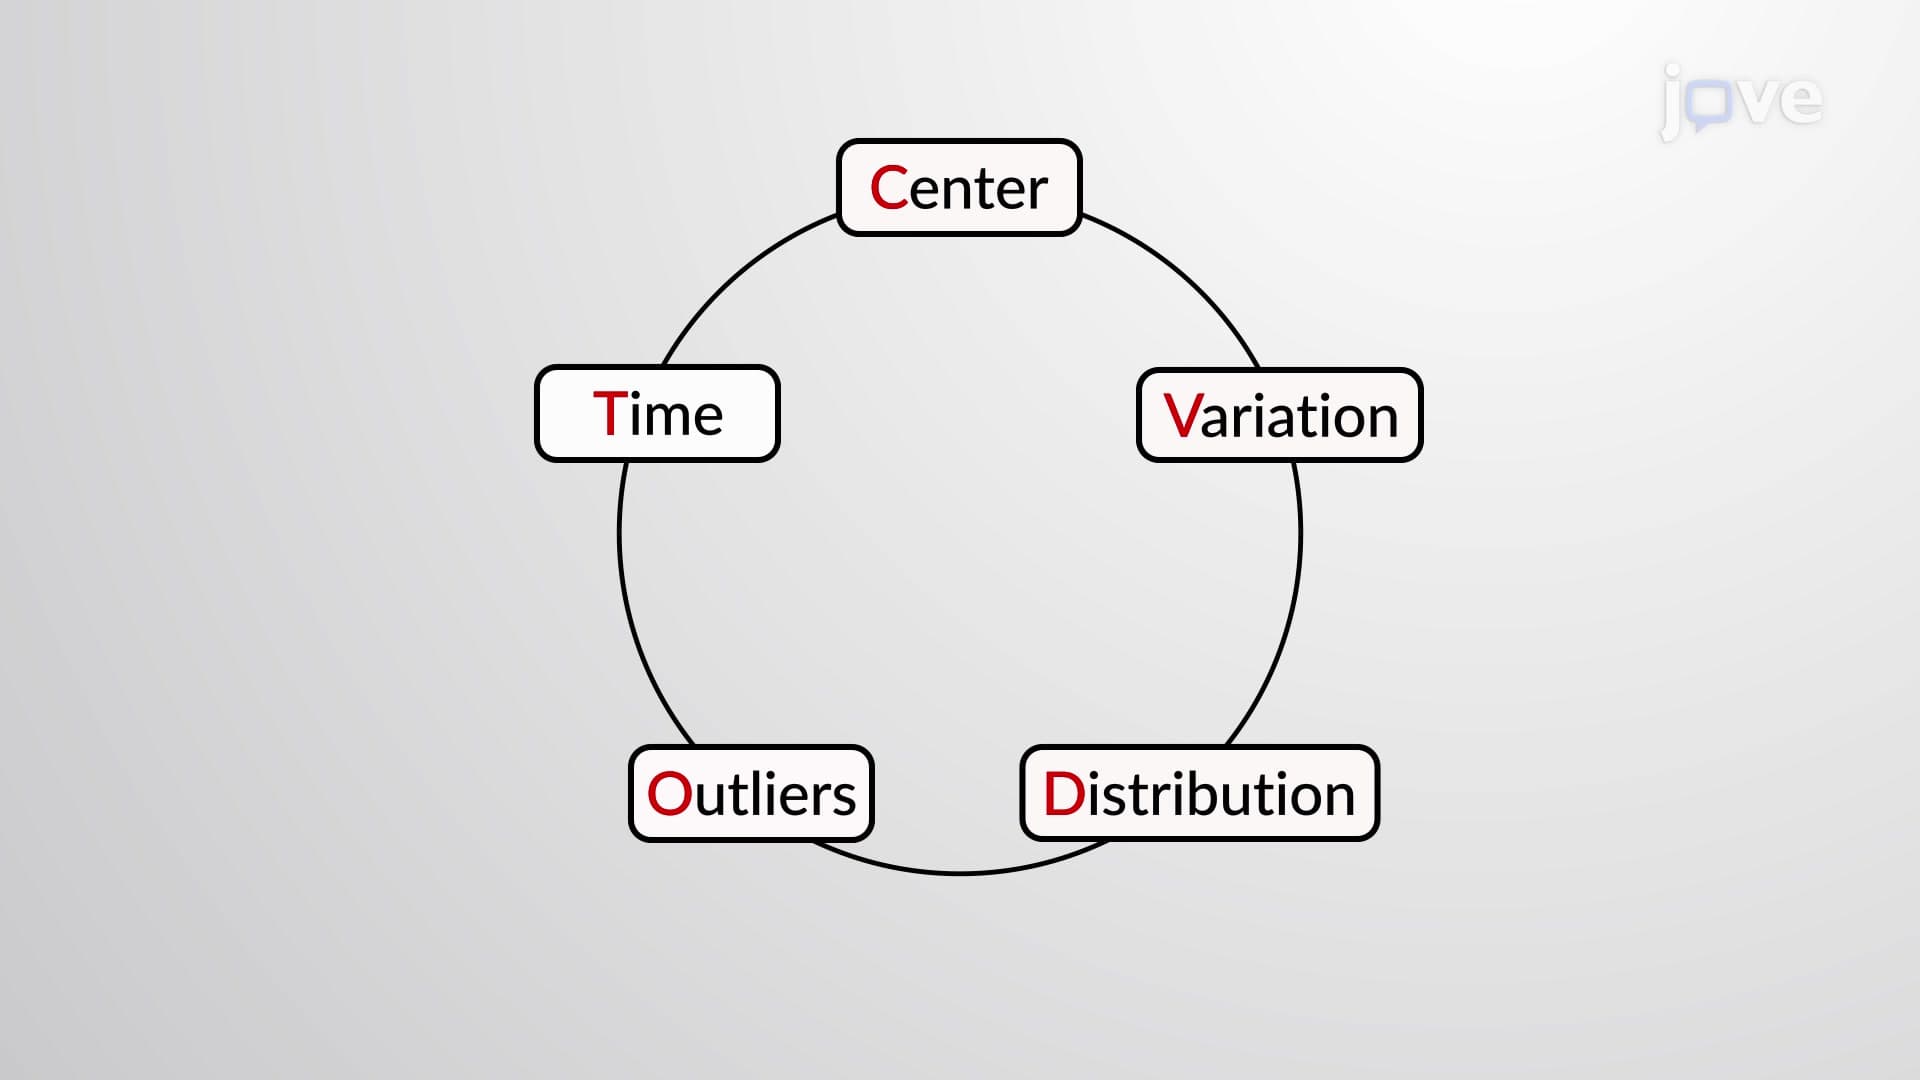
What is Variation?
The range, standard deviation, standard error, and variance are the different measures of variation.
Range: The range is the difference between its maximum and...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:10
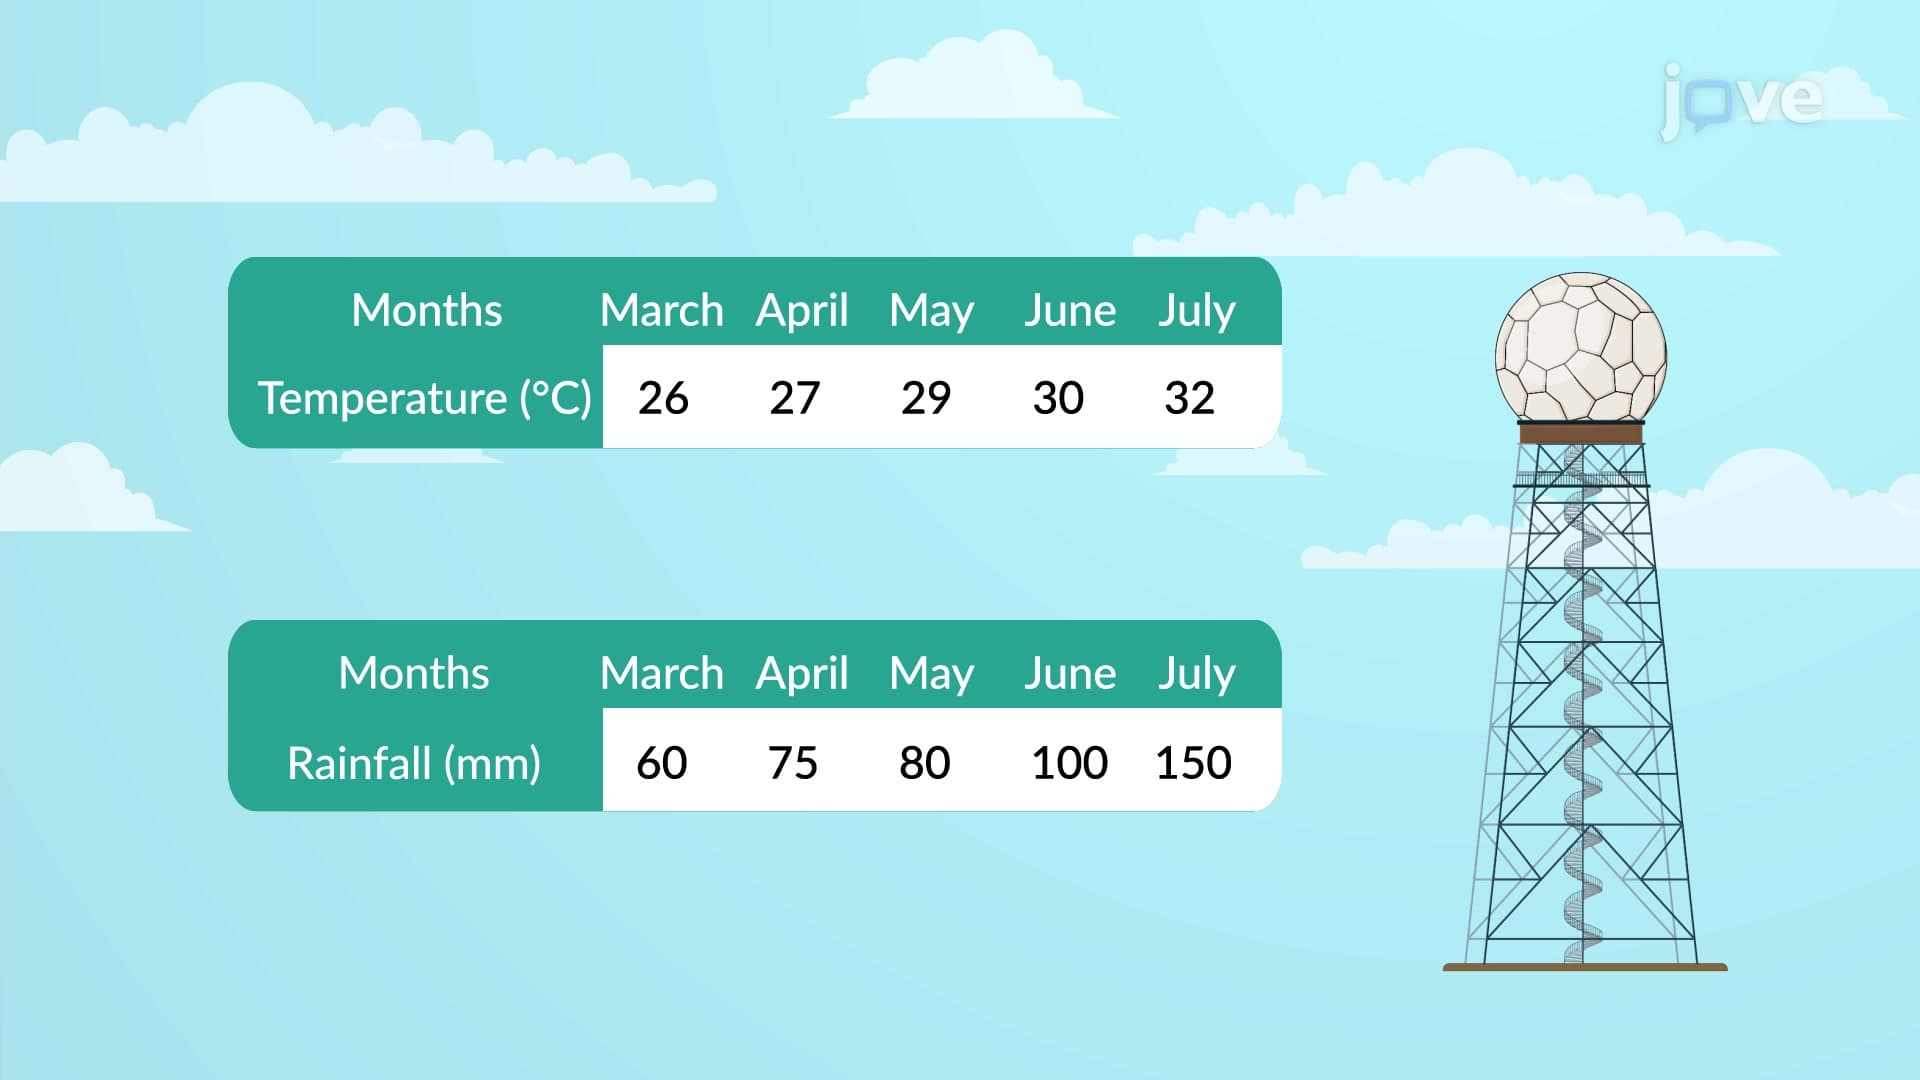
Coefficient of Variation
The coefficient of variation is a practical statistical tool in finance. It allows investors to assess the volatility or...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...