Optimal structure for automatic processing of DNA sequences
Related Experiment Video
Updated: Oct 19, 2026
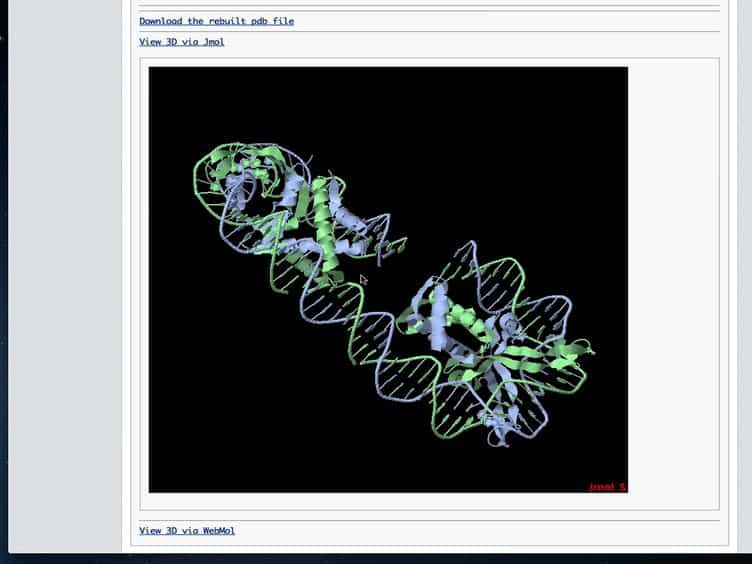
Analyzing and Building Nucleic Acid Structures with 3DNA
Published on: April 26, 2013
S W Davies1, M Eizenman, S Pasupathy
1Bell Laboratories, Holmdel, NJ 07733-3030, USA.

Abstract:
The faithful recovery of the base sequence in automatic DeoxyriboNucleic Acid (DNA) sequencing fundamentally depends on the underlying statistics of the DNA electrophoresis time series. Current DNA sequencing algorithms are heuristic in nature and modest in their use of statistical information. In this paper, a formal statistical model of the DNA time series is presented and then used to construct the optimal maximum-likelihood (ML) processor. The DNA-ML algorithm that is derived in this paper features Kalman prediction of peak locations, peak parameter estimation, whitened waveform comparison and multiple hypothesis processing using the M-algorithm. Properties of the algorithm are examined using both simulated and real data. Model parameters of critical importance and their impact on different types of error mechanisms, such as insertions and deletions, are pointed out. The statistical model of the DNA time-series and the structure of the DNA-ML algorithm provides a basis for future investigation and refinement of DNA sequencing techniques.
Related Concept Videos
 01:57
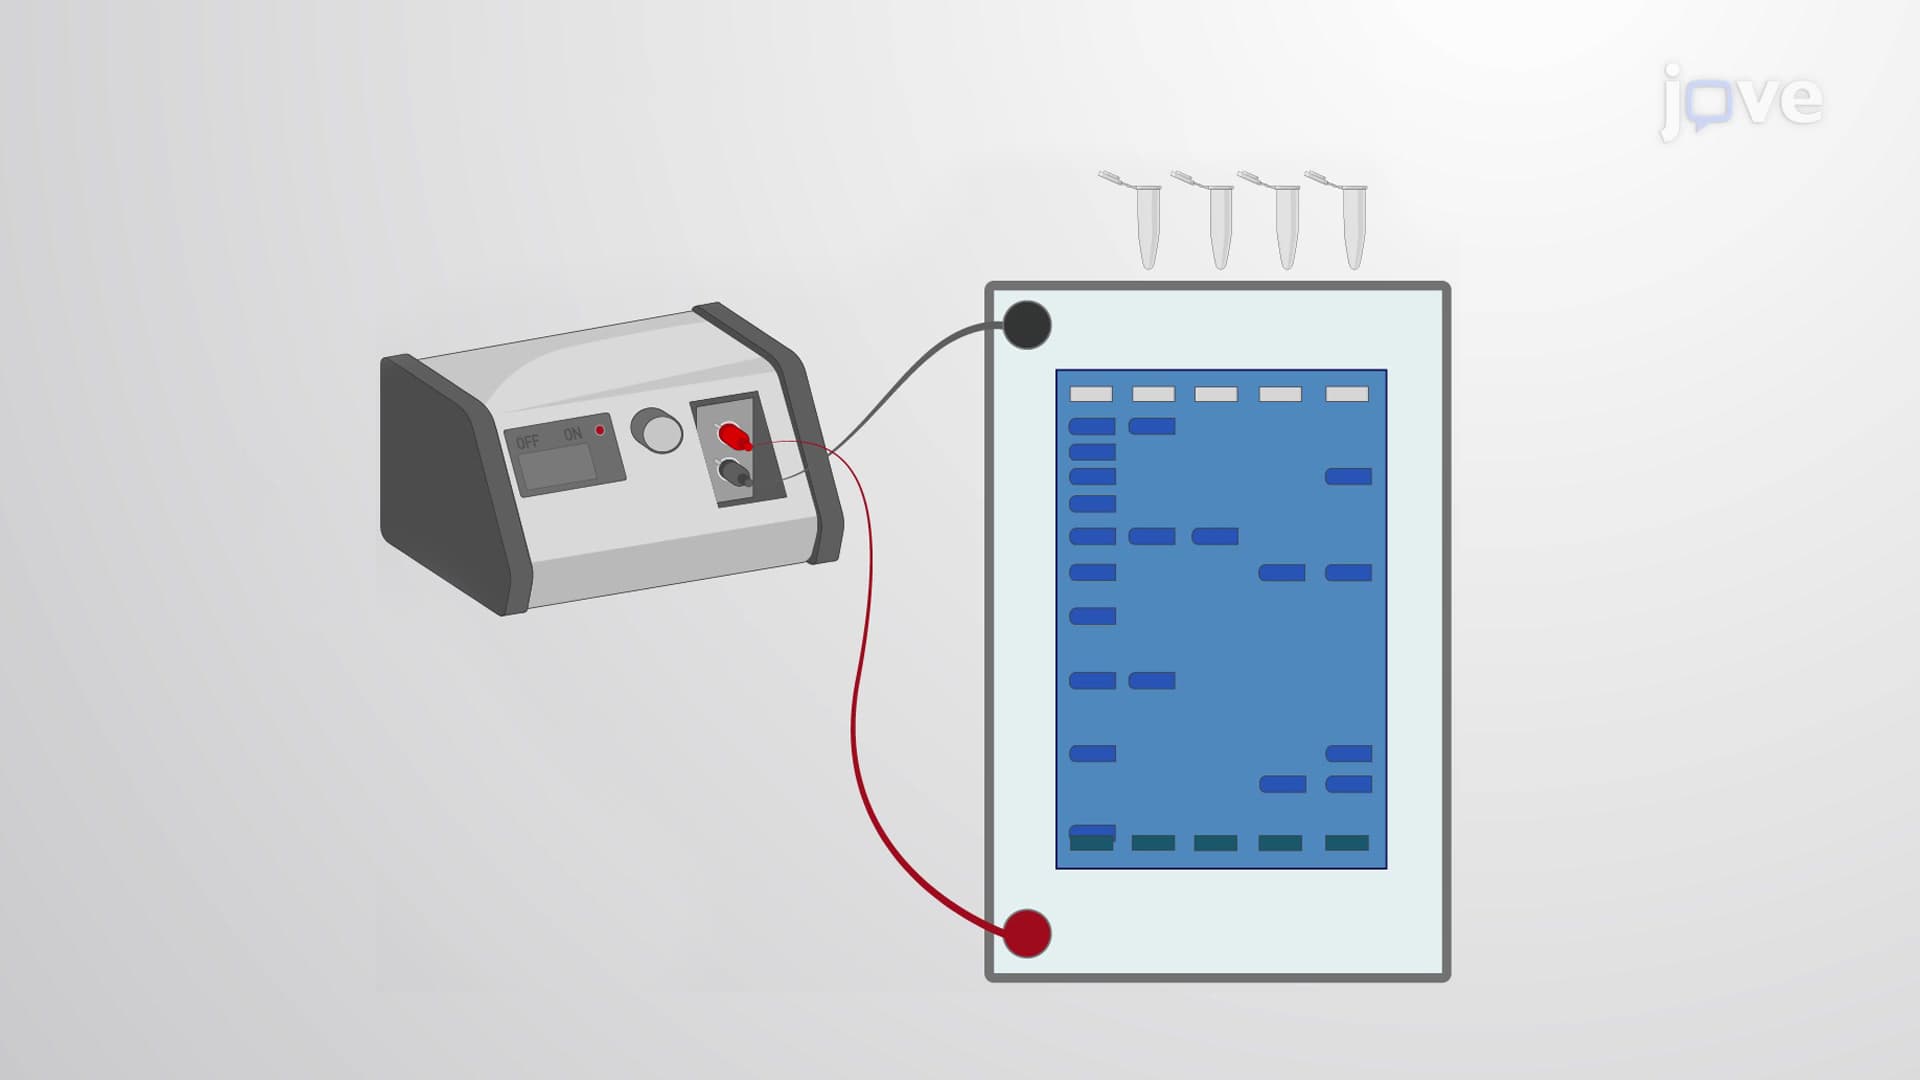
Sanger Sequencing
 03:21
RNA-seq
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while microarray-based...
 03:00
Next-generation Sequencing
Next-Generation Sequencing Methods
Although all next-generation methods use different technologies, they all share a set of standard features.
 01:05
Maxam-Gilbert Sequencing
Challenges of the Maxam-Gilbert Method
The...
 01:25
Nucleic Acid Structure
DNA Structure
DNA has a double-helix structure. The...
 03:36
Genome Annotation and Assembly