Efficiency of regression estimates for clustered data
Related Experiment Video
Updated: Jul 10, 2026
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
1Department of Dental Public Health Sciences, University of Washington, Box 357475, Seattle 98195-7475, Washington, USA.

Abstract:
Statistical methods for clustered data, such as generalized estimating equations (GEE) and generalized least squares (GLS), require selecting a correlation or convariance structure to specify the dependence between observations within a cluster. Valid regression estimates can be obtained that do not depend on correct specification of the true correlation, but inappropriate specifications can result in a loss of efficiency. We derive general expressions for the asymptotic relative efficiency of GEE and GLS estimators under nested correlation structures. Efficiency is shown to depend on the covariate distribution, the cluster sizes, the response variable correlation, and the regression parameters. The results demonstrate that efficiency is quite sensitive to the between- and within-cluster variation of the covariates, and provide useful characterizations of models for which upper and lower efficiency bounds are attained. Efficiency losses for simple working correlation matrices, such as independence, can be large even for small to moderate correlations and cluster sizes.

Related Concept Videos
 01:52
Regression Toward the Mean
 01:16
Estimating Population Mean with Known Standard Deviation
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate + error bound)
The...
 01:11
Regression Analysis
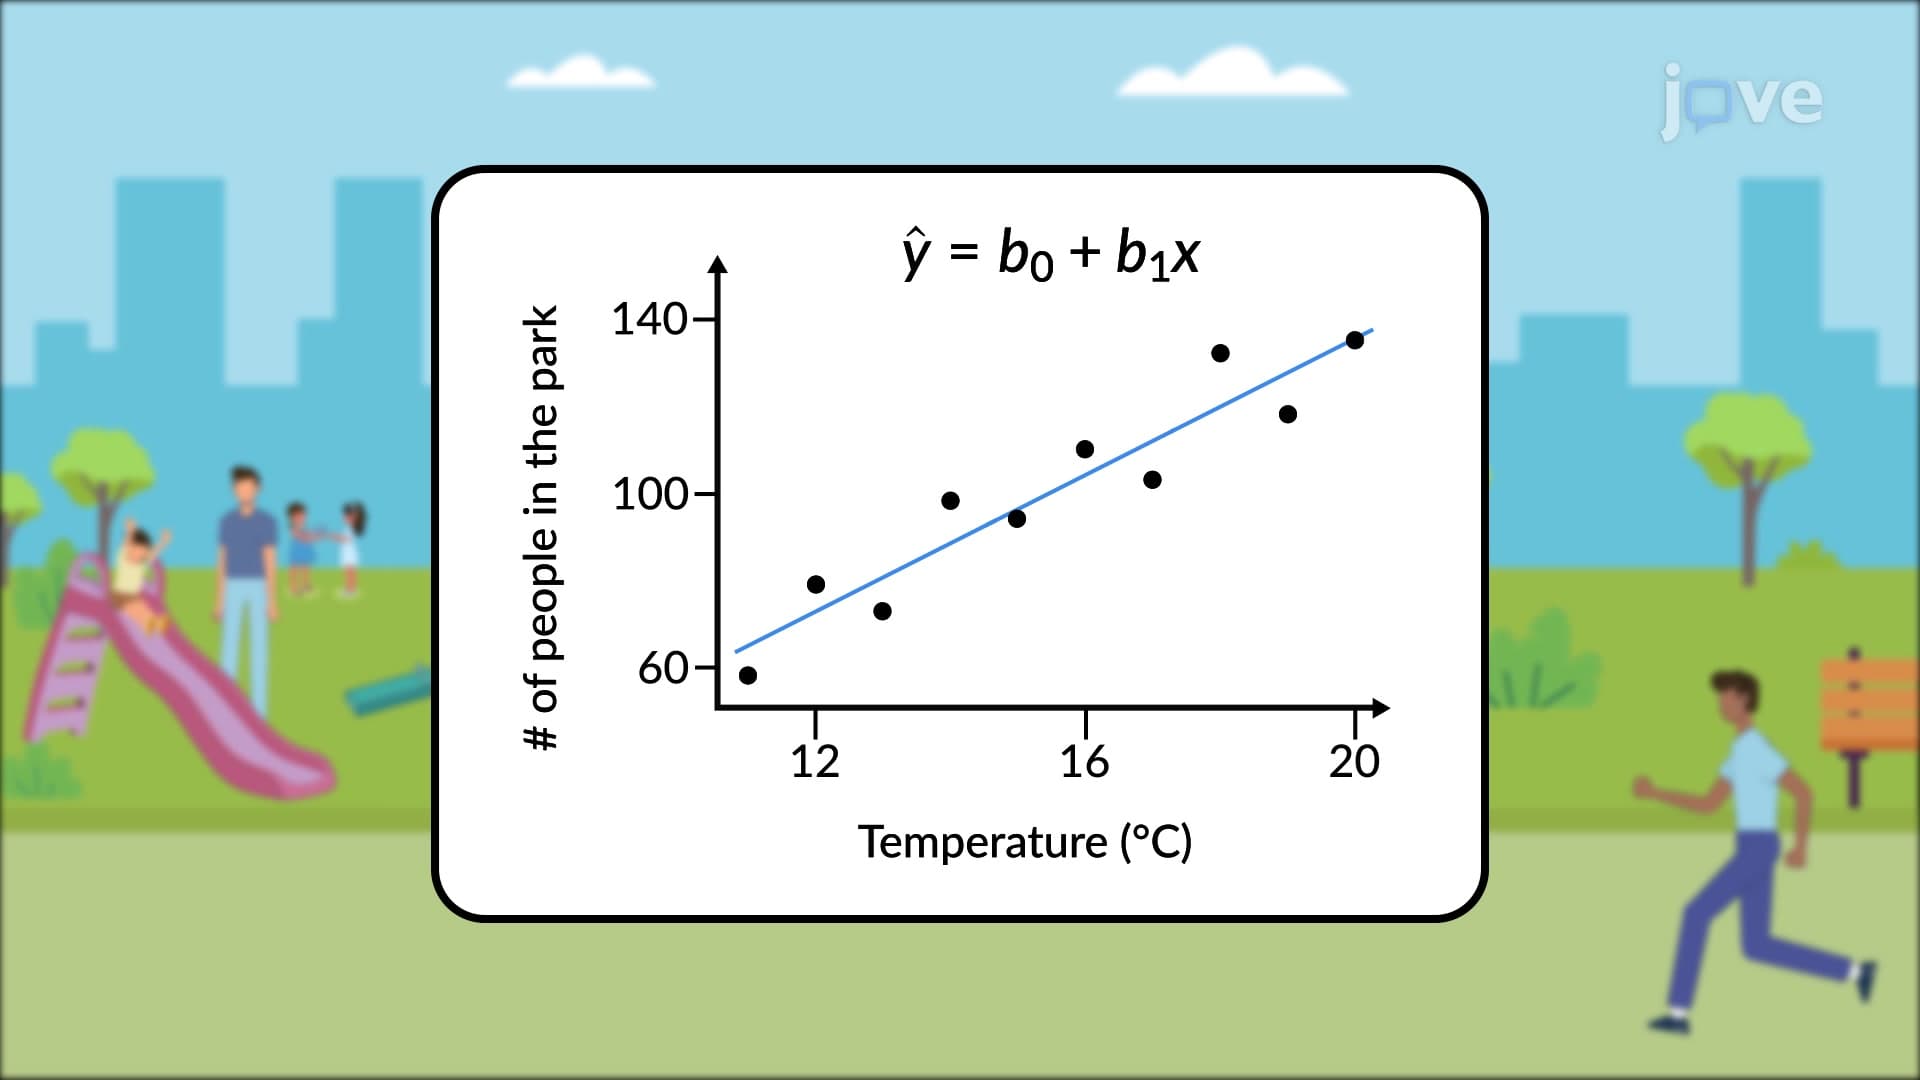
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...