Related Experiment Video
Updated: Aug 12, 2026


A Method of Trigonometric Modelling of Seasonal Variation Demonstrated with Multiple Sclerosis Relapse Data
Published on: December 9, 2015
Modelling covariance structure in the analysis of repeated measures data
R C Littell1, J Pendergast, R Natarajan
1Department of Statistics, Institute of Food and Agricultural Sciences, University of Florida, Gainesville, Florida 32611, USA. litell@stat.ufl.edu

Abstract:
The term 'repeated measures' refers to data with multiple observations on the same sampling unit. In most cases, the multiple observations are taken over time, but they could be over space. It is usually plausible to assume that observations on the same unit are correlated. Hence, statistical analysis of repeated measures data must address the issue of covariation between measures on the same unit. Until recently, analysis techniques available in computer software only offered the user limited and inadequate choices. One choice was to ignore covariance structure and make invalid assumptions. Another was to avoid the covariance structure issue by analysing transformed data or making adjustments to otherwise inadequate analyses. Ignoring covariance structure may result in erroneous inference, and avoiding it may result in inefficient inference. Recently available mixed model methodology permits the covariance structure to be incorporated into the statistical model. The MIXED procedure of the SAS((R)) System provides a rich selection of covariance structures through the RANDOM and REPEATED statements. Modelling the covariance structure is a major hurdle in the use of PROC MIXED. However, once the covariance structure is modelled, inference about fixed effects proceeds essentially as when using PROC GLM. An example from the pharmaceutical industry is used to illustrate how to choose a covariance structure. The example also illustrates the effects of choice of covariance structure on tests and estimates of fixed effects. In many situations, estimates of linear combinations are invariant with respect to covariance structure, yet standard errors of the estimates may still depend on the covariance structure.

Related Concept Videos
 01:17
Two-Way ANOVA
The two-way ANOVA analysis initially begins by stating the null hypothesis that there is an interaction effect between the two factors of a dataset. This effect can be visualized using line segments formed by joining the means for...
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:12
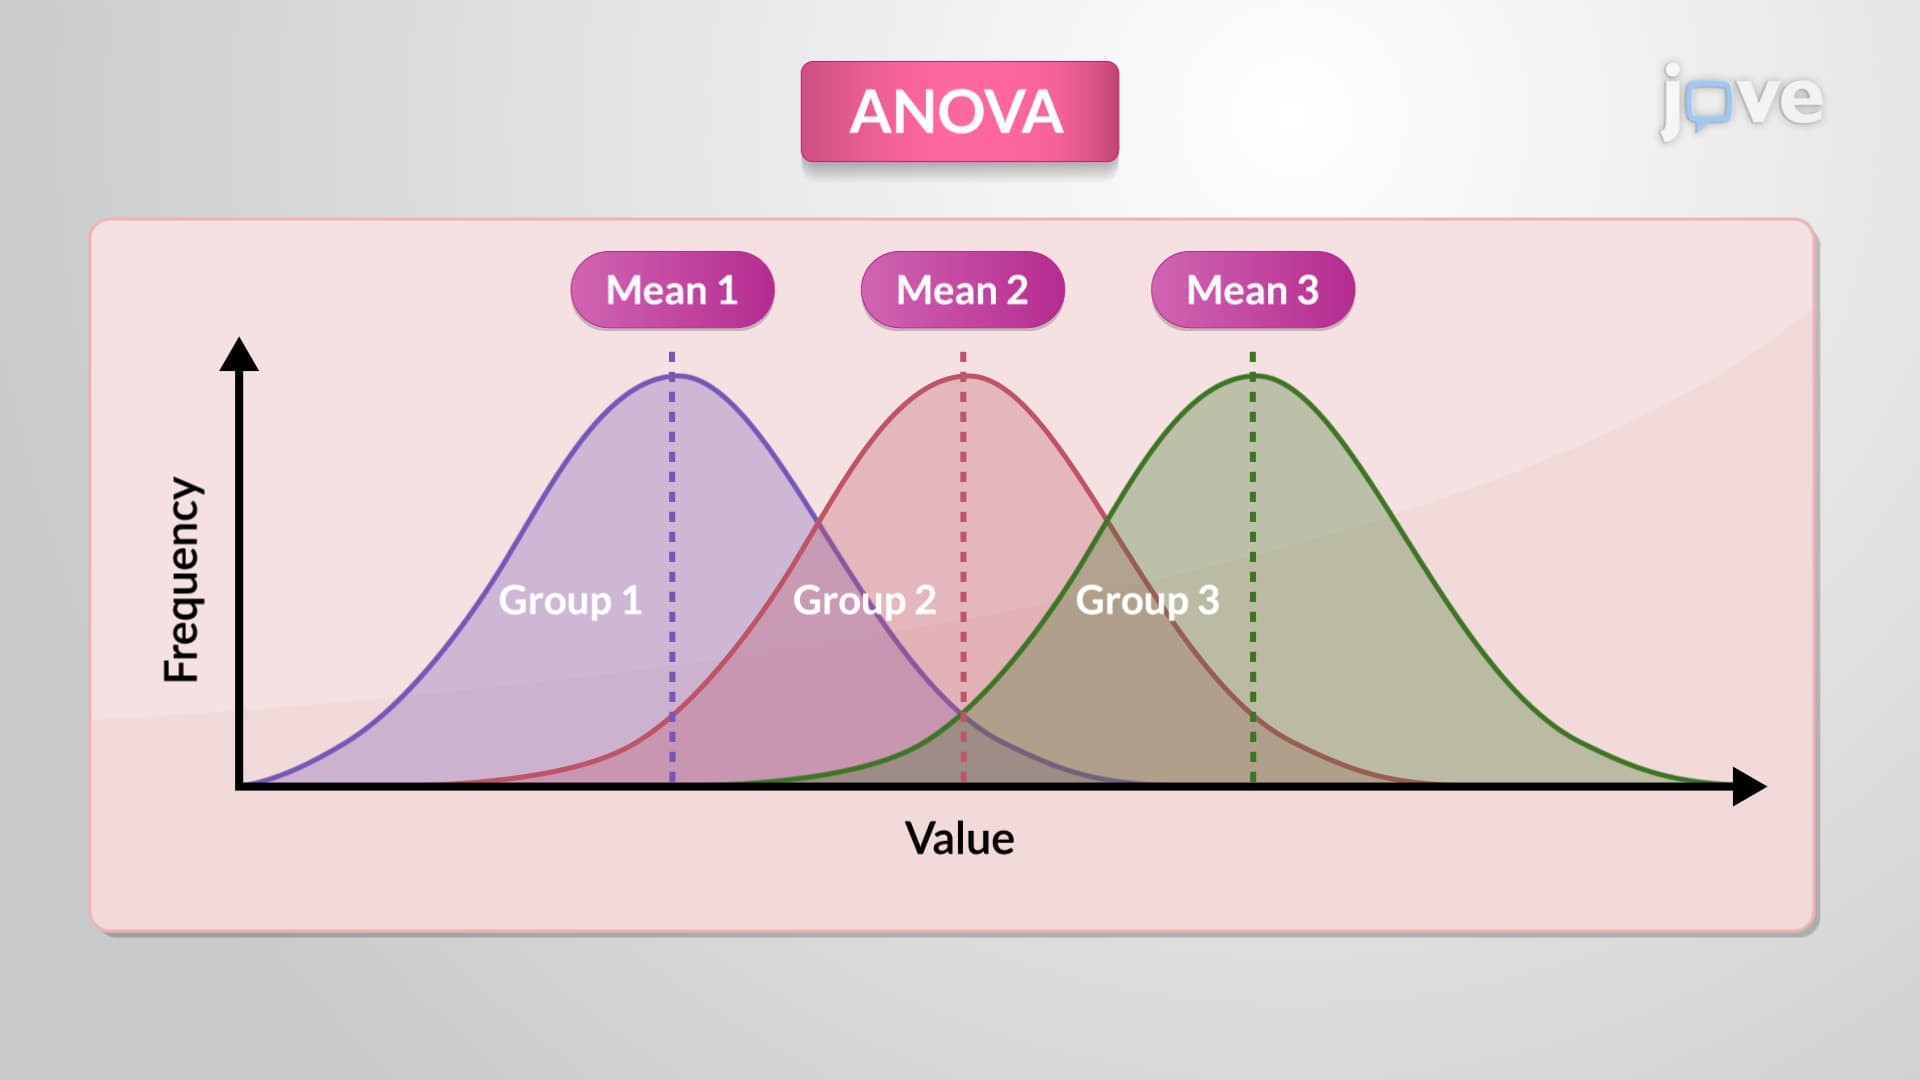
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares the...
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:15
Bioequivalence Experimental Study Designs: Repeated Measures, Cross-Over, Carry-Over, and Latin Square Designs
 01:21
Friedman Two-way Analysis of Variance by Ranks