Related Experiment Video
Updated: Oct 15, 2026
A Knowledge Graph Approach to Elucidate the Role of Organellar Pathways in Disease via Biomedical Reports
Published on: October 13, 2023
EDGAR: extraction of drugs, genes and relations from the biomedical literature
T C Rindflesch1, L Tanabe, J N Weinstein
1Lister Hill Center, National Library of Medicine, Bethesda, MD 20894, USA. tcr@lhc.nlm.nih.gov

Abstract:
EDGAR (Extraction of Drugs, Genes and Relations) is a natural language processing system that extracts information about drugs and genes relevant to cancer from the biomedical literature. This automatically extracted information has remarkable potential to facilitate computational analysis in the molecular biology of cancer, and the technology is straightforwardly generalizable to many areas of biomedicine. This paper reports on the mechanisms for automatically generating such assertions and on a simple application, conceptual clustering of documents. The system uses a stochastic part of speech tagger, generates an underspecified syntactic parse and then uses semantic and pragmatic information to construct its assertions. The system builds on two important existing resources: the MEDLINE database of biomedical citations and abstracts and the Unified Medical Language System, which provides syntactic and semantic information about the terms found in biomedical abstracts.
More Related Videos
Related Concept Videos
 01:29
Pharmacogenomics: Identification of New Drug Targets
 01:29
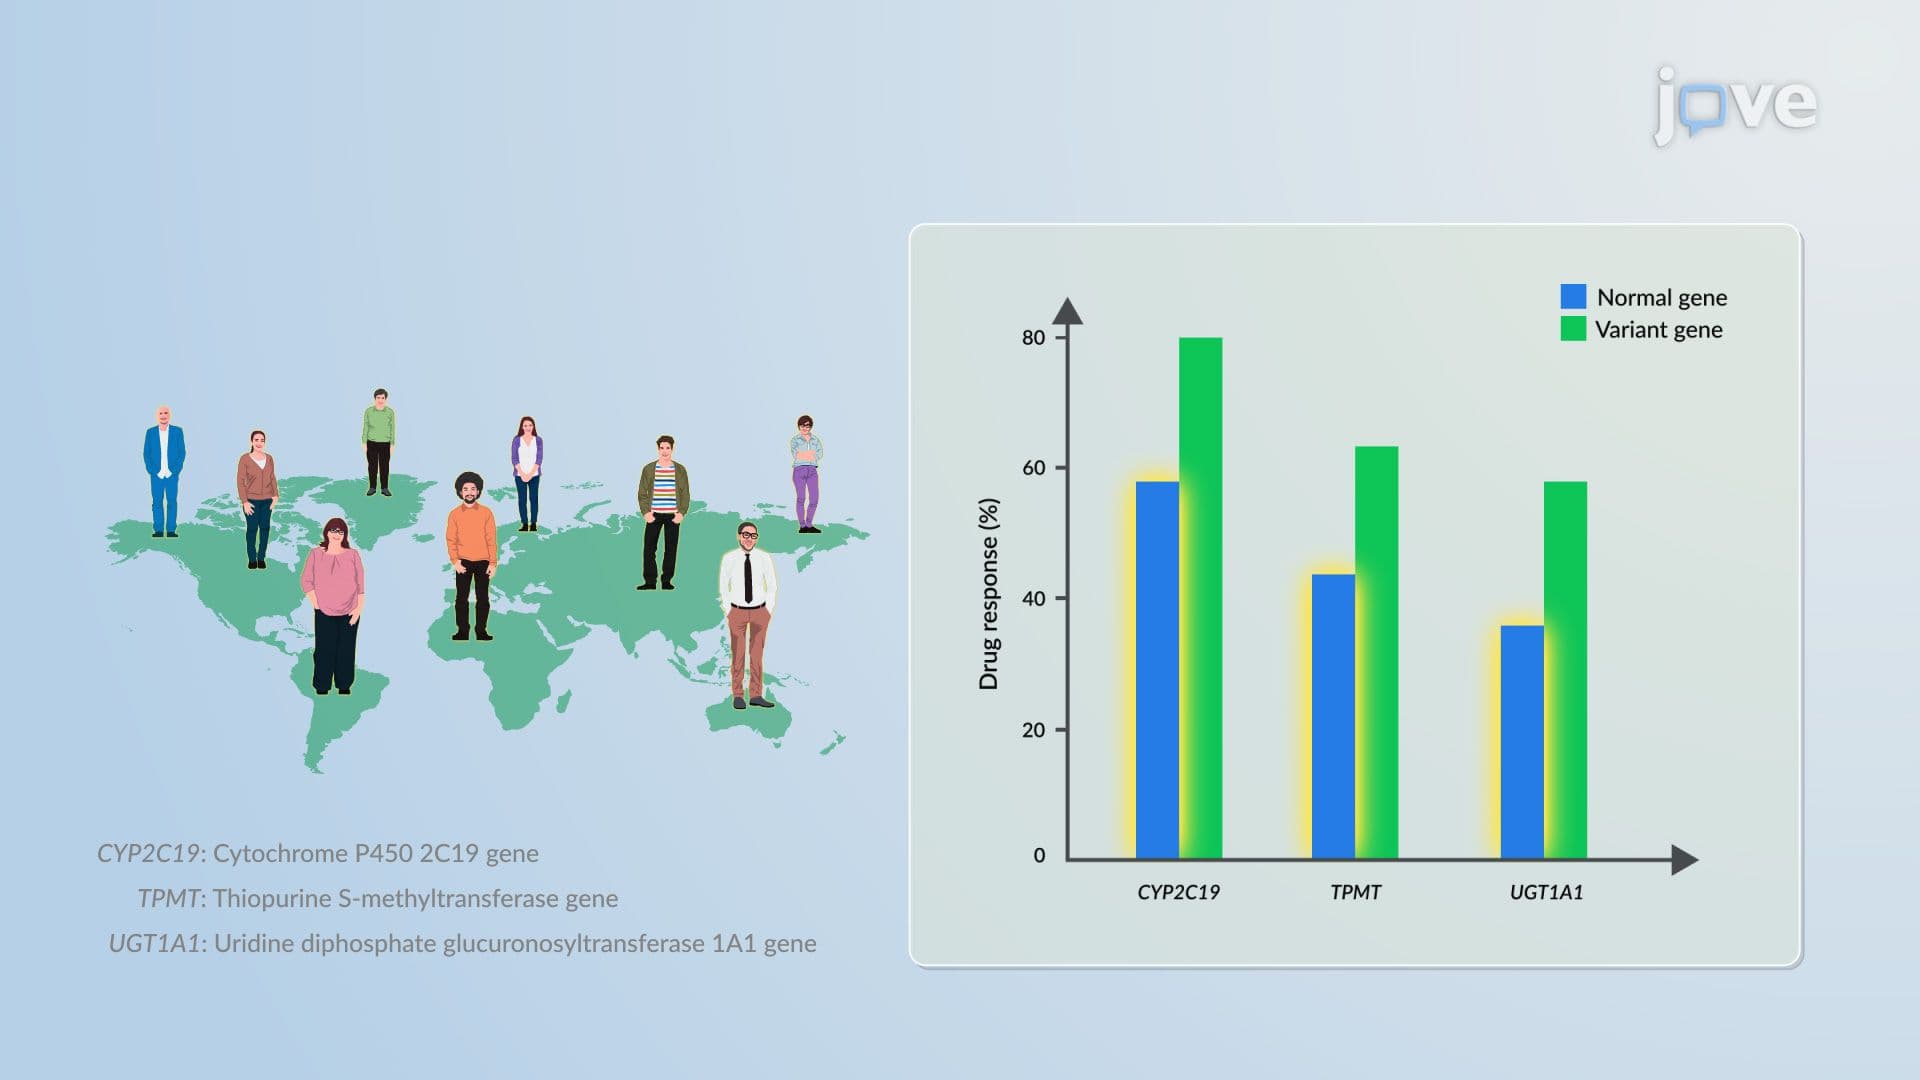
Pharmacogenetics and Pharmacogenomics: Overview
 02:46
Genetic Screens
Forward genetic screens
Forward or “classical” genetic screens involve creating random mutations in an organism’s DNA using radiation, mutagens, or insertion of additional bases, which result in visible changes...
 02:54
Evolutionary Relationships through Genome Comparisons
 01:27
Pharmacogenetics of Drug Metabolism: Overview
 02:02
Genomics