Analyzing k (2 x 2) tables under cluster sampling
Related Experiment Video
Updated: Aug 14, 2026
Infinium Assay for Large-scale SNP Genotyping Applications
Published on: November 19, 2013
1Division of Biostatistics, Columbia School of Public Health, New York, New York 10032, USA. melissa.begg@columbia.edu

Abstract:
In many data analytic applications, such as ophthalmologic, longitudinal, or periodontal studies, multiple observations are recorded over several sites (or timepoints) within the same subject, bringing about dependence between measurements. This correlation, in turn, precludes the use of standard statistical methods that assume independence between outcome measurements. For example, the Mantel-Haenszel statistic, used to assess association between a binary outcome and a binary exposure while adjusting for a categorical covariate, does not follow the usual chi-squared distribution under the null hypothesis when there is correlation between observations. A modified Mantel-Haenszel procedure, which makes adjustment for dependence, is proposed. No particular correlation structure is assumed for responses within a cluster. This closed-form adjustment stems from Liang and Zeger's (1986, Biometrika 73, 13-22) generalized estimating equations approach for clustered data. The difference between this tabular (i.e., noniterative) technique and many earlier tabular methods is that the current method allows for consideration of site-specific exposure and covariate information. An example from a periodontal research study illustrates application of the method.
Related Concept Videos
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:29
Contingency Table
 01:21
Introduction to Test of Independence
The test statistic for a test of independence is similar to that of a goodness-of-fit test:
 01:08
Determination of Expected Frequency
 01:19
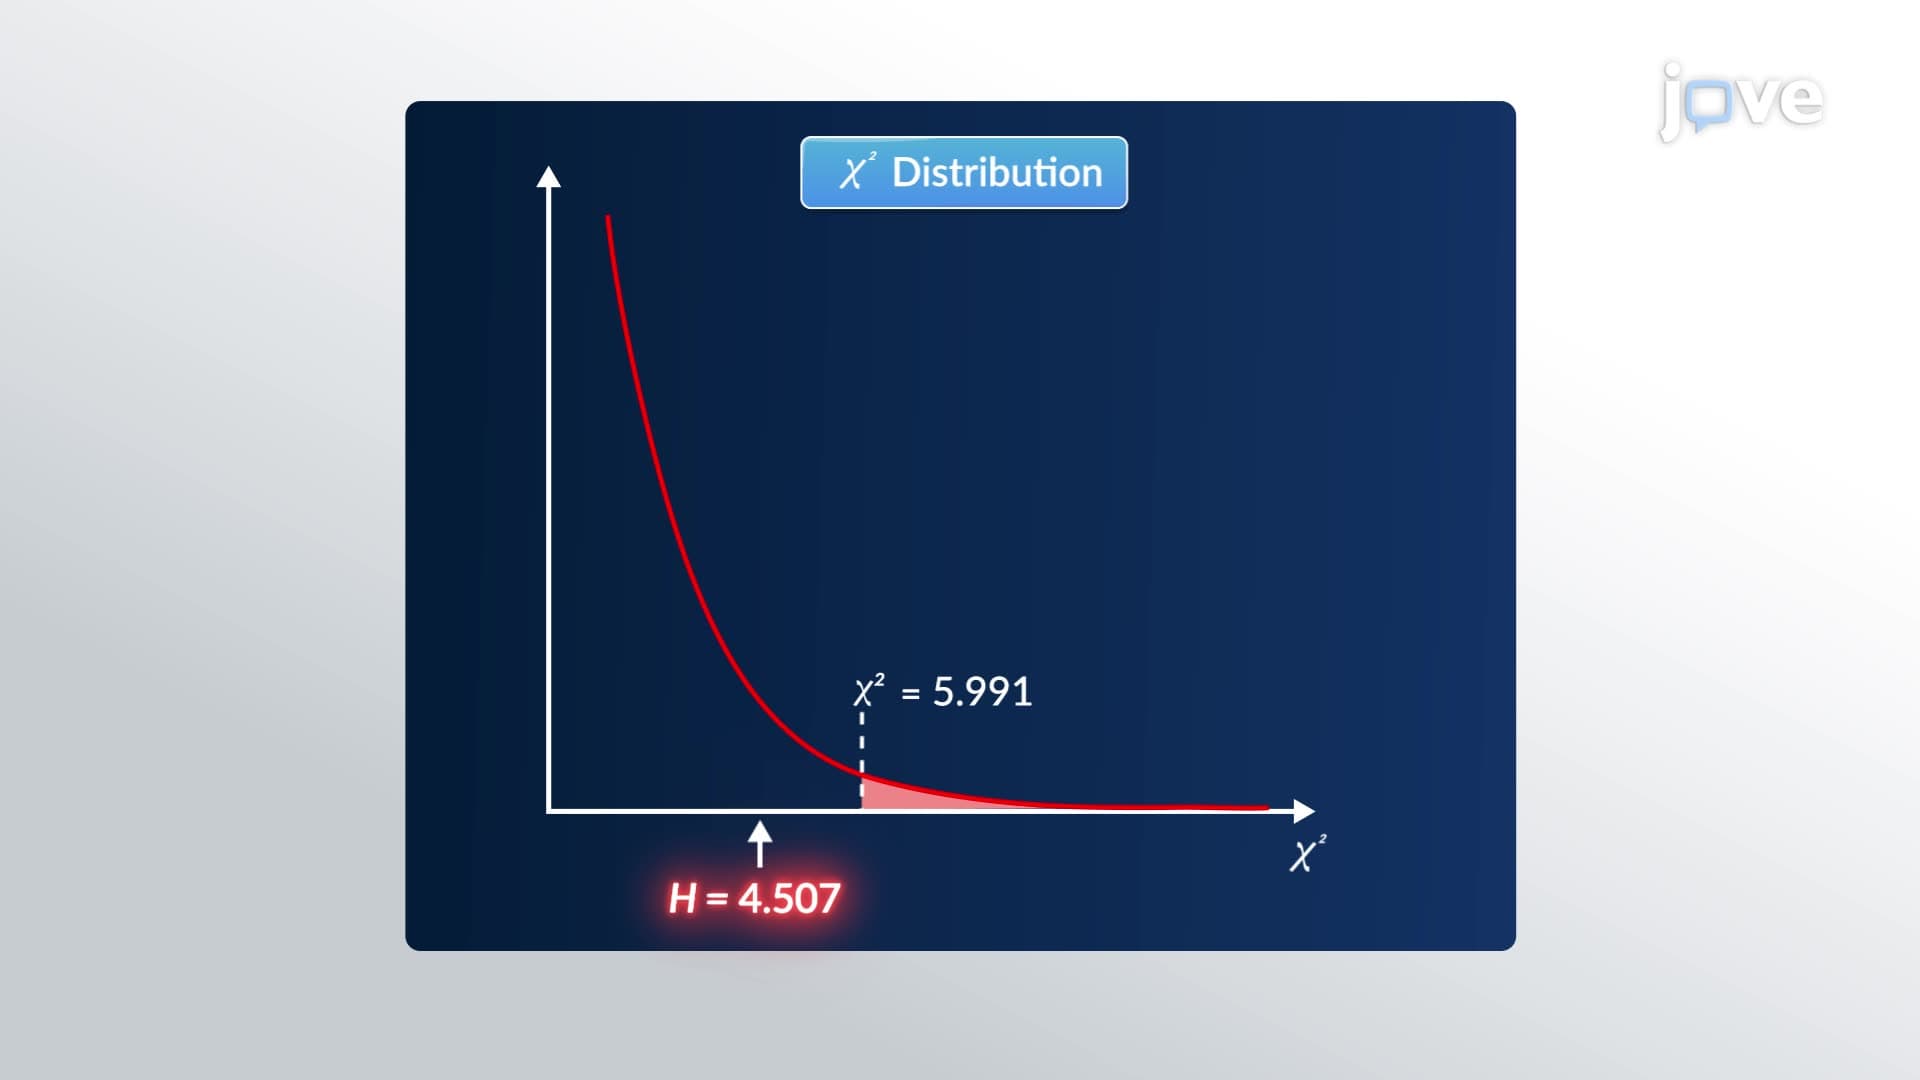
Kruskal-Wallis Test
 01:23
Sampling Plans
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...