Parameterization of multivariate random effects models for categorical data
Related Experiment Video
Updated: Aug 18, 2026

A Method of Trigonometric Modelling of Seasonal Variation Demonstrated with Multiple Sclerosis Relapse Data
Published on: December 9, 2015
1Department of Biostatistics and Computing, Institute of Psychiatry, London, UK. spaksrh@iop.kcl.ac.uk

Abstract:
Alternative parameterizations and problems of identification and estimation of multivariate random effects models for categorical responses are investigated. The issues are illustrated in the context of the multivariate binomial logit-normal (BLN) model introduced by Coull and Agresti (2000, Biometrics 56, 73-80). We demonstrate that the BLN model is poorly identified unless proper restrictions are imposed on the parameters. Moreover, estimation of BLN models is unduly computationally complex. In the first application considered by Coull and Agresti, an identification problem results in highly unstable, highly correlated parameter estimates and large standard errors. A probit-normal version of the specified BLN model is demonstrated to be underidentified, whereas the BLN model is empirically underidentified. Identification can be achieved by constraining one of the parameters. We show that a one-factor probit model is equivalent to the probit version of the specified BLN model and that a one-factor logit model is empirically equivalent to the BLN model. Estimation is greatly simplified by using a factor model.


Related Concept Videos
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:12
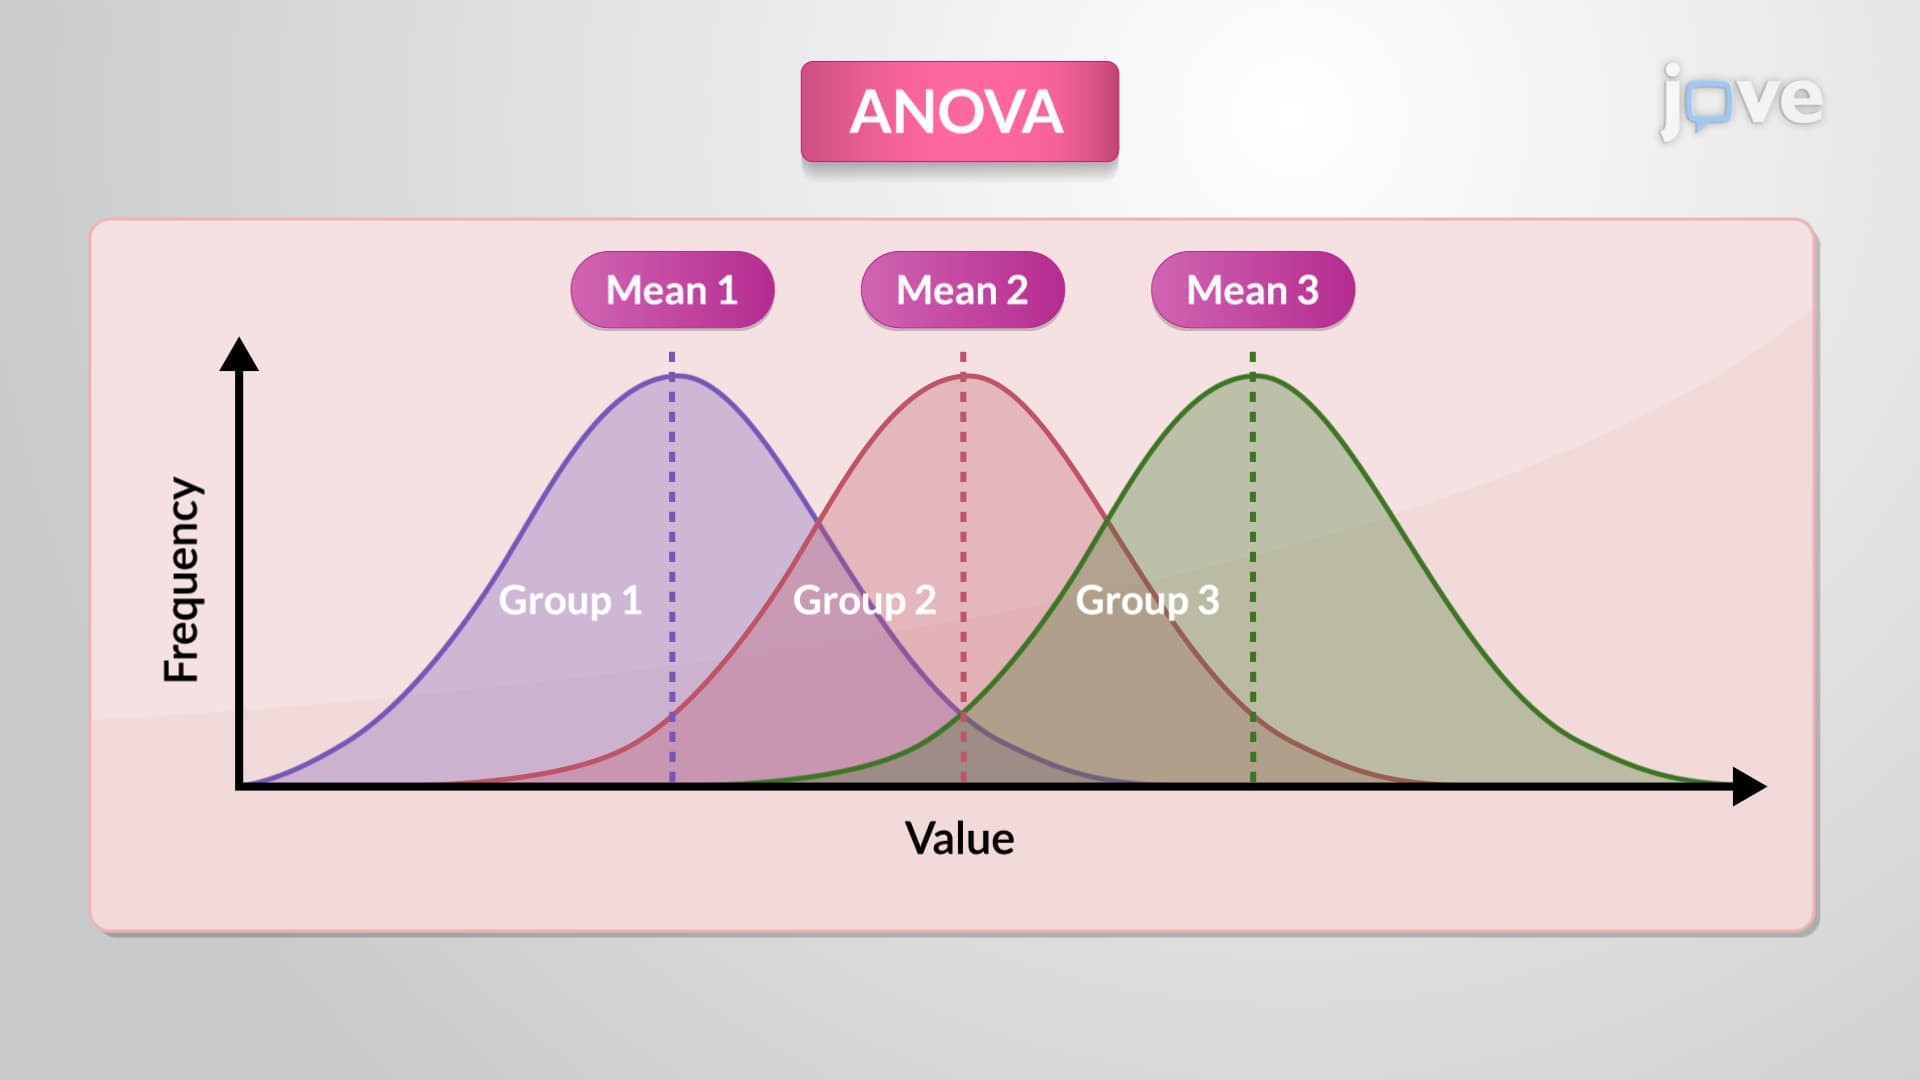
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares the...
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...