Novel alleles of the D16S752 polymorphic genetic marker linked to E-cadherin gene--a potential population marker

N Pećina-Slaus1, K Gall-Troselj, S Kapitanović

  • 1Department of Biology, School of Medicine, University of Zagreb, Croatia.

Related Concept Videos

Structure of Cadherins01:25

Structure of Cadherins

The cadherins were one of the first cell adhesion molecules discovered; the term “cadherins”   is based on their calcium-dependent adhering properties. The first cadherins discovered on the epithelial, neuronal, and placental cells were named E-cadherin, P-cadherin, and N-cadherin, respectively. These classical cadherins share sequence and structural similarities. Other cadherins, including those involved in cell signaling, are grouped into non-classical cadherins. This diversity of cadherins...
Genome-wide Association Studies-GWAS01:11

Genome-wide Association Studies-GWAS

Genome-wide association studies or GWAS are used to identify whether common SNPs are associated with certain diseases. Suppose specific SNPs are more frequently observed in individuals with a particular disease than those without the disease. In that case, those SNPs are said to be associated with the disease. Chi-square analysis is performed to check the probability of the allele likely to be associated with the disease.
GWAS does not require the identification of the target gene involved in...
Exon Recombination02:32

Exon Recombination

The evolution of new genes is critical for speciation. Exon recombination, also known as exon shuffling or domain shuffling, is an important means of new gene formation. It is observed across vertebrates, invertebrates, and in some plants such as potatoes and sunflowers. During exon recombination, exons from the same or different genes recombine and produce new exon-intron combinations, which might evolve into new genes. 
Exon shuffling follows “splice frame rules.” Each exon has three reading...
Comparing Copy Number Variations and SNPs02:26

Comparing Copy Number Variations and SNPs

Sequencing of the human genome has opened up several best-kept secrets of the genome. Scientists have identified thousands of genome variations that exist within a population. These variations can be a single nucleotide or a larger chromosomal variation.
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
Single Nucleotide Polymorphisms-SNPs01:05

Single Nucleotide Polymorphisms-SNPs
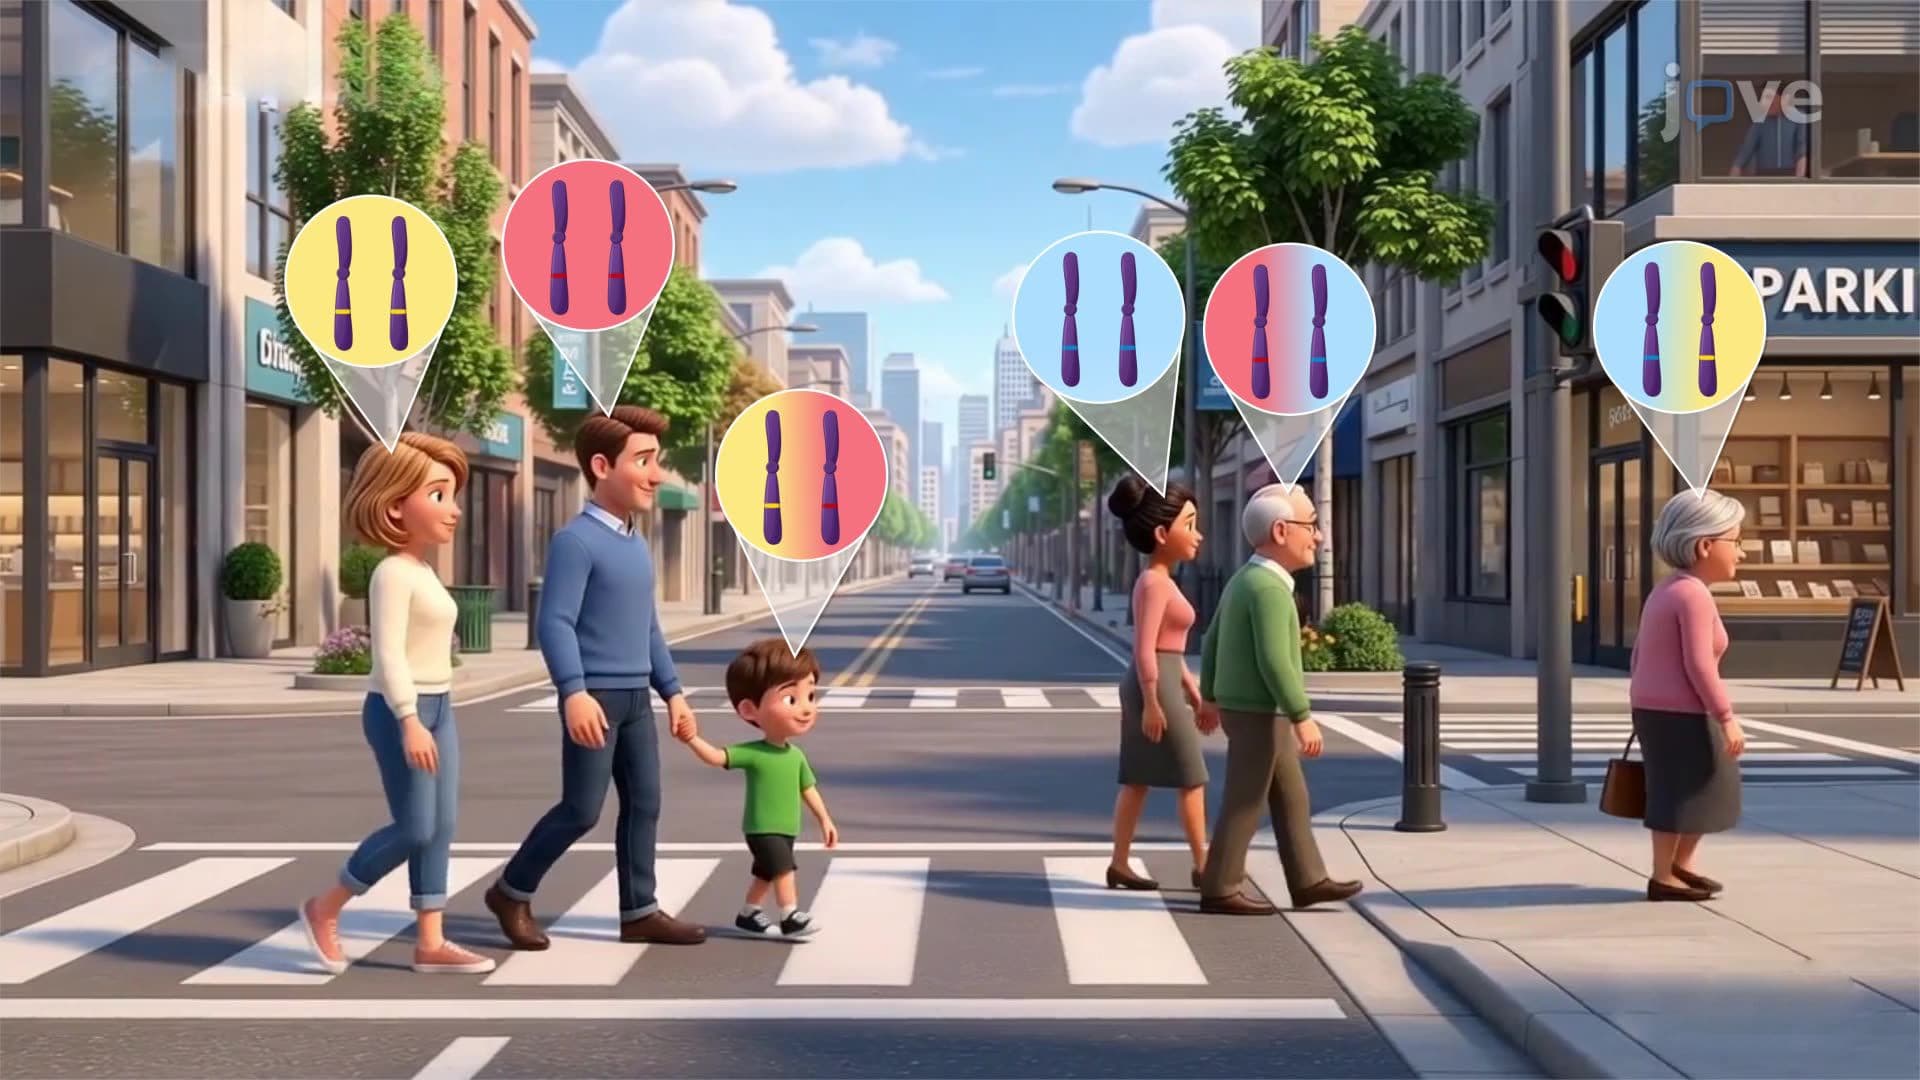
A single nucleotide polymorphism or SNP is a single nucleotide variation at a specific genomic position in a large population. It is the most prevalent type of sequence variation found in the human genome. Point mutations that occur in more than 1% of the population qualify as SNPs. These are present once every 1000 nucleotides on an average in the human genome. Replacement of a purine with another purine (A/G) or a pyrimidine with another pyrimidine (C/T) is known as a transition. In contrast,...
Multiple Allele Traits02:19

Multiple Allele Traits

For the same gene multiple alleles can interact to influence phenotypes like the shape and protein composition of an individual cells.By studying allele interactions on the molecular and cellular levels researchers can understand the resulting phenotypes and complications of human conditions like sickle cell trait, improving treatment.The ABO blood group system is a common example of multiple alleles in humans. This system includes three alleles called IA, IB, and i alleles, which combine in...