Related Experiment Video
Updated: Sep 27, 2026

'Boden Food Plate': Novel Interactive Web-based Method for the Assessment of Dietary Intake
Published on: September 18, 2018
Estimation of usual intakes: What We Eat in America-NHANES
Johanna Dwyer1, Mary Frances Picciano, Daniel J Raiten
1Agricultural Research Service, U.S. Department of Agriculture, Washington, DC 20250, USA.

Abstract:
Usual intakes of nutrients are reliable indicators for making associations between diet and health or disease risks. Estimates of consumption of specific foods and food groups are also important for evaluating the progress in meeting key objectives in such national public health initiatives as Healthy People 2010. Reliable and valid estimates of intakes of particular foods, food ingredients, dietary supplements and other bioactive substances are also needed for dietary assessment and regulatory purposes. The ability to generate useful estimates of these constituents often requires much larger sample sizes than are needed for estimating nutrient intakes. Statistical methods recommended by the National Academy of Sciences are described that provide estimates of distributions of usual nutrient intakes and permit dietary assessment and planning at the population level. Statistical and modeling approaches for estimating intakes of foods, dietary supplements and other bioactive substances are also summarized. Based on the deliberations of discussion groups consisting of members of key stakeholder groups involved in the planning, implementation and utilization of national survey data, a high priority was placed on the need for more research to determine the best approaches for applying these methods to dietary data in the integrated What We Eat in America-National Health and Nutrition Examination Survey (NHANES).
Related Concept Videos
 01:06
What are Estimates?
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such as the mean,...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:26
Distributions to Estimate Population Parameter
 01:10
Central Tendency: Analysis
The mean is one such measure, calculated by totaling all values in a dataset and dividing by the number of values. For instance, the mean blood pressure reading (120, 130, 140, 150) would be 135. However, the mean can be affected by extreme values or outliers.
The median, another measure,...
 02:16
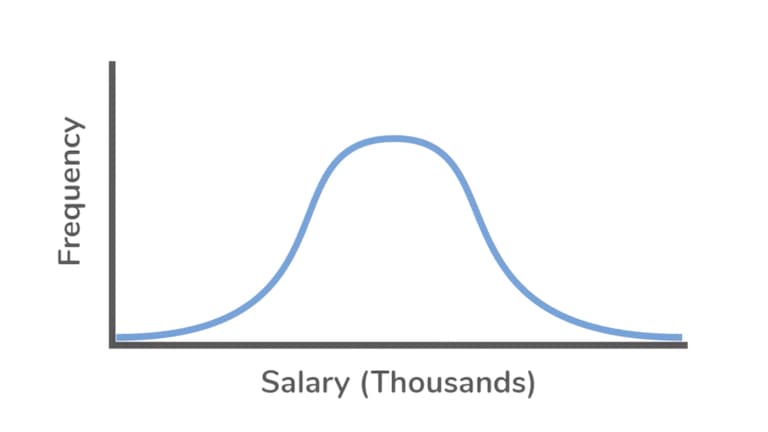
Measures of Central Tendency
 01:15
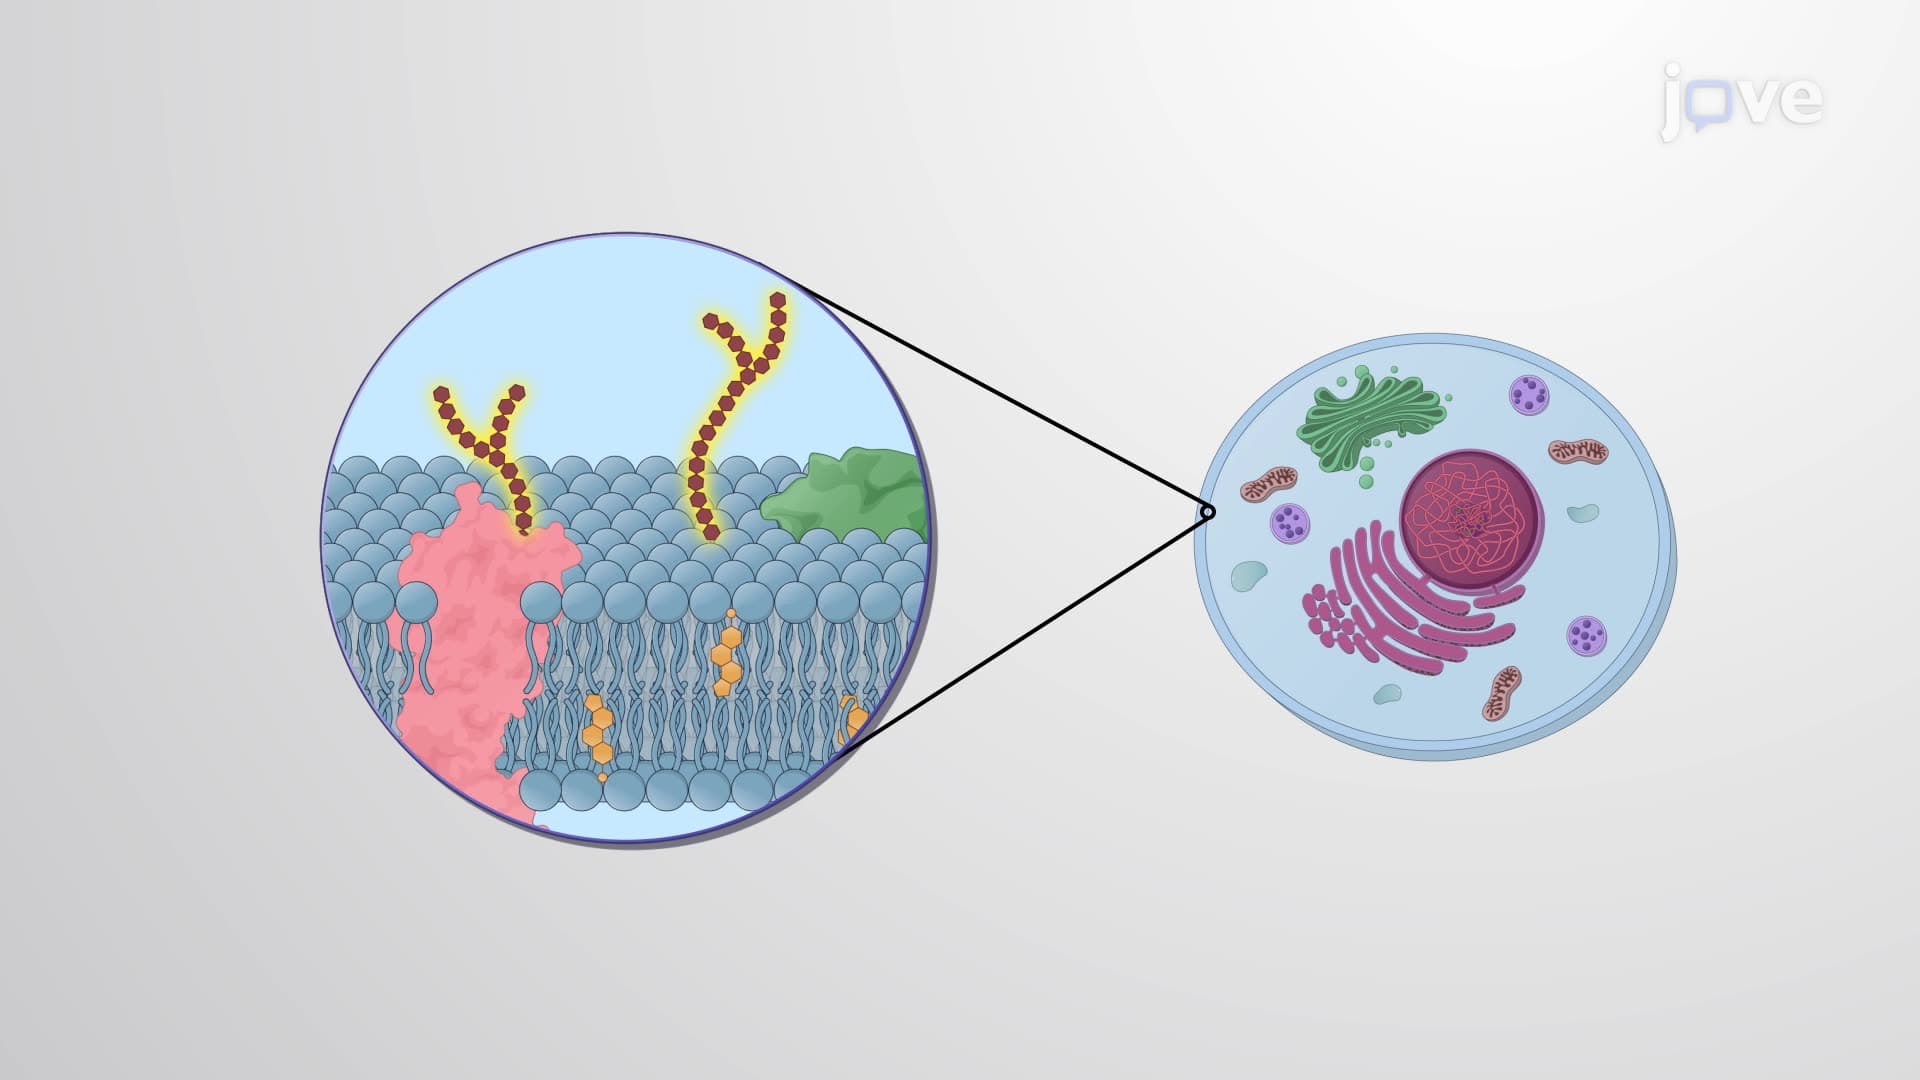
Carbohydrates: Dietary Sources and Requirements