Obtaining maximal concatenated phylogenetic data sets from large sequence databases
Related Experiment Video
Updated: Sep 25, 2026
Using Phylogenetic Analysis to Investigate Eukaryotic Gene Origin
Published on: August 14, 2018
Michael J Sanderson1, Amy C Driskell, Richard H Ree
1Section of Evolution and Ecology, University of California, Davis, USA. mjsanderson@ucdavis.edu

Abstract:
To improve the accuracy of tree reconstruction, phylogeneticists are extracting increasingly large multigene data sets from sequence databases. Determining whether a database contains at least k genes sampled from at least m species is an NP-complete problem. However, the skewed distribution of sequences in these databases permits all such data sets to be obtained in reasonable computing times even for large numbers of sequences. We developed an exact algorithm for obtaining the largest multigene data sets from a collection of sequences. The algorithm was then tested on a set of 100,000 protein sequences of green plants and used to identify the largest multigene ortholog data sets having at least 3 genes and 6 species. The distribution of sizes of these data sets forms a hollow curve, and the largest are surprisingly small, ranging from 62 genes by 6 species, to 3 genes by 65 species, with more symmetrical data sets of around 15 taxa by 15 genes. These upper bounds to sequence concatenation have important implications for building the tree of life from large sequence databases.

Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 03:21
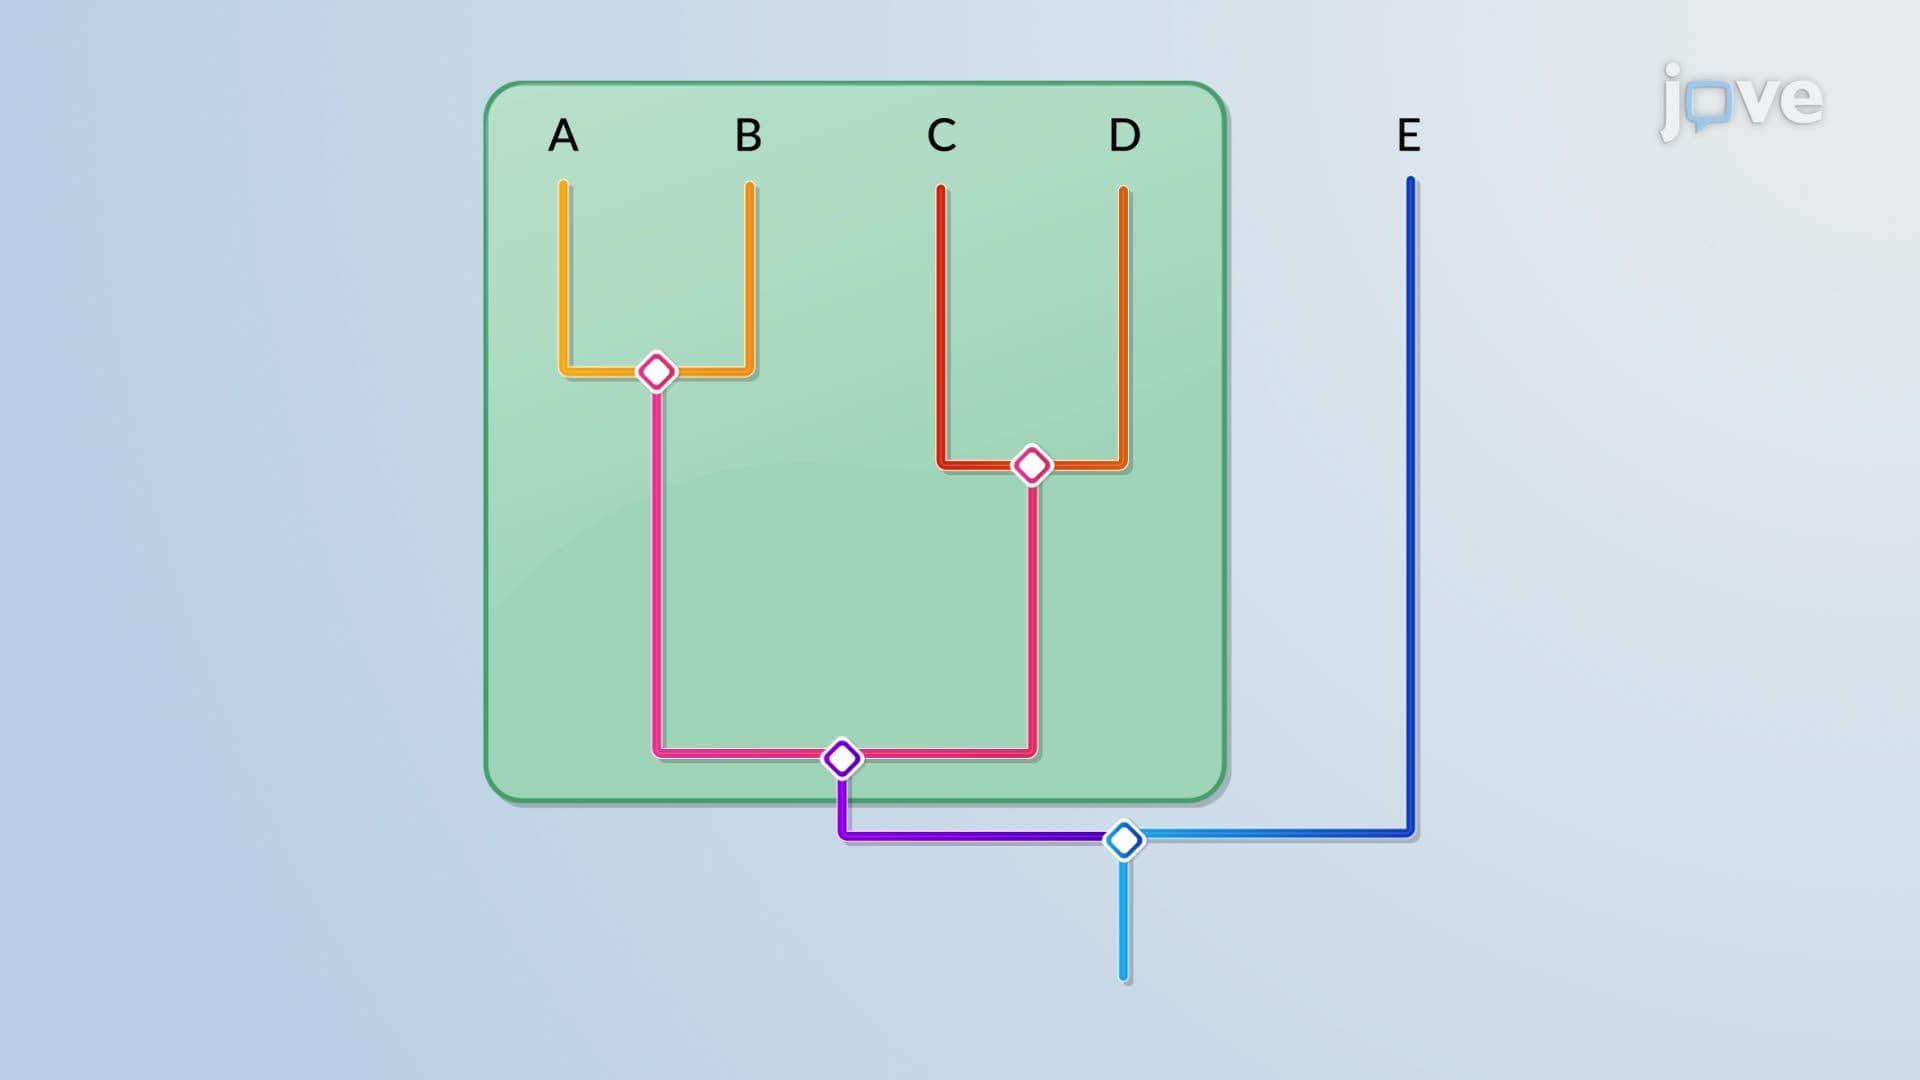
Phylogenetic Trees
03:21Phylogenetic Trees
 01:28
Microbial Phylogeny
 02:51
Multi-species Conserved Sequences
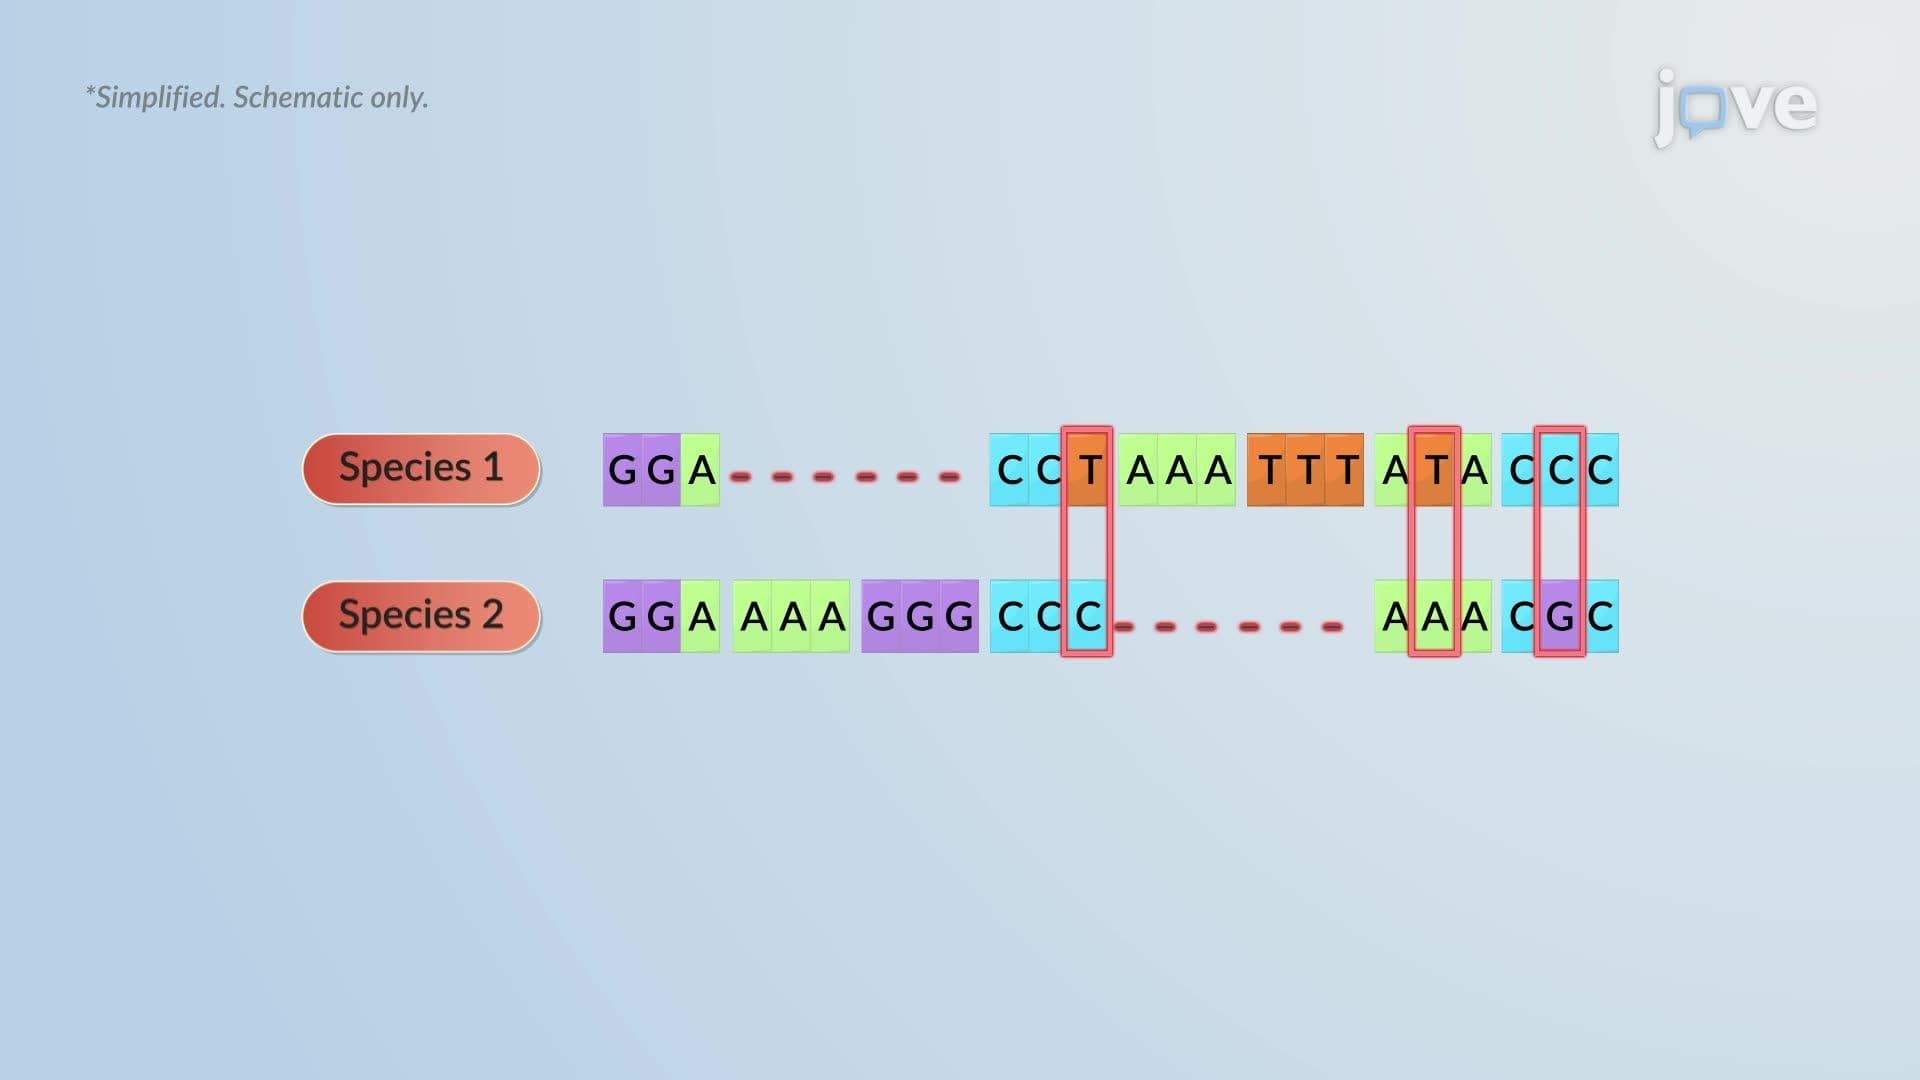
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...
 01:05
Maxam-Gilbert Sequencing
Challenges of the Maxam-Gilbert Method
The...