Related Experiment Video
Updated: Sep 25, 2026

In vivo Application of the REMOTE-control System for the Manipulation of Endogenous Gene Expression
Published on: March 29, 2019
Importance of a single base pair for discrimination between intron-containing and intronless alleles by endonuclease
David R Edgell1, Matthew J Stanger, Marlene Belfort
1Molecular Genetics Program, Wadsworth Center, New York State Department of Health, P.O. Box 22002, Albany, NY 12201-2002, USA. edgell@wadsworth.org

Abstract:
Homing endonucleases initiate mobility of their host group I introns by binding to and cleaving lengthy recognition sequences that are typically centered on the intron insertion site (IS) of intronless alleles. Because the intron interrupts the endonucleases' recognition sequence, intron-containing alleles are immune to cleavage by their own endonuclease. I-TevI and I-BmoI are related GIY-YIG endonucleases that bind a homologous stretch of thymidylate synthase (TS)-encoding DNA but use different strategies to distinguish intronless from intron-containing substrates. I-TevI discriminates between substrates at the level of DNA binding, as its recognition sequence is centered on the intron IS. I-BmoI, in contrast, possesses a very asymmetric recognition sequence with respect to the intron IS, binds both intron-containing and intronless TS-encoding substrates, but efficiently cleaves only intronless substrate. Here, we show that I-BmoI is extremely tolerant of multiple substitutions around its cleavage sites and has a low specific activity. However, a single G-C base pair, at position -2 of a 39-base pair recognition sequence, is a major determinant for cleavage efficiency and distinguishes intronless from intron-containing alleles. Strikingly, this G-C base pair is universally conserved in phylogenetically diverse TS-coding sequences; this finding suggests that I-BmoI has evolved exquisite cleavage requirements to maximize the potential to spread to variant intronless alleles, while minimizing cleavage at its own intron-containing allele.
Related Concept Videos
 01:11
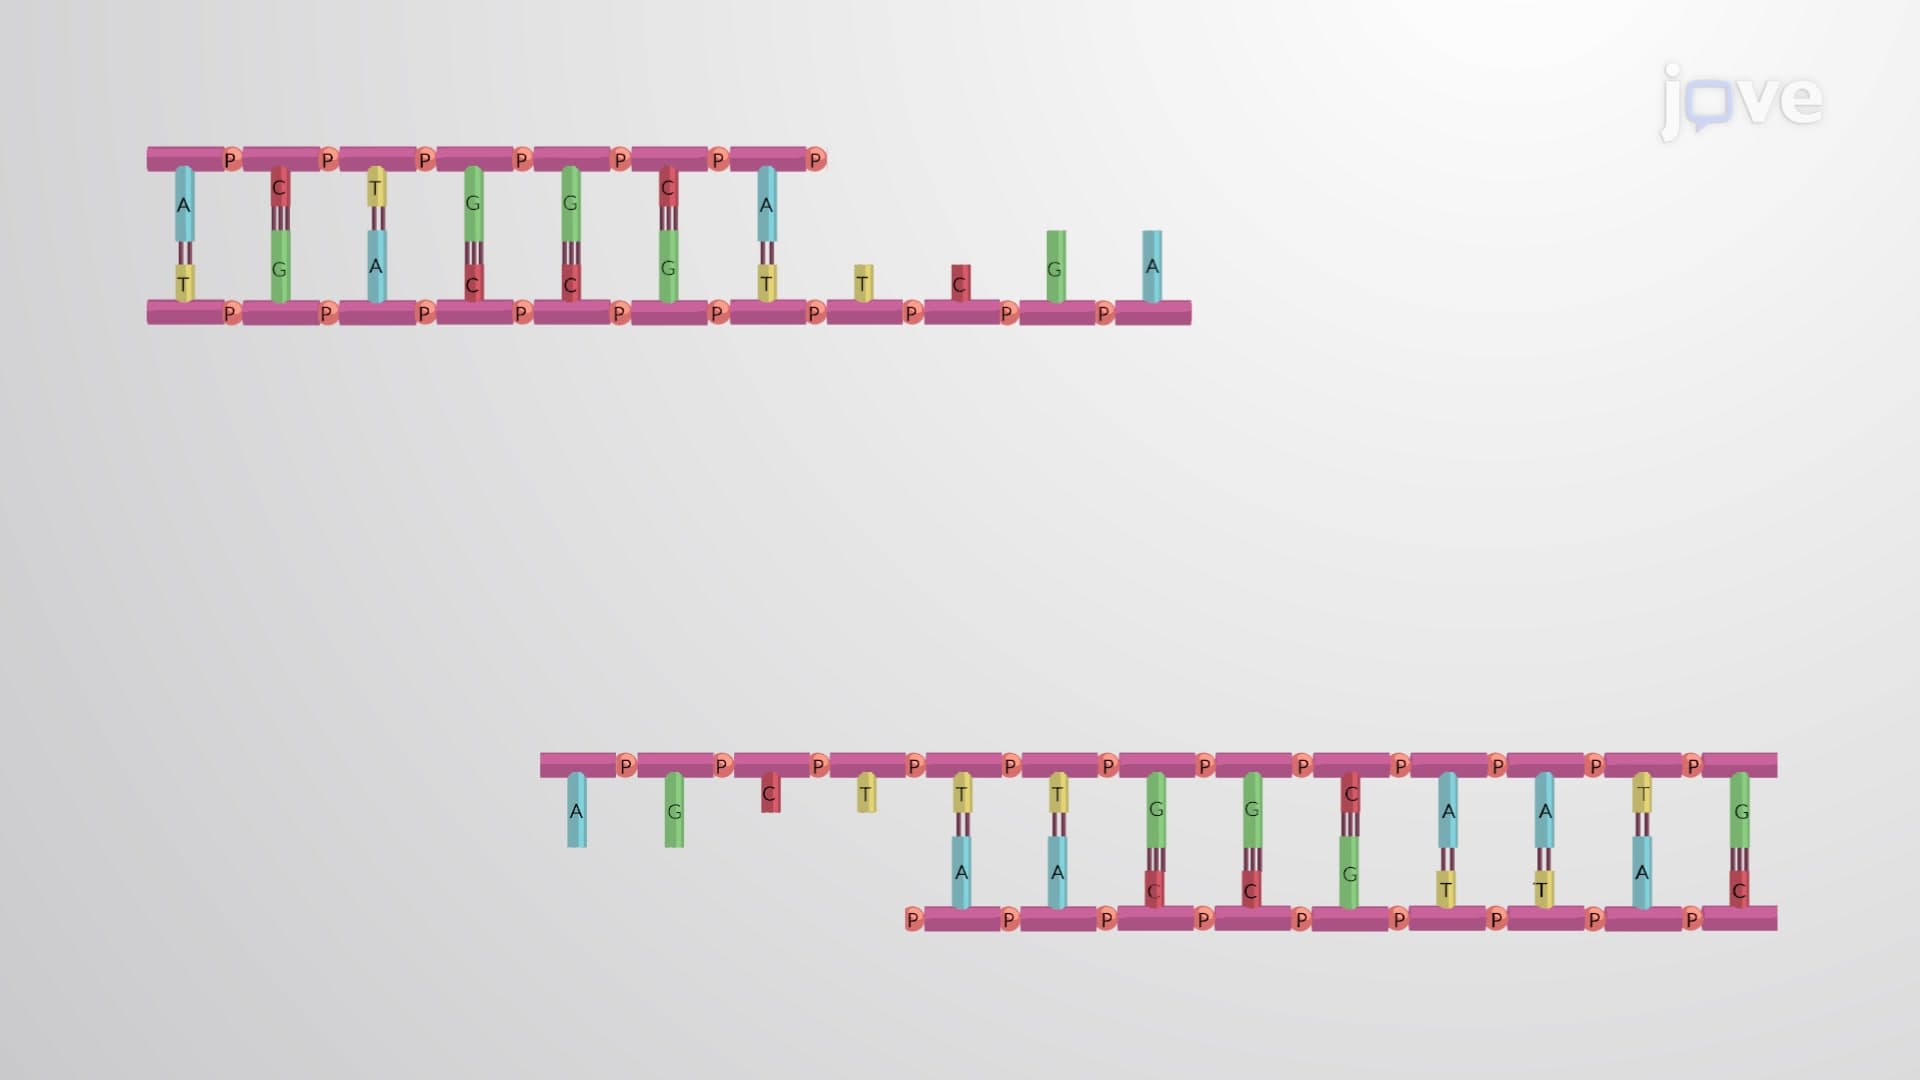
Restriction Enzymes
The host bacteria protect their own genomic DNA from these enzymes by methylating these sites. Some...
 01:20
Mismatch Repair
The Mutator Protein Family Plays a Key Role in DNA Mismatch Repair
The human genome has more than 3 billion base pairs of DNA per cell. Prior to cell division, that vast amount of genetic...
 01:31
Proofreading
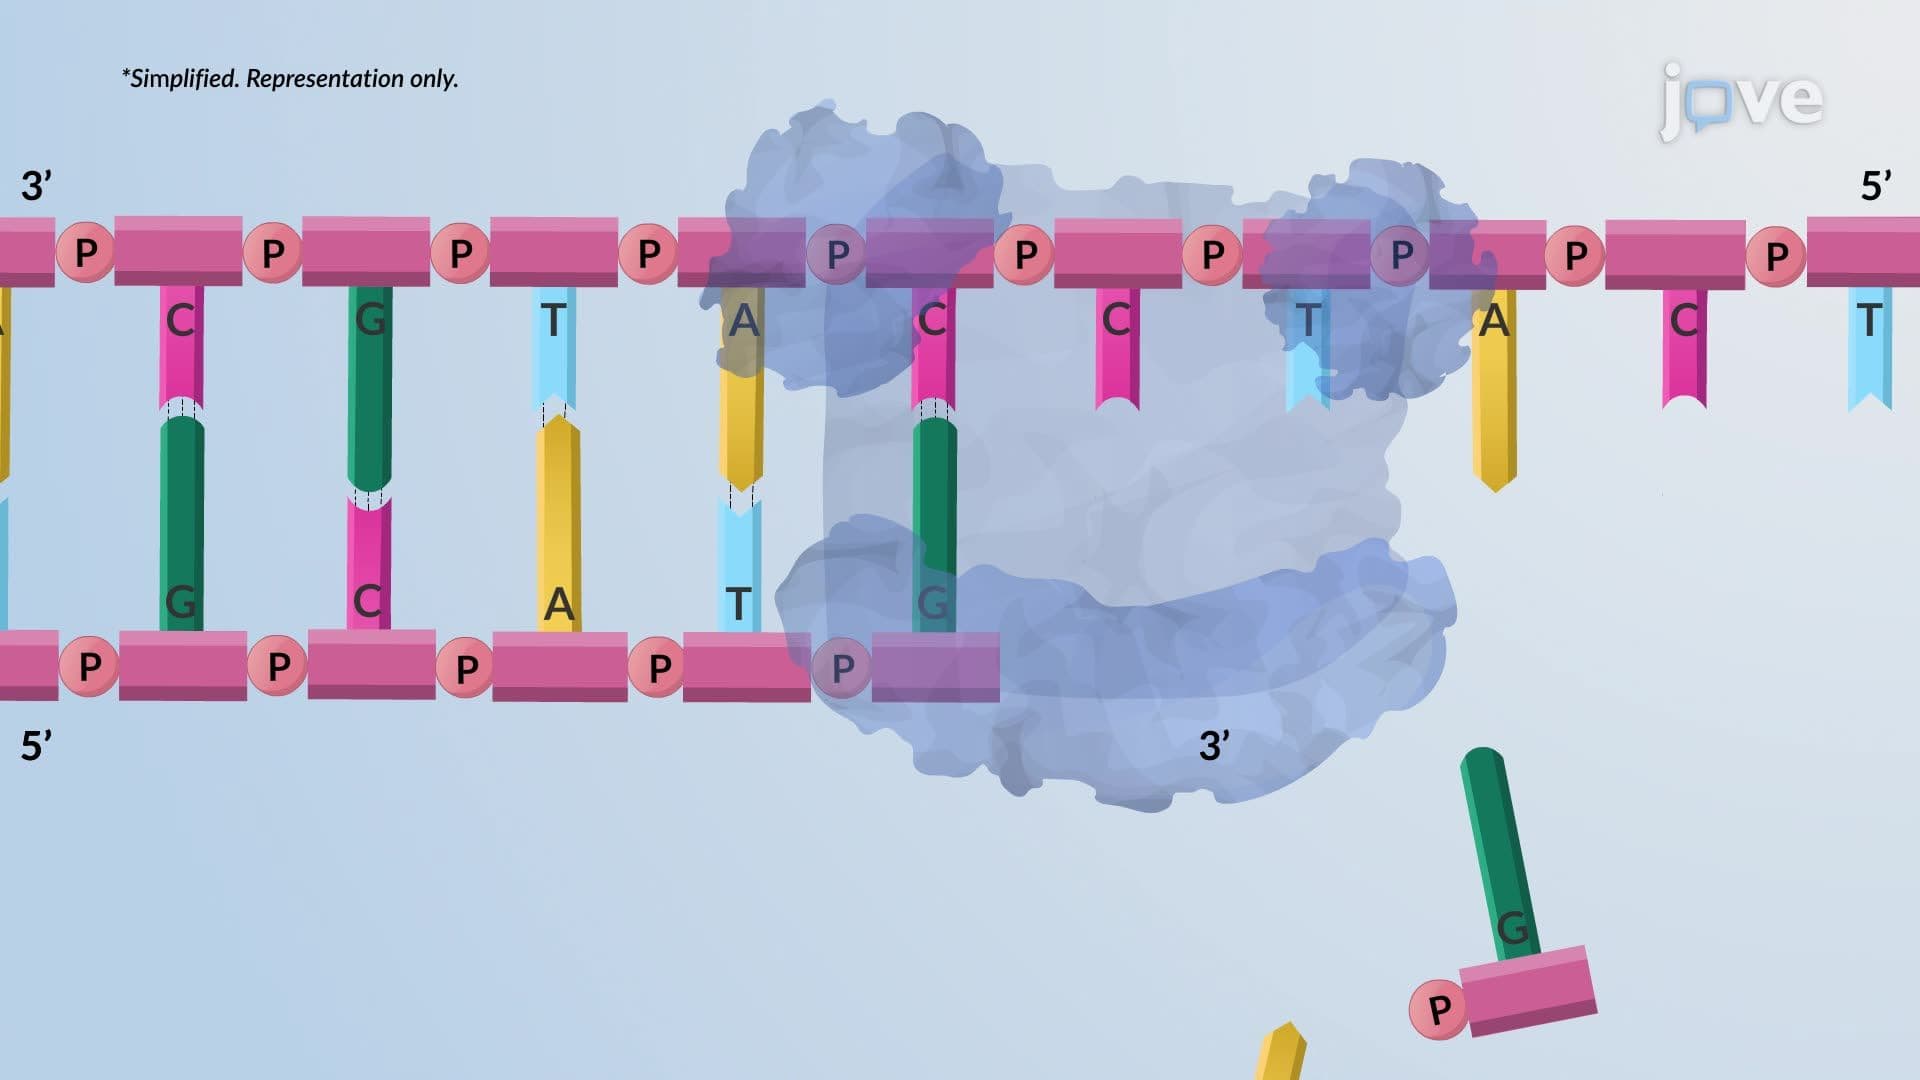
Errors During Replication are Corrected by the DNA Polymerase Enzyme
 01:43
Proofreading
 01:05
Single Nucleotide Polymorphisms-SNPs
 02:39
Organization of Genes