Related Experiment Video
Updated: Aug 13, 2026

Analyzing Tumor Gene Expression Factors with the CorExplorer Web Portal
Published on: October 11, 2019
Extraction of correlated gene clusters from multiple genomic data by generalized kernel canonical correlation
Y Yamanishi1, J-P Vert, A Nakaya
1Bioinformatics Center, Institute for Chemical Research, Kyoto University, Gokasho, Uji, Kyoto 611-0011, Japan. yoshi@kuicr.kyoto-u.ac.jp

Motivation:
A major issue in computational biology is the reconstruction of pathways from several genomic datasets, such as expression data, protein interaction data and phylogenetic profiles. As a first step toward this goal, it is important to investigate the amount of correlation which exists between these data.
Results:
These methods are successfully tested on their ability to recognize operons in the Escherichia coli genome, from the comparison of three datasets corresponding to functional relationships between genes in metabolic pathways, geometrical relationships along the chromosome, and co-expression relationships as observed by gene expression data.
Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:14
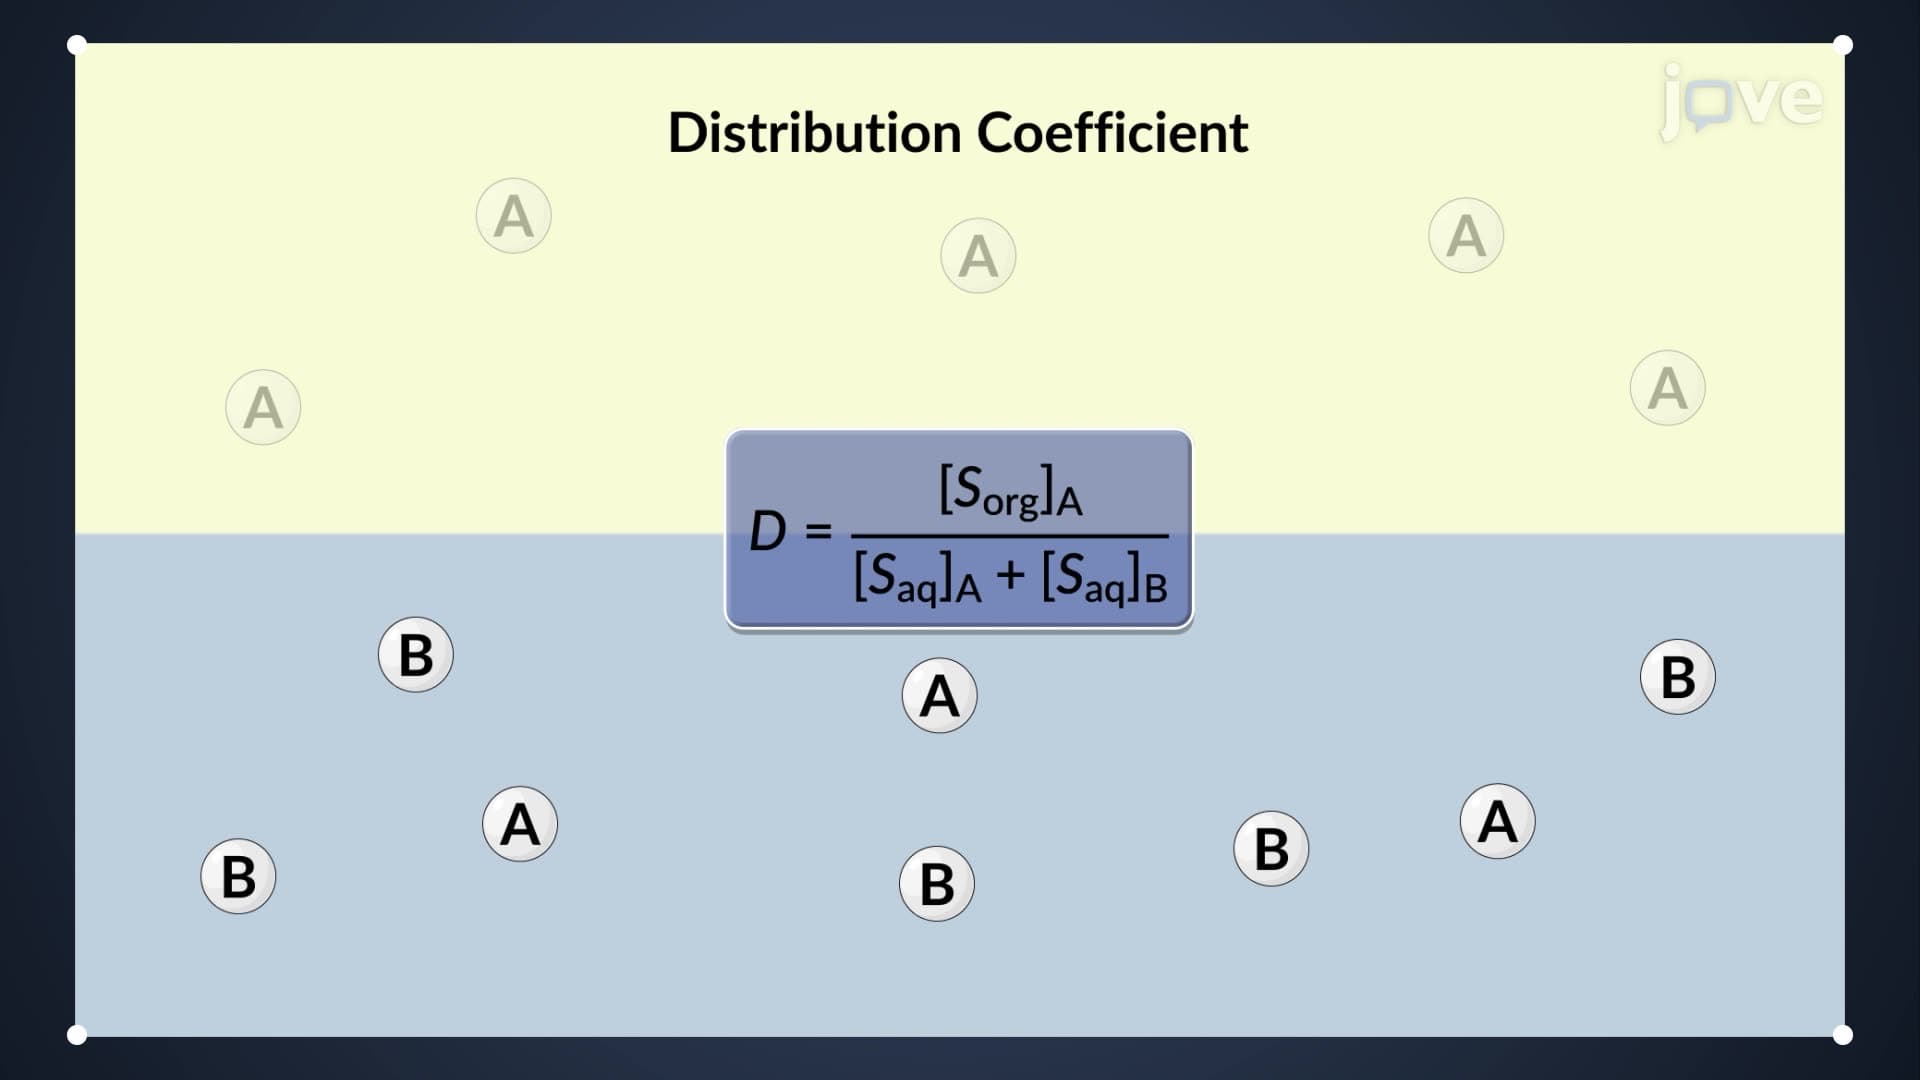
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an organic...
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:23
Correlation of Experimental Data
For example, a spherical particle moving through a viscous fluid experiences drag. Dimensional analysis shows that the drag force depends on the particle's diameter, velocity, and...
 01:20
Kendall's Coefficient of Concordance