Related Experiment Video
Updated: Sep 20, 2026

Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
Separation of individual-level and cluster-level covariate effects in regression analysis of correlated data
Melissa D Begg1, Michael K Parides
1Department of Biostatistics, Mailman School of Public Health of Columbia University, 722 West 168th Street (R626B), New York, NY 10032, U.S.A. mdb3@columbia.edu

Abstract:
The focus of this paper is regression analysis of clustered data. Although the presence of intracluster correlation (the tendency for items within a cluster to respond alike) is typically viewed as an obstacle to good inference, the complex structure of clustered data offers significant analytic advantages over independent data. One key advantage is the ability to separate effects at the individual (or item-specific) level and the group (or cluster-specific) level. We review different approaches for the separation of individual-level and cluster-level effects on response, their appropriate interpretation and give recommendations for model fitting based on the intent of the data analyst. Unlike many earlier papers on this topic, we place particular emphasis on the interpretation of the cluster-level covariate effect. The main ideas of the paper are highlighted in an analysis of the relationship between birth weight and IQ using sibling data from a large birth cohort study.

Related Concept Videos
 00:53
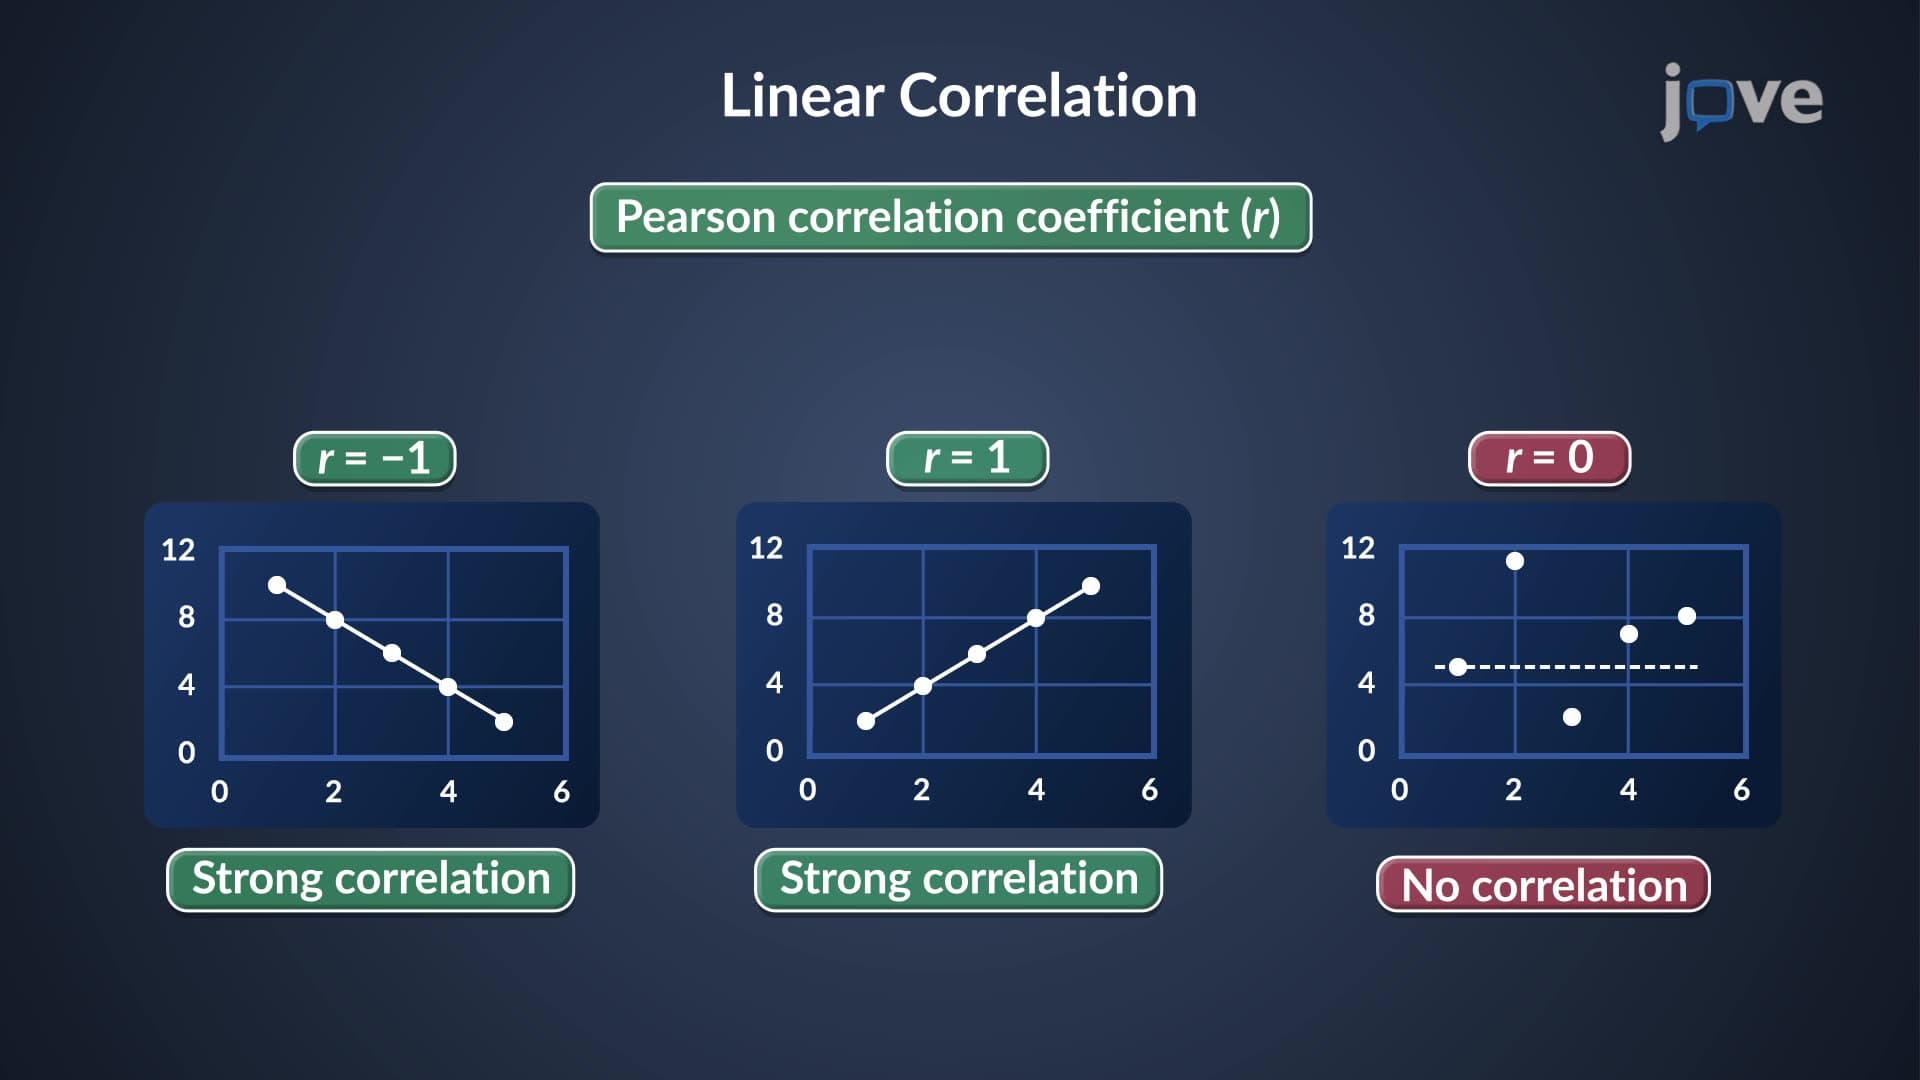
Correlation and Regression
 01:23
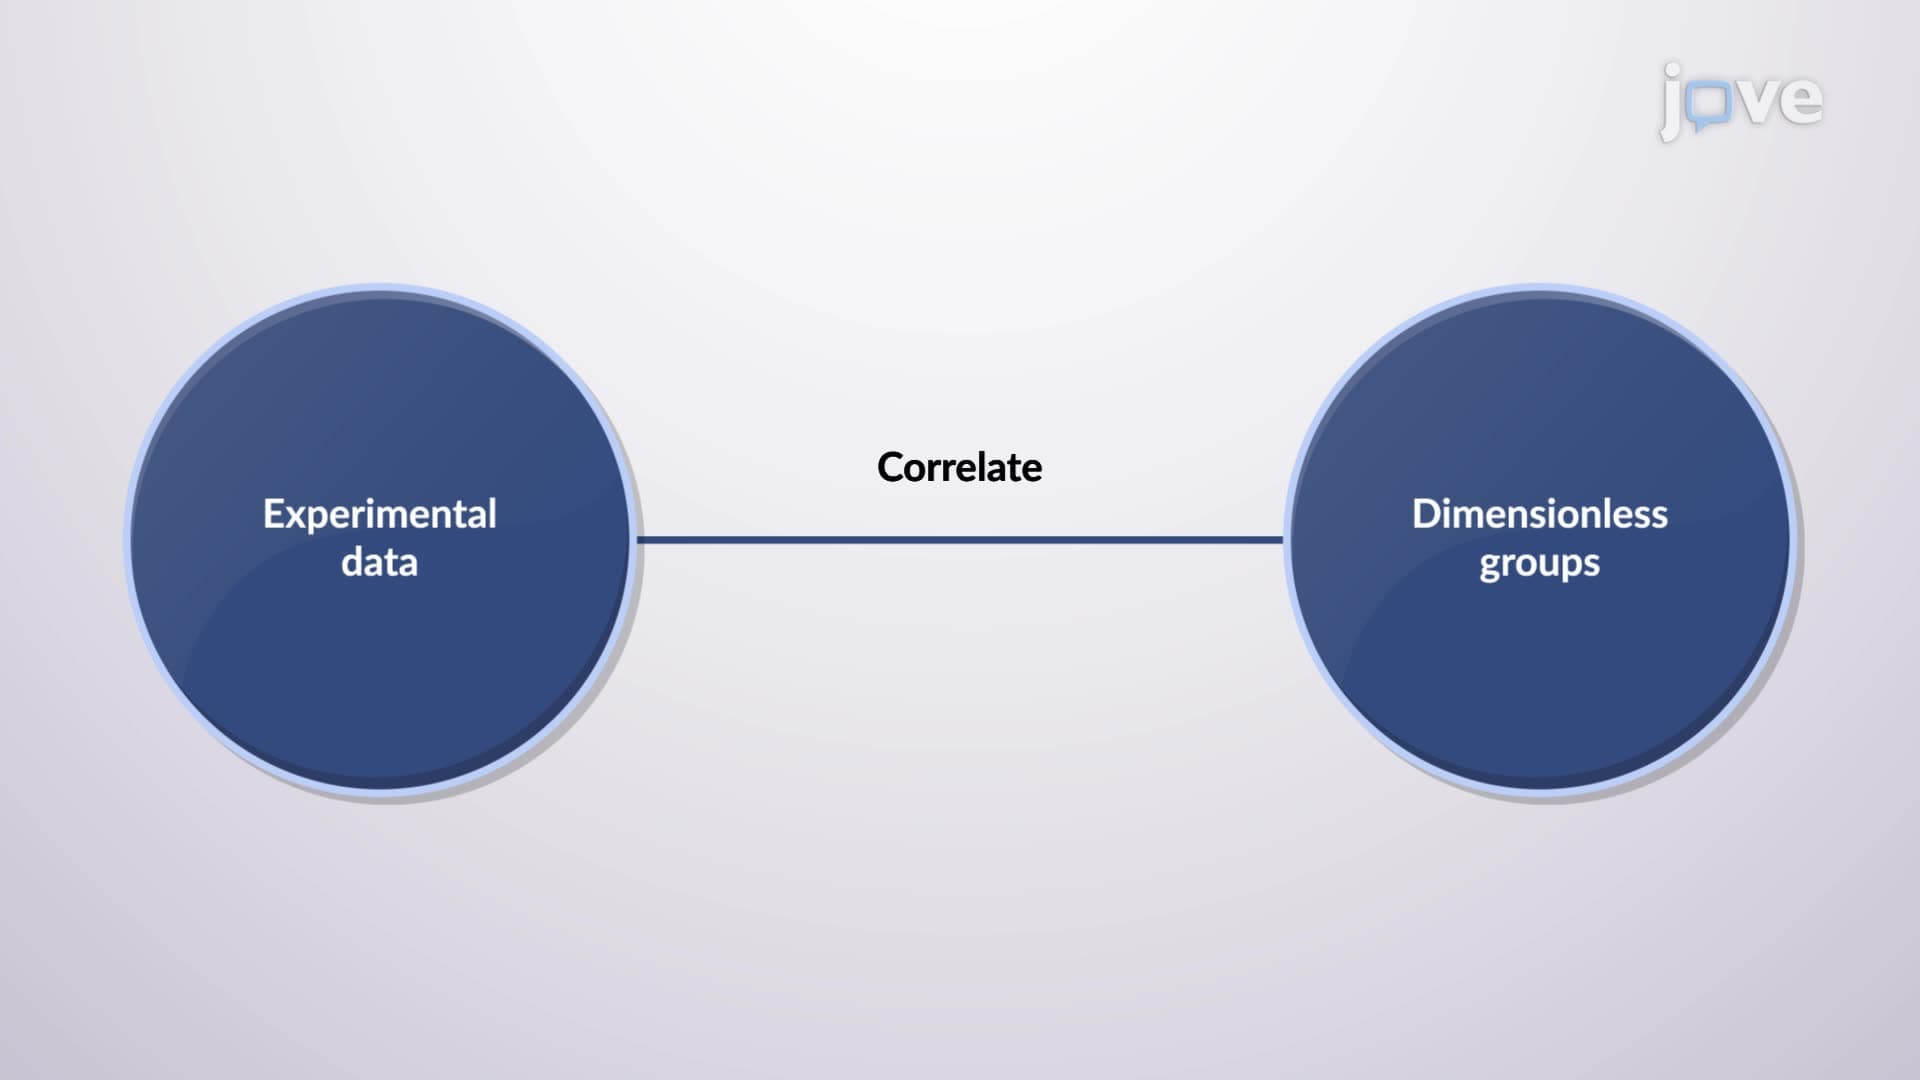
Correlation of Experimental Data
For example, a spherical particle moving through a viscous fluid experiences drag. Dimensional analysis shows that the drag force depends on the particle's diameter, velocity, and...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:19
Variation
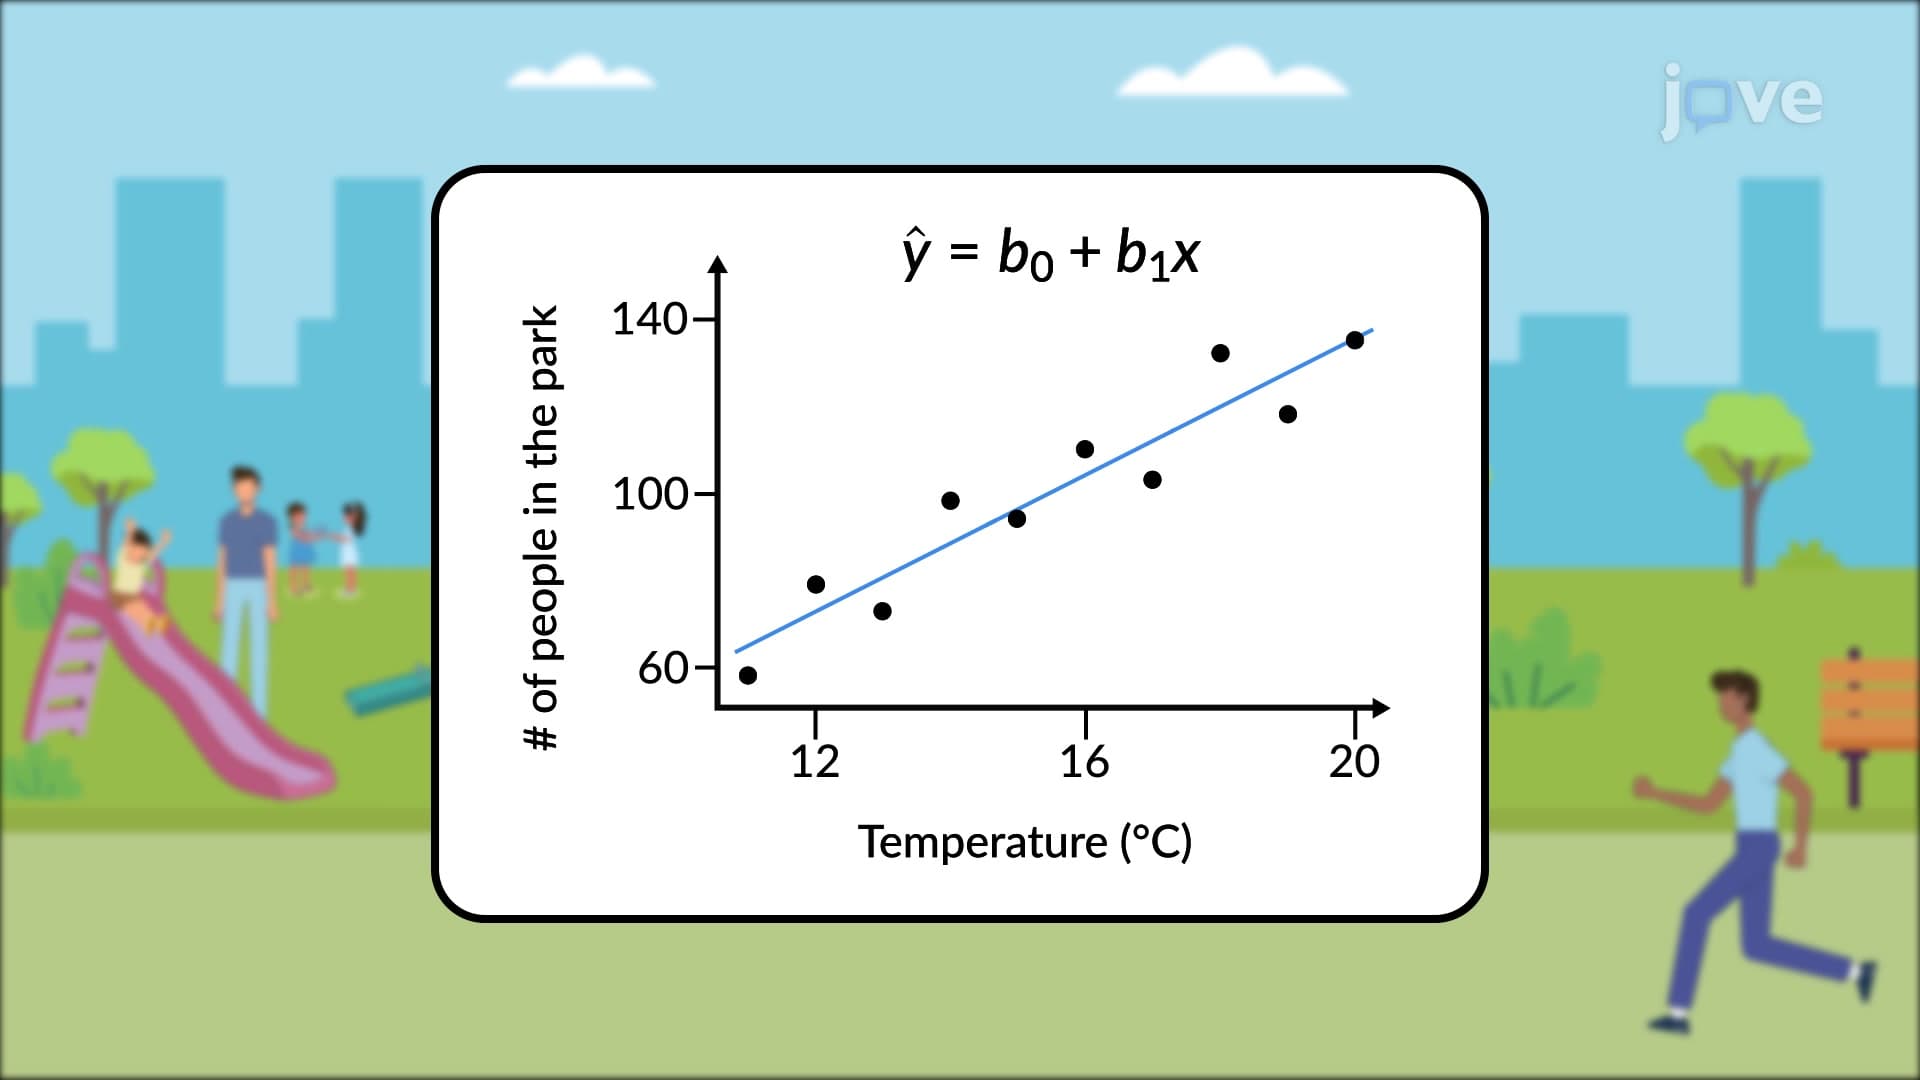
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Calculating and Interpreting the Linear Correlation Coefficient
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as: