Related Experiment Video
Updated: Sep 20, 2026

An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
Estimation of weights and validation: a marginal likelihood approach
Andrey A Lebedev1, Ian J Tickle, Roman A Laskowski
1School of Crystallography, Birkbeck College, London WC1E 7HX, England.

Abstract:
The estimation of weights is quite an important aspect of the restrained refinement of macromolecular structures and related procedures such as the estimation of coordinate errors and structure validation using geometrical criteria. In principle, the method of maximum likelihood can be used for estimation of both atomic and weighting parameters. However, the low observation-to-parameter ratio in macromolecular refinement makes this kind of estimate of weighting parameters seriously biased; thus, the weighting parameters have traditionally been estimated separately from atomic parameters using a special technique, such as minimizing the free R factor. However, the variance of the latter estimate is large, as only a small portion of all data is used. In this work, an estimator of weights is proposed which is based on an approximation of a marginal likelihood function of the weighting parameters and which uses all the X-ray data. There is a known true value for the overall scaling coefficient for distance variances in restrained refinement and therefore the (maximum-likelihood) estimator for this coefficient may be used as a validation statistic.
Related Concept Videos
 01:26
Distributions to Estimate Population Parameter
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:21
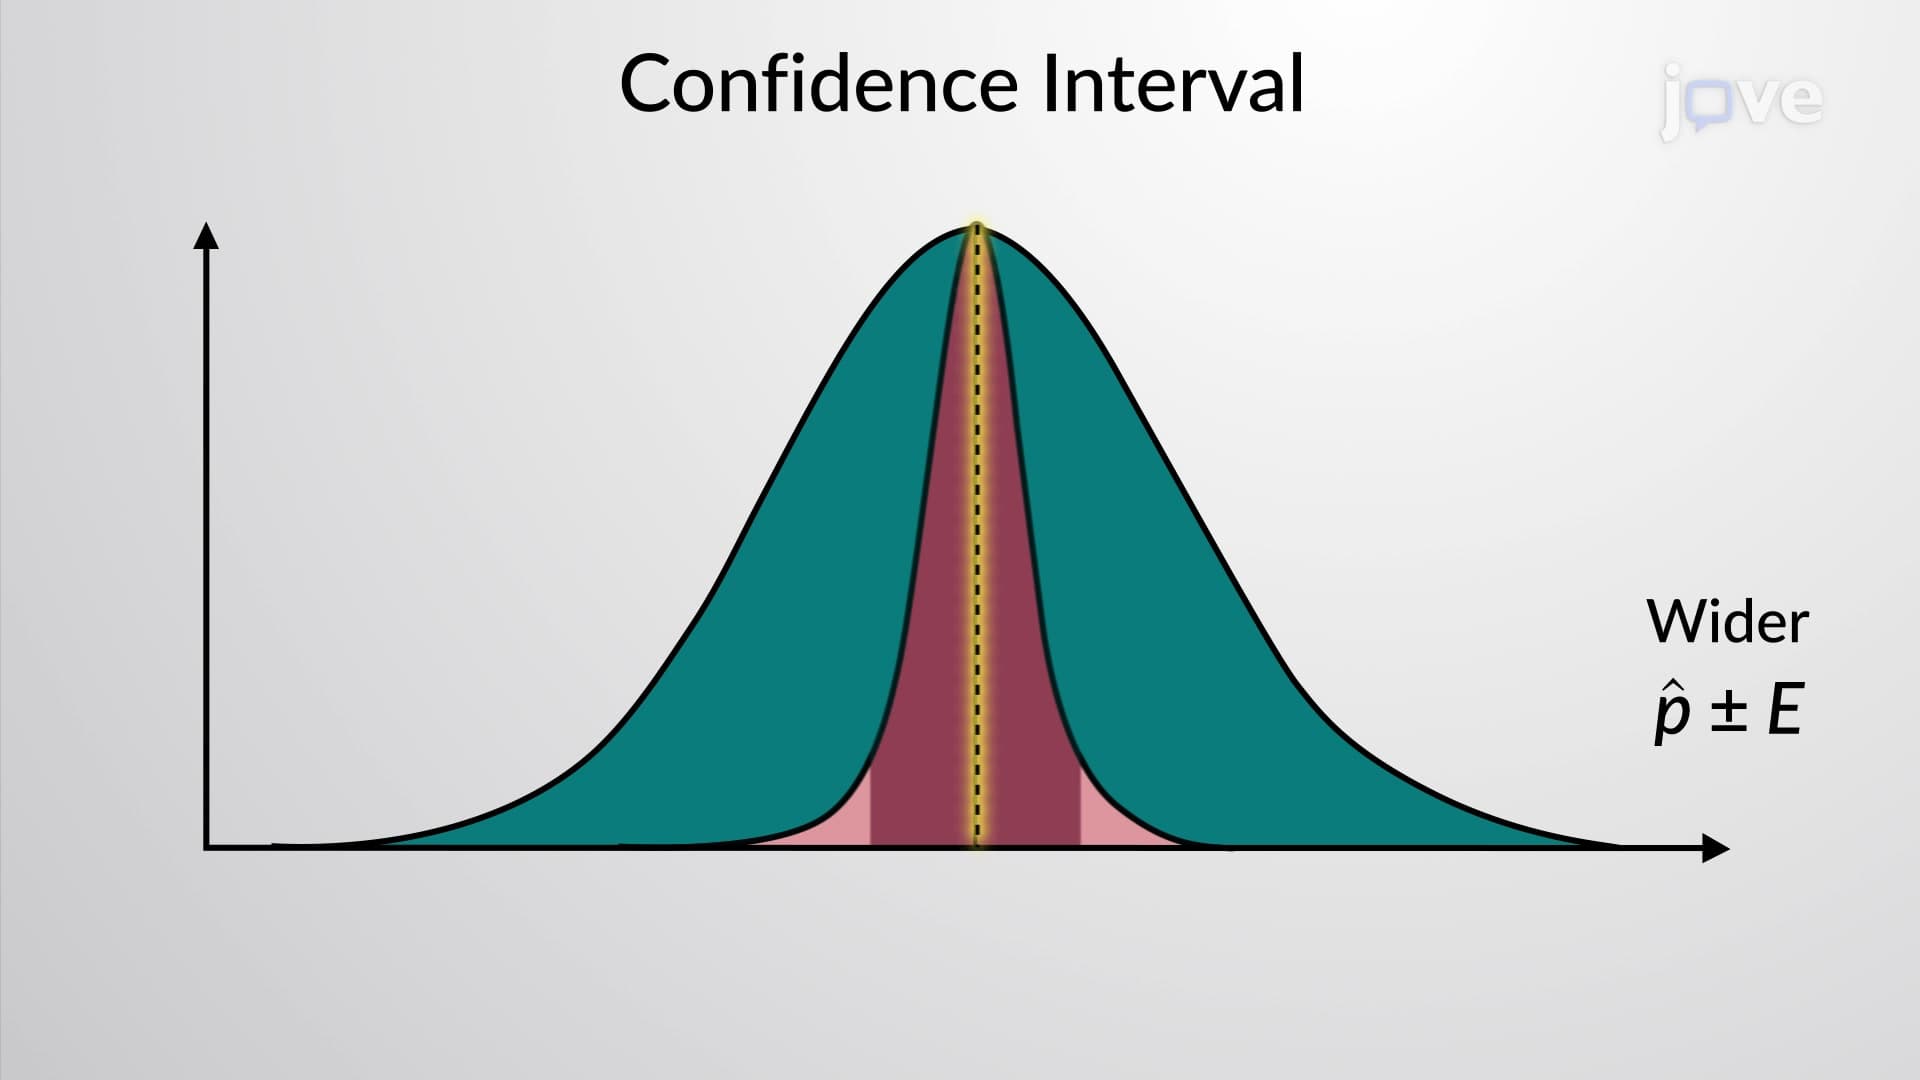
Confidence Intervals
A confidence...
 01:22
Estimating Population Mean with Unknown Standard Deviation
William S. Gosset (1876–1937) of the Guinness...