Related Experiment Video
Updated: Aug 30, 2026

Foreign Accent and Forensic Speaker Identification in Voice Lineups: The Influence of Acoustic Features Based on Prosody
Published on: September 27, 2024
Automatic pre-segmentation of running speech improves the robustness of several acoustic voice measures
Tom Bäckström1, Laura Lehto, Paavo Alku
1Laboratory of Acoustics and Audio Signal Processing, Helsinki University of Technology, P.O. Box 3000, FIN-02015 Hut, Finland. tom.backstrom@hut.fi

Abstract:
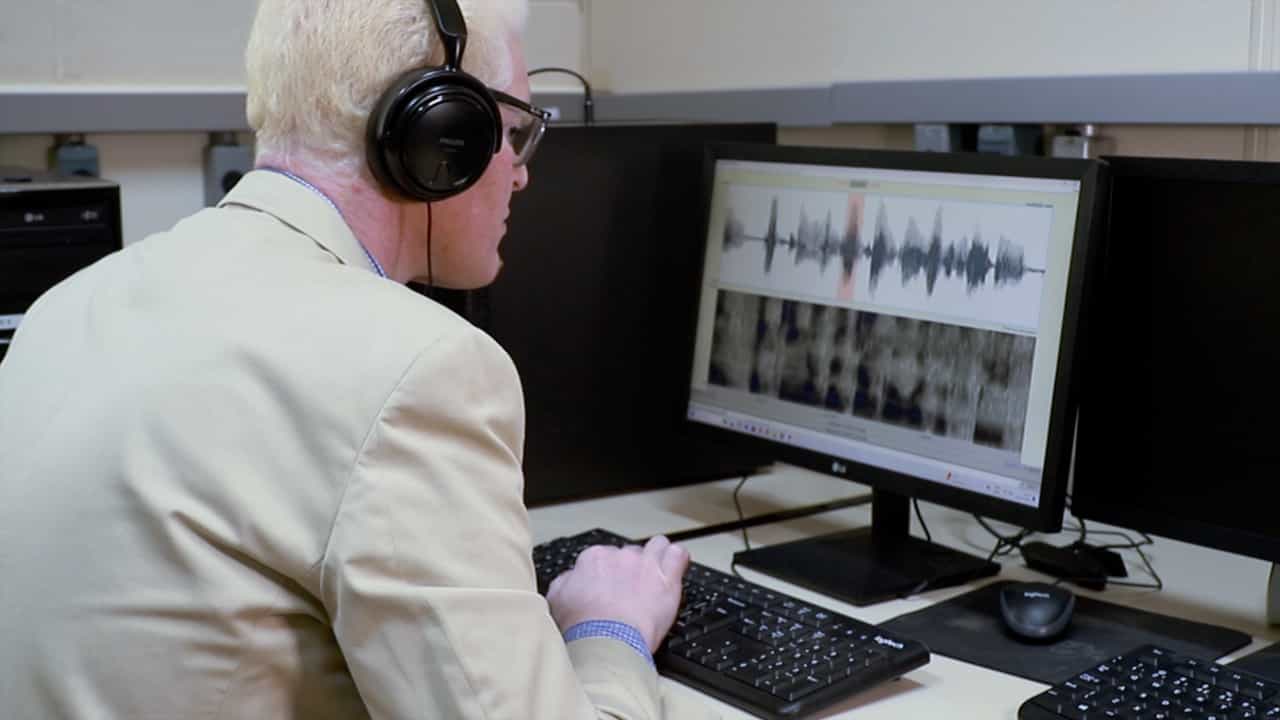
In order to study vocal loading, we developed a speech analysis environment for continuous speech. The objective was to build a robust system capable of handling large amounts of data while minimizing the amount of user-intervention required. The current version of the system can analyze up to five-minute recordings of speech at a time. Through a semiautomatic process it will classify a speech signal into segments of silence, voiced speech and unvoiced speech. Parameters extracted from the input signal include fundamental frequency, sound pressure level, alpha-ratio and speech segment information such as the ratio of speech to silence. This paper presents results from the performance evaluation of the system, which shows that the analysis environment is able to perform robust and consistent measurements of continuous speech.