To transform or not transform skewed data for psychometric analysis: that is the question!
Related Experiment Video
Updated: Aug 29, 2026
Validation of a Psychosocial Intervention on Body Image in Older People: An Experimental Design
Published on: May 31, 2021
Anne E Norris1, Karen J Aroian
1William F Connell School of Nursing, Boston College, Chestnut Hill, Massachusetts 02467, USA. norrisa@bc.edu

Background:
Although data transformation is generally recommended, its benefits of have not been widely studied. This report reviews evidence regarding the costs and benefits of transforming skewed data with respect to two statistics commonly used in psychometric analyses: the Cronbach alpha and the Pearson product-moment correlation.
Methods:
Data describing 758 immigrants from the former Soviet Union who completed a Russian language version of the Symptom Checklist-90-Revised (SCL-90-R) were used to demonstrate the effects of transformation. More than half (55%) of the SCL-90-R items had a problematic skew. The Cronbach alpha and the Pearson product-moment correlation were calculated for original item responses as well as for square root and log transformations of these responses. Sample size (full, 30%, 20%), transformation type (square root or log transformation), and transformation method (sum items first and then transform, transform items first and then sum) were manipulated to evaluate the relevance of these factors to transformation.
Results:
Regardless of sample size, neither the Cronbach alpha nor the Pearson product-moment correlation showed a difference between original and transformed data, with one exception. When items were transformed first before being summed in the calculation of the Pearson product-moment correlation, inconsistently higher (+.05) or slightly lower values (-.01) were observed relative to those created with the nontransformed data across the different sample sizes.
Conclusions:
These findings suggest that data transformation is not always needed or advisable when the Cronbach alpha or Pearson product-moment correlation is calculated for instruments with skewed item responses.
Related Concept Videos
 01:06
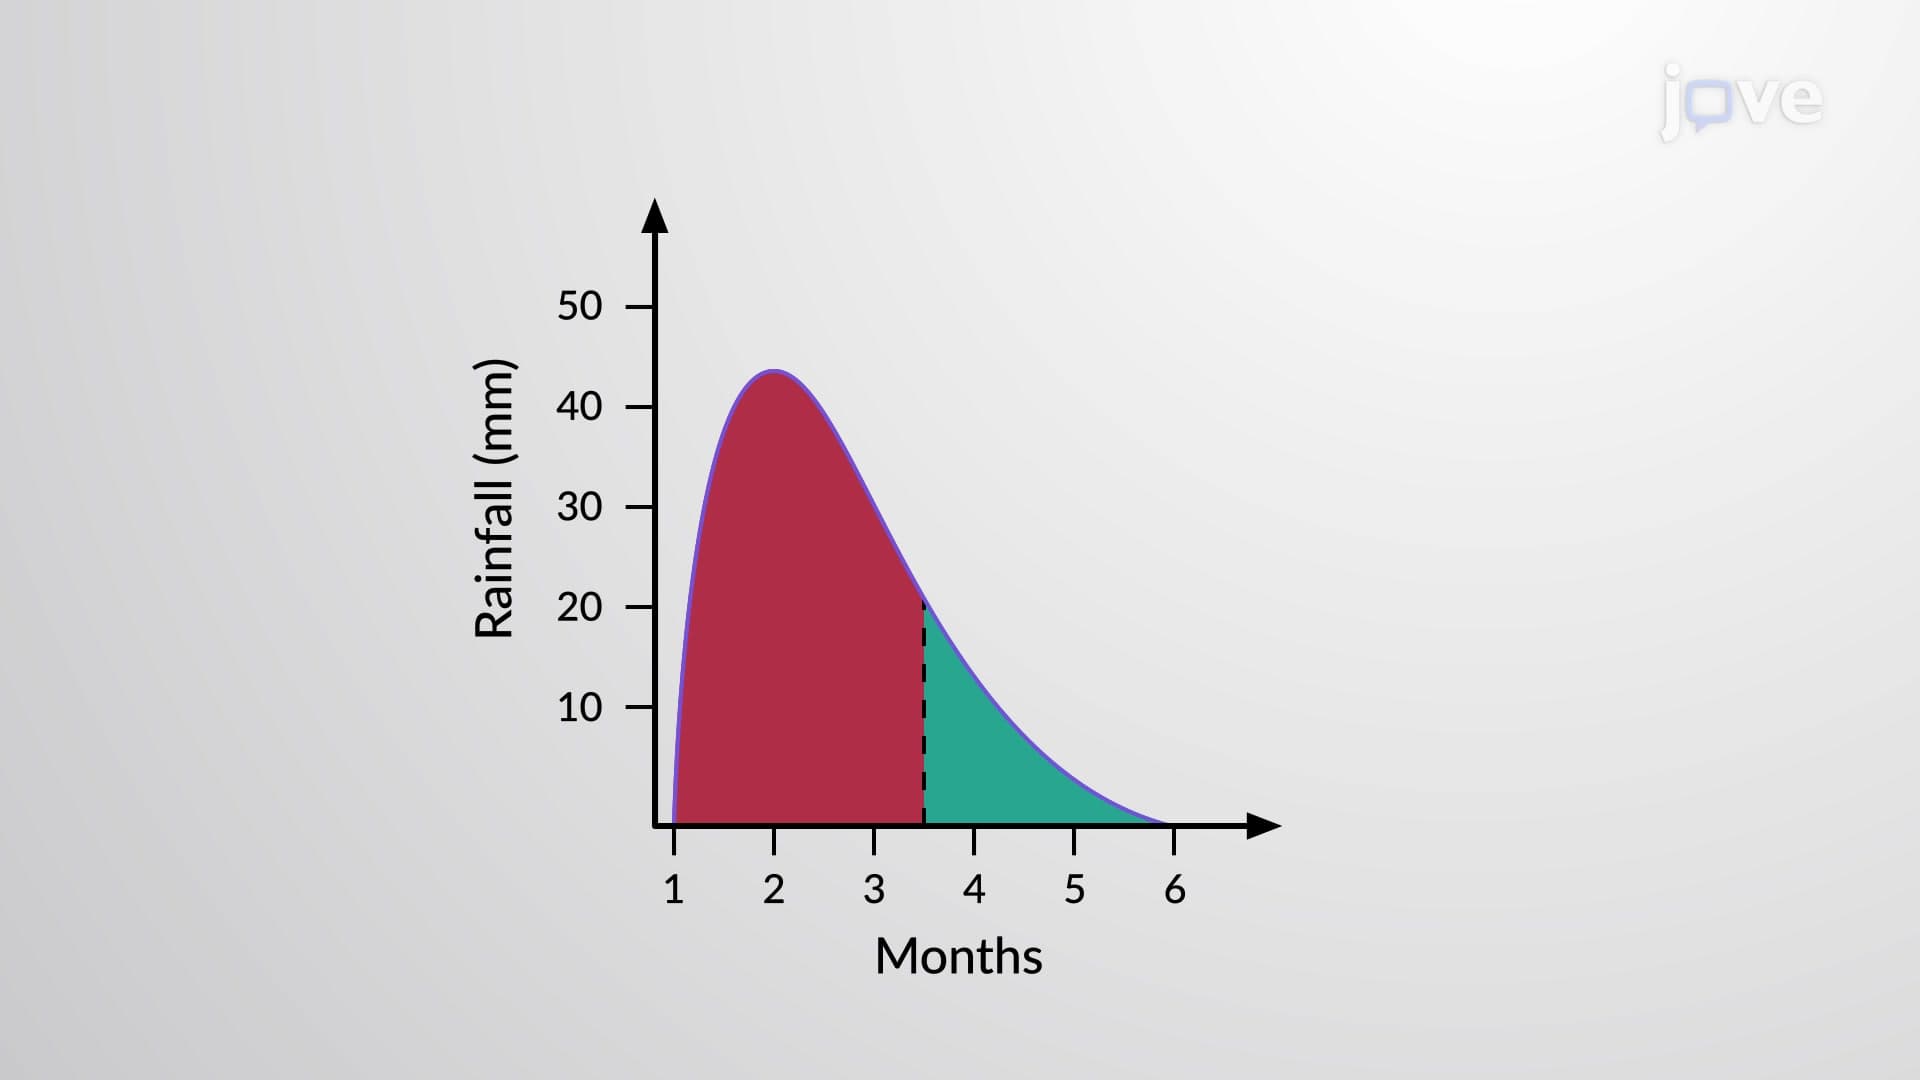
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency are...
 01:09
Types of Skewness
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
 01:24
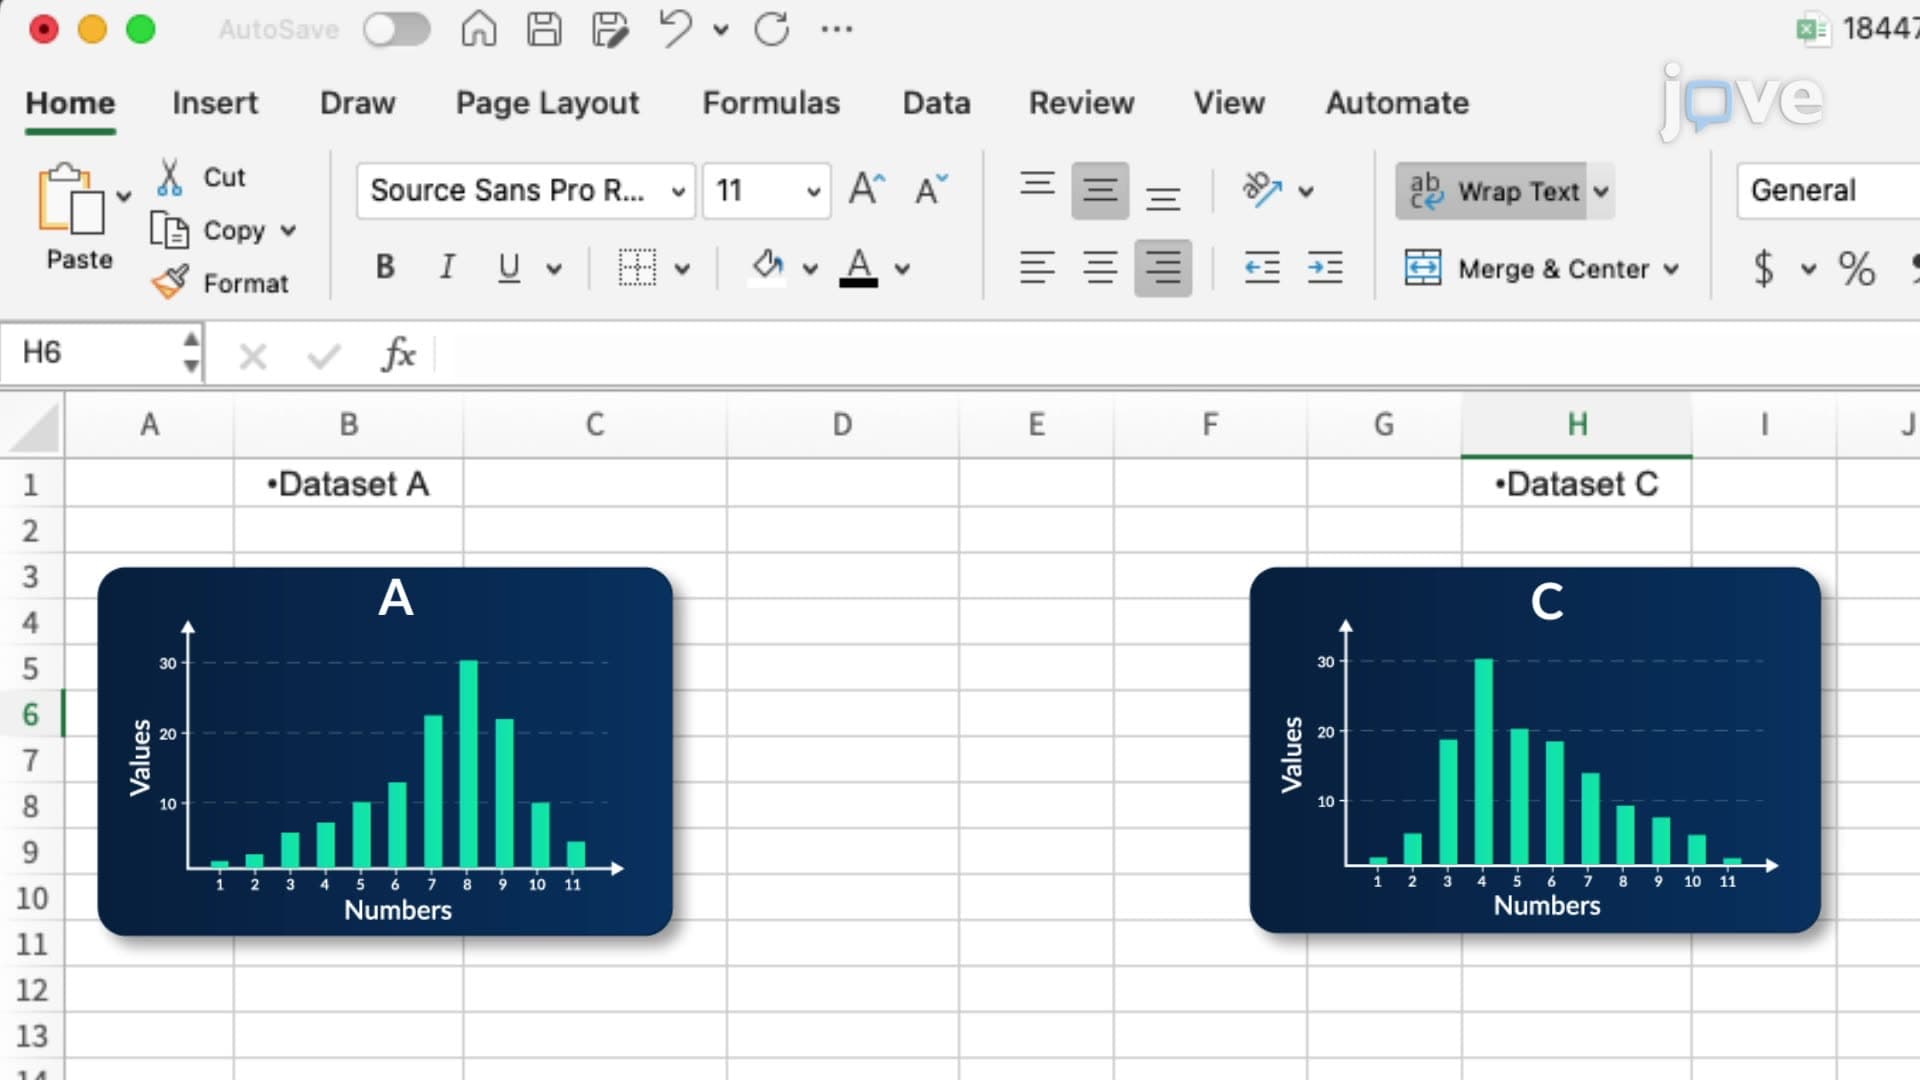
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
 01:52
Regression Toward the Mean
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
 01:19
Data: Types and Distribution
Distributions in...