Related Experiment Video
Updated: Jun 24, 2026

Synthetic, Multi-Layer, Self-Oscillating Vocal Fold Model Fabrication
Published on: December 2, 2011
A model of acoustic interspeaker variability based on the concept of formant-cavity affiliation
Lian Apostol1, Pascal Perrier, Gérard Bailly
1Institut de la Communication Parlée, UMR CNRS 5009, INPG, Grenoble, France.

Abstract:
A method is proposed to model the interspeaker variability of formant patterns for oral vowels. It is assumed that this variability originates in the differences existing among speakers in the respective lengths of their front and back vocal-tract cavities. In order to characterize, from the spectral description of the acoustic speech signal, these vocal-tract differences between speakers, each formant is interpreted, according to the concept of formant-cavity affiliation, as a resonance of a specific vocal-tract cavity. Its frequency can thus be directly related to the corresponding cavity length, and a transformation model can be proposed from a speaker A to a speaker B on the basis of the frequency ratios of the formants corresponding to the same resonances. In order to minimize the number of sounds to be recorded for each speaker in order to carry out this speaker transformation, the frequency ratios are exactly computed only for the three extreme cardinal vowels [i, a, u] and they are approximated for the remaining vowels through an interpolation function. The method is evaluated through its capacity to transform the (F1,F2) formant patterns of eight oral vowels pronounced by five male speakers into the (F1,F2) patterns of the corresponding vowels generated by an articulatory model of the vocal tract. The resulting formant patterns are compared to those provided by normalization techniques published in the literature. The proposed method is found to be efficient, but a number of limitations are also observed and discussed. These limitations can be associated with the formant-cavity affiliation model itself or with a possible influence of speaker-specific vocal-tract geometry in the cross-sectional direction, which the model might not have taken into account.
Related Concept Videos
 01:08
IR Spectrum Peak Splitting: Symmetric vs Asymmetric Vibrations
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:28
Standing Waves in a Cavity
 01:10
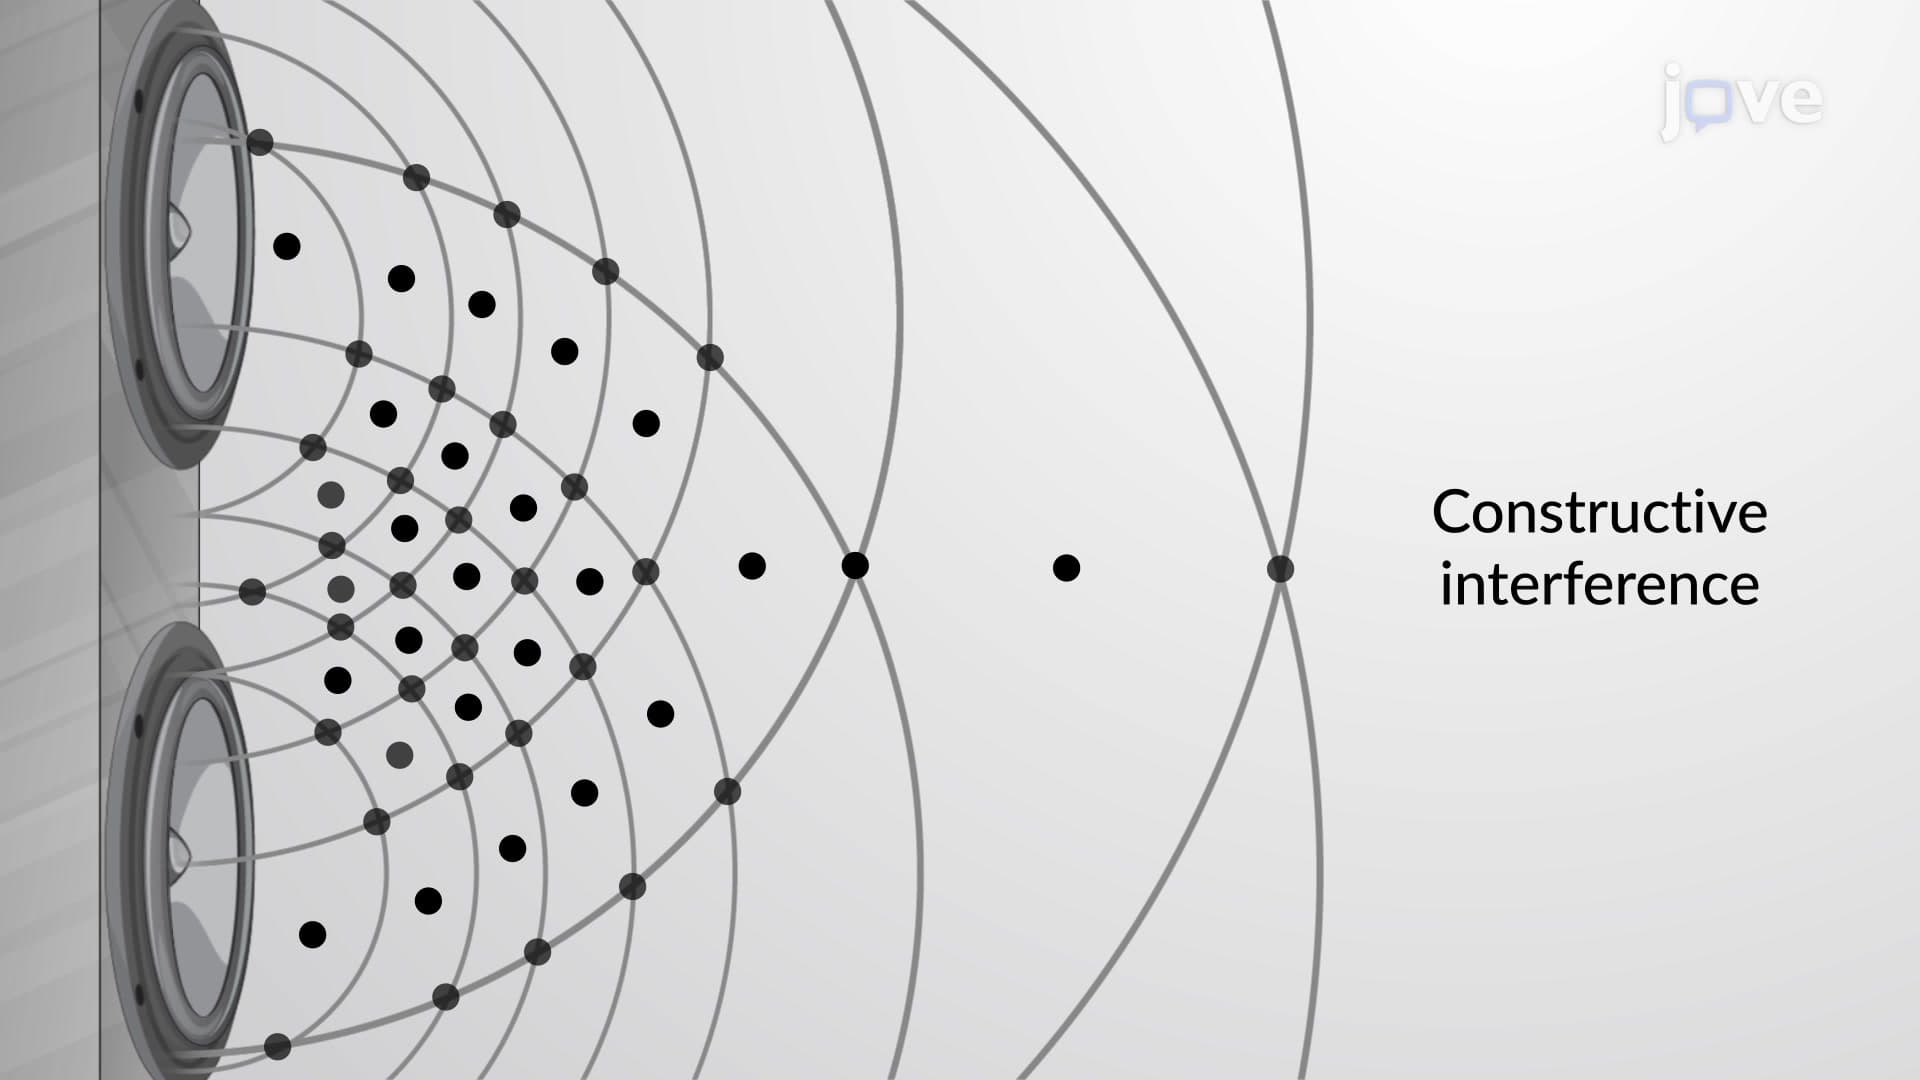
Interference: Path Lengths
Two special sources may be considered when they are in phase. This can be easily achieved by feeding the two sources from the same source. An example would be synchronizing the two speakers by feeding them with the same source, such as the sound waves produced by a tuning fork. This setup ensures that the two sources have the same frequency and are...
 01:26
Unsoundness of Aggregate due to Volume Change
 01:24
Facial Feedback Hypothesis