Related Experiment Videos
Latent variable discovery in classification models
Nevin L Zhang1, Thomas D Nielsen, Finn V Jensen
1Department of Computer Science, Hong Kong University of Science and Technology, Hong Kong, PR China. lzhang@cs.ust.hk

Abstract:
The naive Bayes model makes the often unrealistic assumption that the feature variables are mutually independent given the class variable. We interpret a violation of this assumption as an indication of the presence of latent variables, and we show how latent variables can be detected. Latent variable discovery is interesting, especially for medical applications, because it can lead to a better understanding of application domains. It can also improve classification accuracy and boost user confidence in classification models.
Related Concept Videos
 01:11
Variability: Analysis
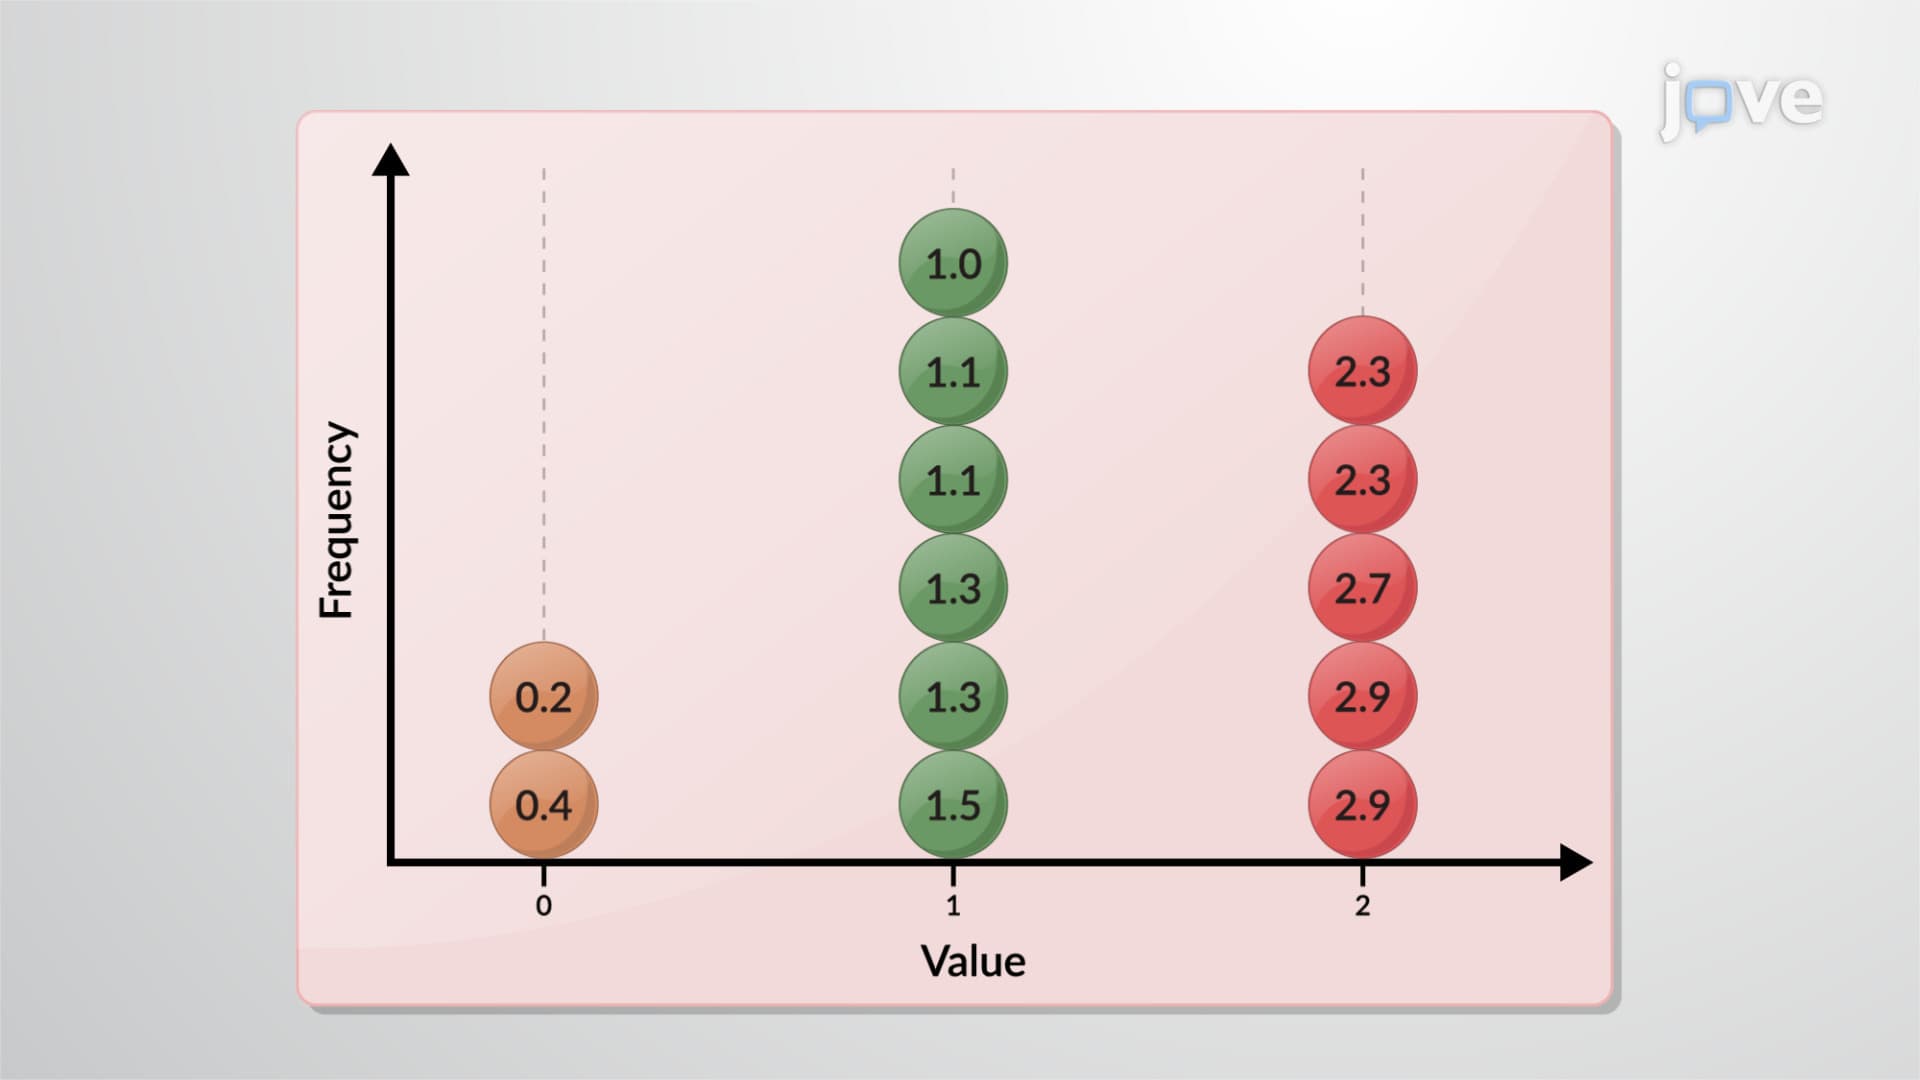
The range is a simple measure of variability, indicating the difference between the highest and...
 01:19
Variation
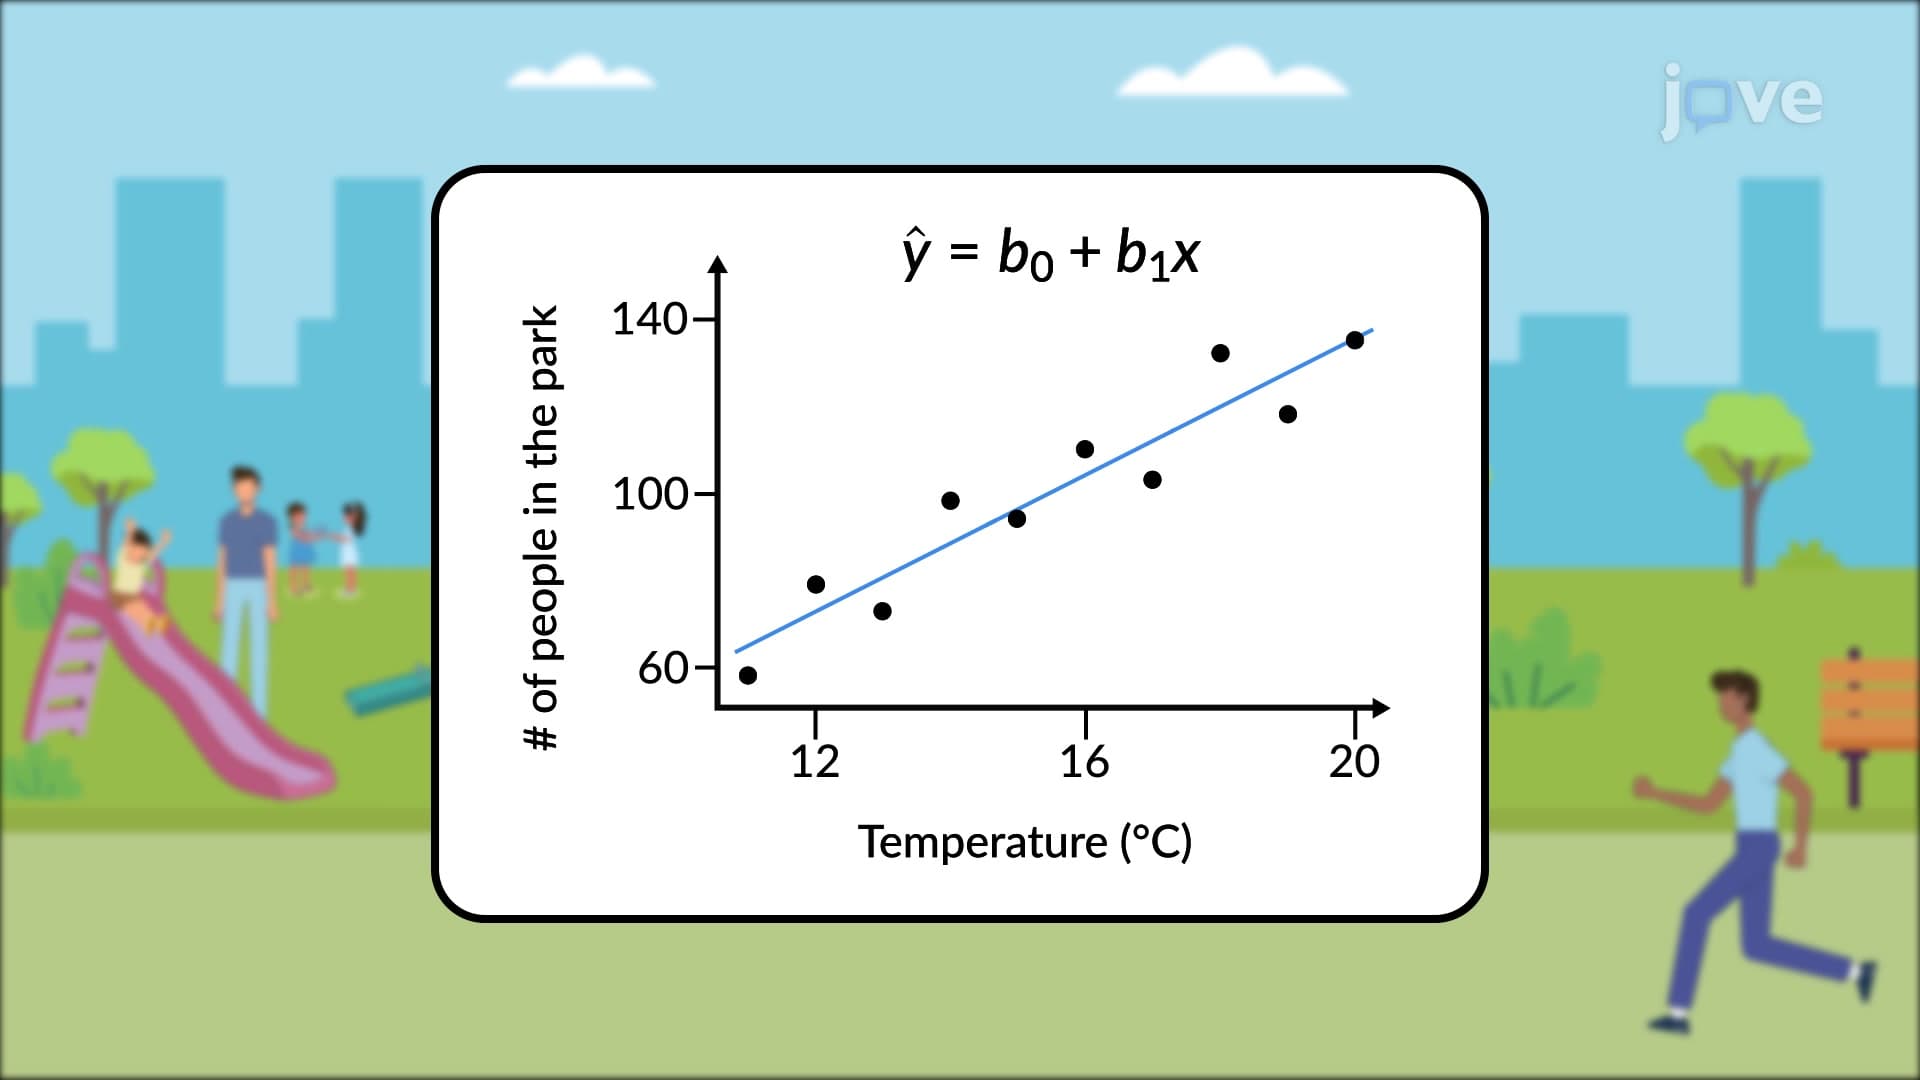
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...