PhyME: a probabilistic algorithm for finding motifs in sets of orthologous sequences
Related Experiment Video
Updated: Aug 21, 2026

A Practical Guide to Phylogenetics for Nonexperts
Published on: February 5, 2014
Saurabh Sinha1, Mathieu Blanchette, Martin Tompa
1Center for Studies in Physics and Biology, The Rockefeller University, New York, NY 10021, USA. saurabh@lonnrot.rockefeller.edu

Background:
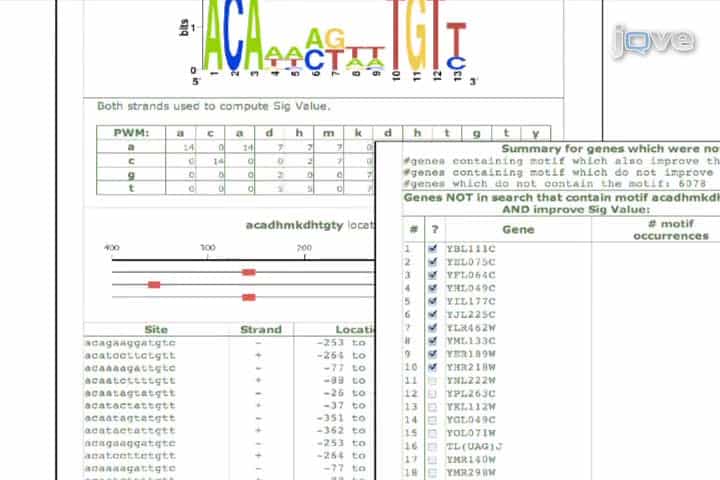
This paper addresses the problem of discovering transcription factor binding sites in heterogeneous sequence data, which includes regulatory sequences of one or more genes, as well as their orthologs in other species.
Results:
We propose an algorithm that integrates two important aspects of a motif's significance - overrepresentation and cross-species conservation - into one probabilistic score. The algorithm allows the input orthologous sequences to be related by any user-specified phylogenetic tree. It is based on the Expectation-Maximization technique, and scales well with the number of species and the length of input sequences. We evaluate the algorithm on synthetic data, and also present results for data sets from yeast, fly, and human.
Conclusions:
The results demonstrate that the new approach improves motif discovery by exploiting multiple species information.

Related Concept Videos
 02:47
Protein Families
 01:29
Modern Molecular Taxonomy
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:28
Microbial Phylogeny
 01:33
Proteomics
Proteomics is the study of proteomes' function. It involves the large-scale systematic study of the proteome to denote the protein complement expressed by a genome. Scientist Mark Wilkins coined the term proteomics...
 02:04
Protein-protein Interfaces