Related Experiment Video
Updated: Aug 16, 2026

Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Mixed group ranks: preference and confidence in classifier combination
Ofer Melnik1, Yehuda Vardi, Cun-Hui Zhang
1DIMACS CORE, Rutgers University, Piscataway, NJ 08854-8018, USA. melnik@dimacs.rutgers.edu

Abstract:
Classifier combination holds the potential of improving performance by combining the results of multiple classifers. For domains with very large numbers of classes, such as biometrics, we present an axiomatic framework of desirable mathematical properties for combination functions of rank-based classifiers. This framework represents a continuum of combination rules, including the Borda Count, Logistic Regression, and Highest Rank combination methods as extreme cases [11], [23], [4], [13]. Intuitively, this framework captures how the two complementary concepts of general preference for specific classifiers and the confidence it has in any specific result (as indicated by ranks) can be balanced while maintaining consistent rank interpretation. Mixed Group Ranks (MGR) is a new combination function that balances preference and confidence by generalizing these other functions. We demonstrate that MGR is an effective combination approach by performing multiple experiments on data sets with large numbers of classes and classifiers from the FERET face recognition study.
Related Concept Videos
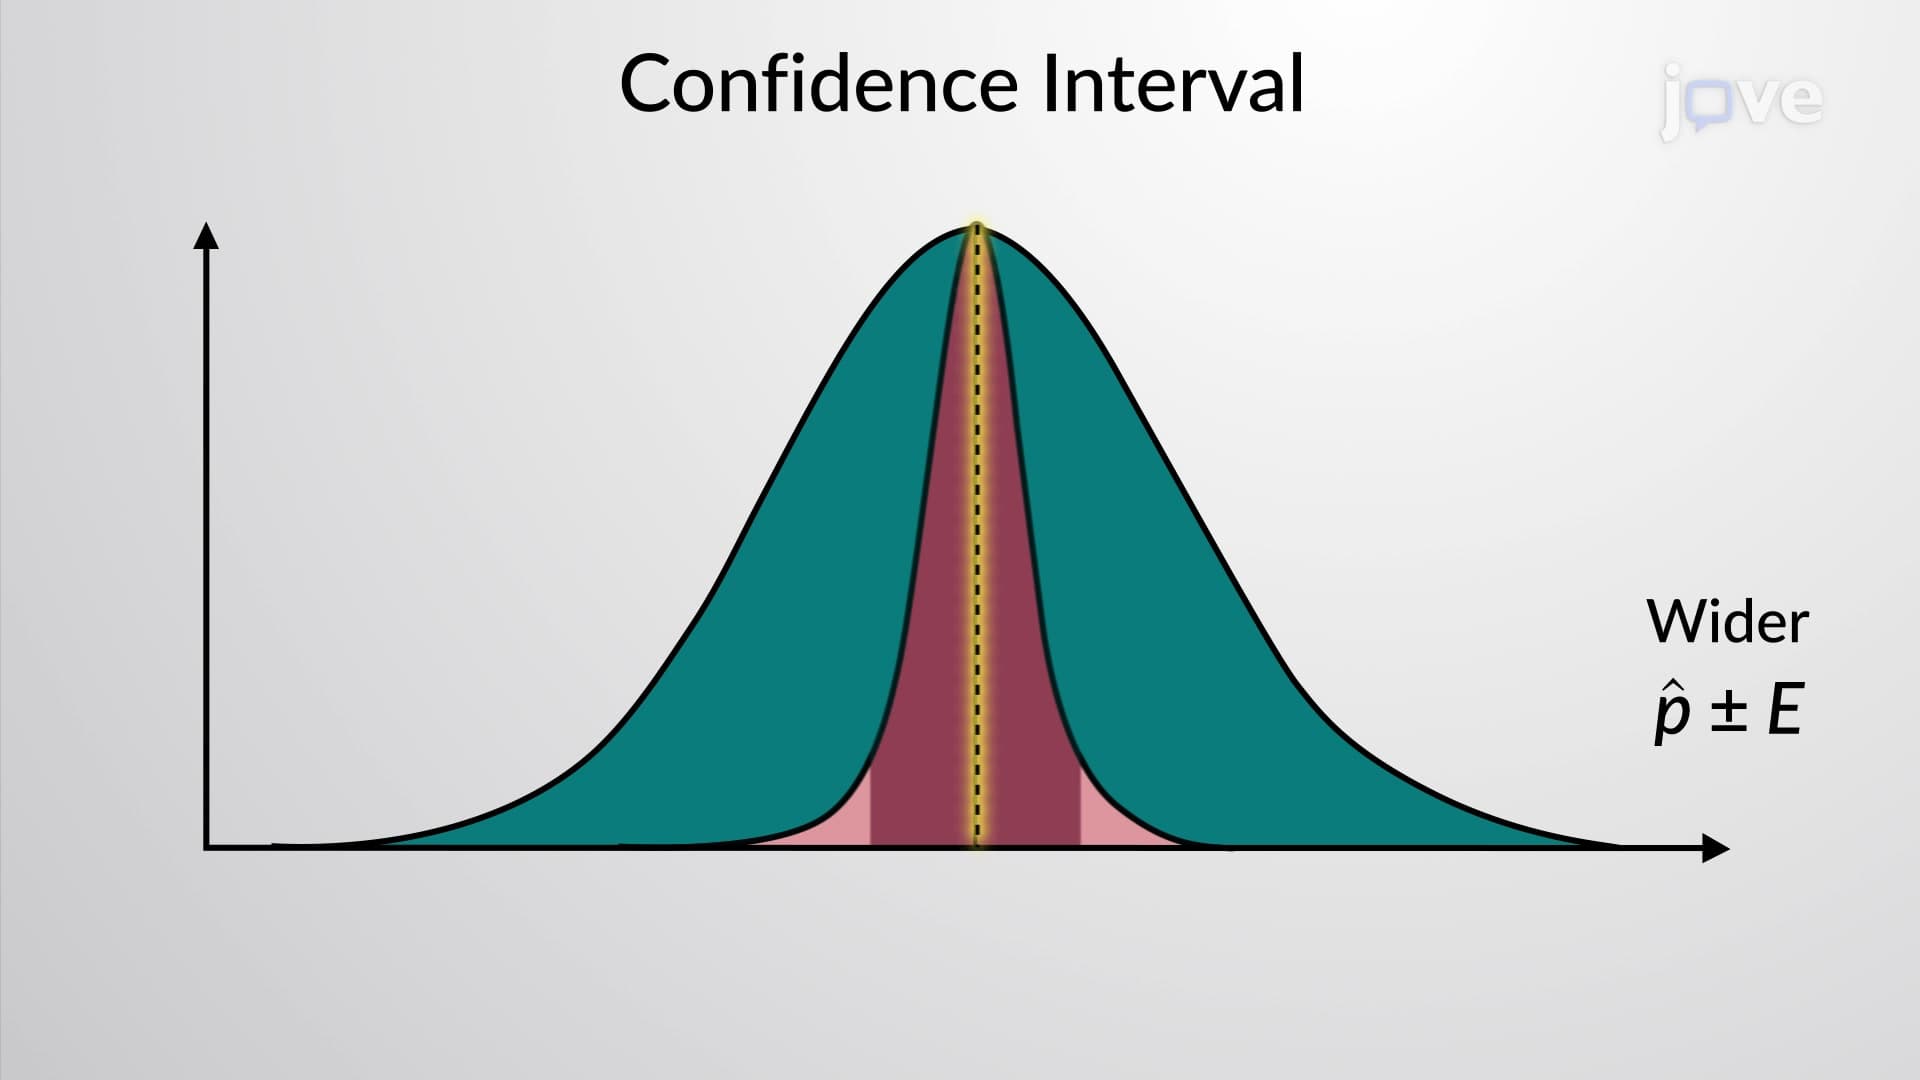 01:21
Confidence Intervals
A confidence...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
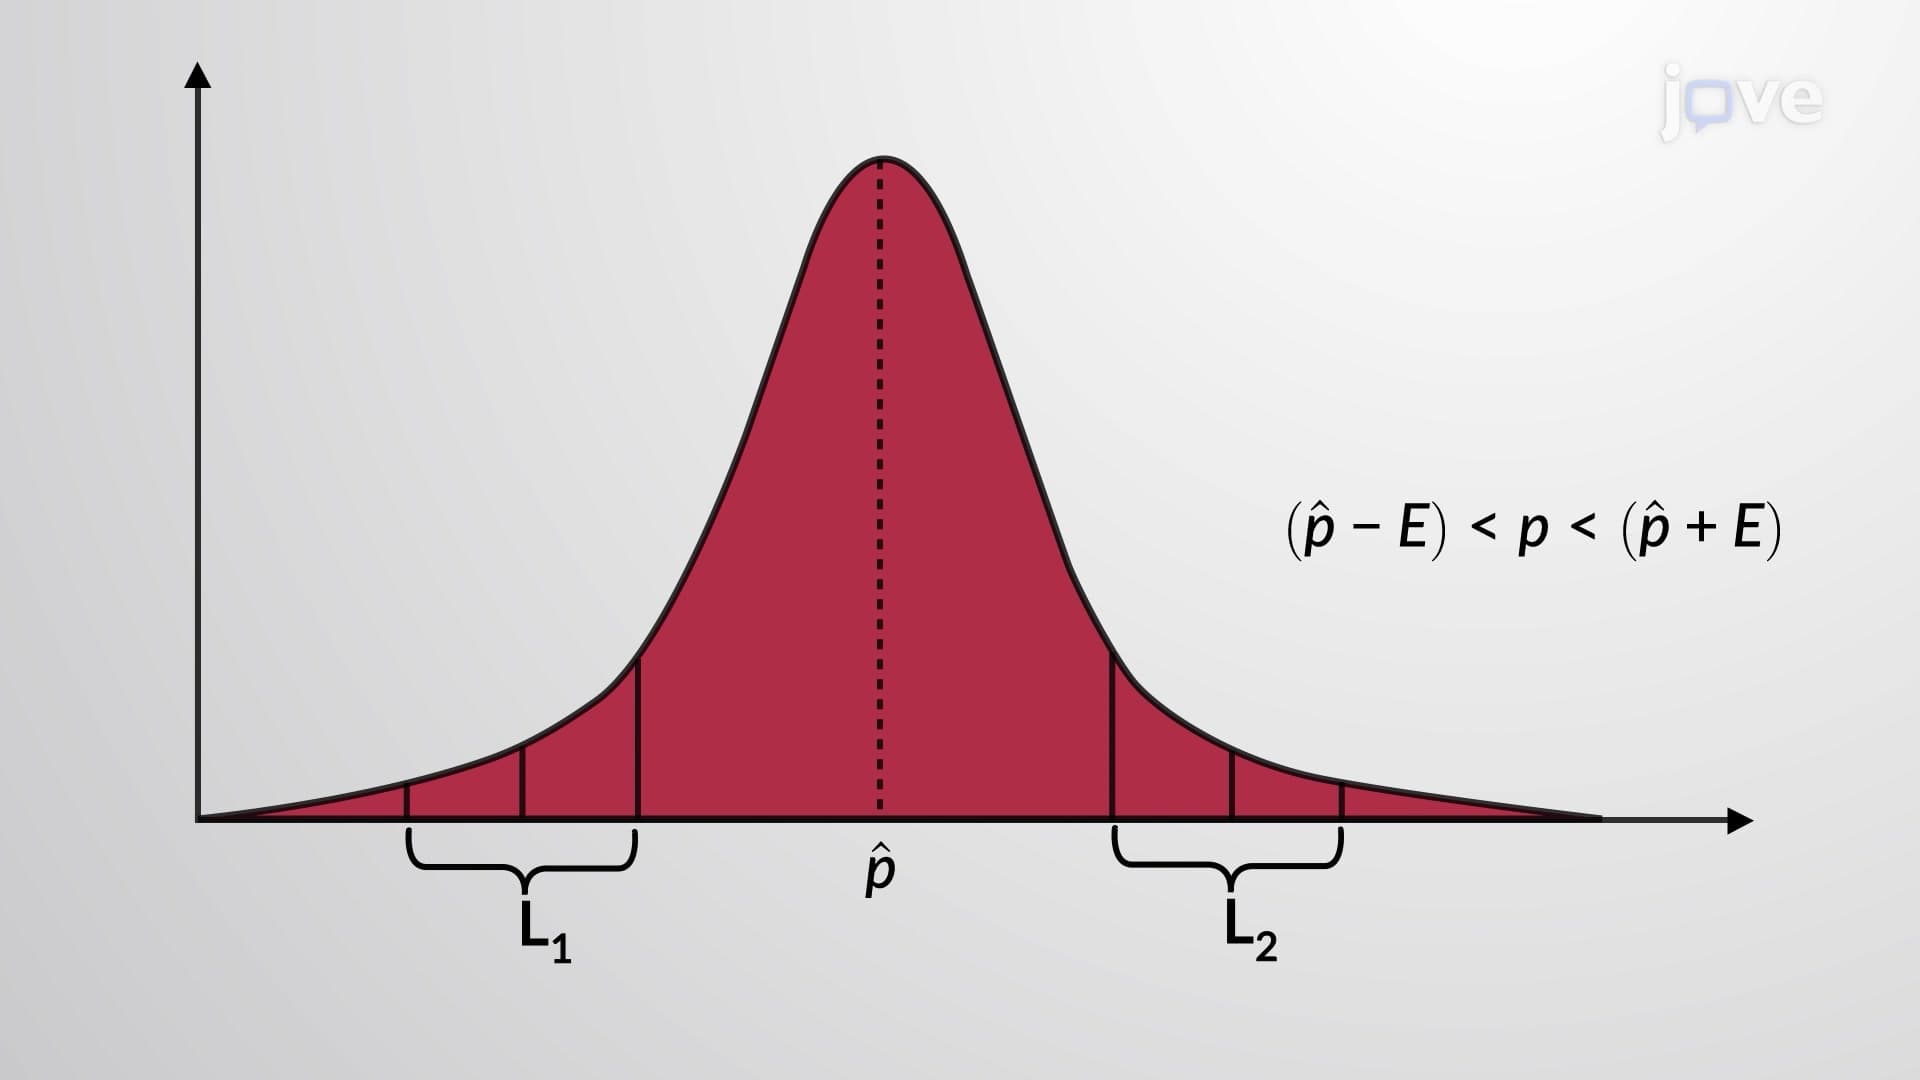 01:24
Confidence Coefficient
 01:02
Ranks
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 01:21
Friedman Two-way Analysis of Variance by Ranks