Related Experiment Video
Updated: Jun 26, 2026
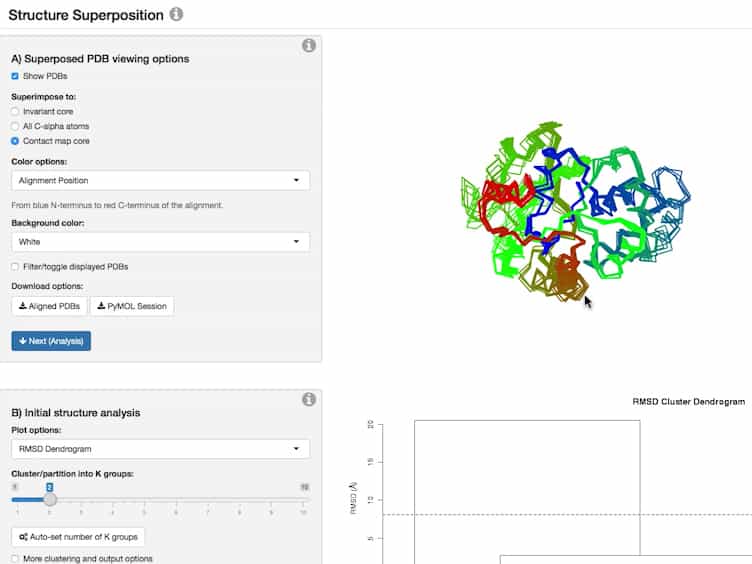

Investigating Protein Sequence-structure-dynamics Relationships with Bio3D-web
Published on: July 16, 2017
Accelerating approximate subsequence search on large protein sequence databases
1T. J. Watson Research, IBM, USA. jiyang@us.ibm.com

Abstract:
Bioinformatics has become an active research area in recent years. The amount of mapped sequences doubles every fourteen months. BLAST has been widely employed for retrieving sequences which has similar portion(s) to a given sequence. However, BLAST has to scan the entire database every time when a query is issued. This can be very time consuming especially when the database is large. In this paper, we study the problem on how to build a persistent index structure for protein sequences to support approximate match. The suffix tree has been proposed as a solution to index sequence database and has been deployed on organizing DNA sequences (Hunt et al. 2001). Unfortunately, it suffers from the problem of "memory bottleneck" that prevents it from being applied efficiently to a large database. The performance even degrades further for protein database due to a larger fanout at each node. Here, we employ an indexing structure, called BASS-tree, to support approximate match in sublinear time on a large protein database. We call this indexing method as sequence approximate match (SAM) index method. The search of approximate matches can be properly directed to the portion in the database with a high potential of matching quickly. It has been demonstrated in our experiments that the potential performance improvement is in an order of magnitude over alternative methods such as the BLAST algorithm and the suffix tree.
Related Concept Videos
 02:47
Protein Families
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 02:28
Leaky Scanning