Related Experiment Video
Updated: Aug 18, 2026

A Protocol for Computer-Based Protein Structure and Function Prediction
Published on: November 3, 2011
Scoredist: a simple and robust protein sequence distance estimator
Erik L L Sonnhammer1, Volker Hollich
1Center for Genomics and Bioinformatics, Karolinska Institutet, Berzelius väg 35, 171 77 Stockholm, Sweden. erik.sonnhammer@cgb.ki.se

Background:
Distance-based methods are popular for reconstructing evolutionary trees thanks to their speed and generality. A number of methods exist for estimating distances from sequence alignments, which often involves some sort of correction for multiple substitutions. The problem is to accurately estimate the number of true substitutions given an observed alignment. So far, the most accurate protein distance estimators have looked for the optimal matrix in a series of transition probability matrices, e.g. the Dayhoff series. The evolutionary distance between two aligned sequences is here estimated as the evolutionary distance of the optimal matrix. The optimal matrix can be found either by an iterative search for the Maximum Likelihood matrix, or by integration to find the Expected Distance. As a consequence, these methods are more complex to implement and computationally heavier than correction-based methods. Another problem is that the result may vary substantially depending on the evolutionary model used for the matrices. An ideal distance estimator should produce consistent and accurate distances independent of the evolutionary model used.
Results:
We propose a correction-based protein sequence estimator called Scoredist. It uses a logarithmic correction of observed divergence based on the alignment score according to the BLOSUM62 score matrix. We evaluated Scoredist and a number of optimal matrix methods using three evolutionary models for both training and testing Dayhoff, Jones-Taylor-Thornton, and Muller-Vingron, as well as Whelan and Goldman solely for testing. Test alignments with known distances between 0.01 and 2 substitutions per position (1-200 PAM) were simulated using ROSE. Scoredist proved as accurate as the optimal matrix methods, yet substantially more robust. When trained on one model but tested on another one, Scoredist was nearly always more accurate. The Jukes-Cantor and Kimura correction methods were also tested, but were substantially less accurate.
Conclusion:
The Scoredist distance estimator is fast to implement and run, and combines robustness with accuracy. Scoredist has been incorporated into the Belvu alignment viewer, which is available at ftp://ftp.cgb.ki.se/pub/prog/belvu/.
More Related Videos
 05:08
Application of I TASSER, trRosetta, UCSF Chimera, HADDOCK server, and HEX loria for De Novo and In Silico Design of Proteins
Published on: July 8, 2025
 16:02
Demonstration of the Sequence Alignment to Predict Across Species Susceptibility Tool for Rapid Assessment of Protein Conservation
Published on: February 10, 2023
Related Concept Videos
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
02:26Conservation of Protein Domains
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 02:15
Protein and Protein Structure
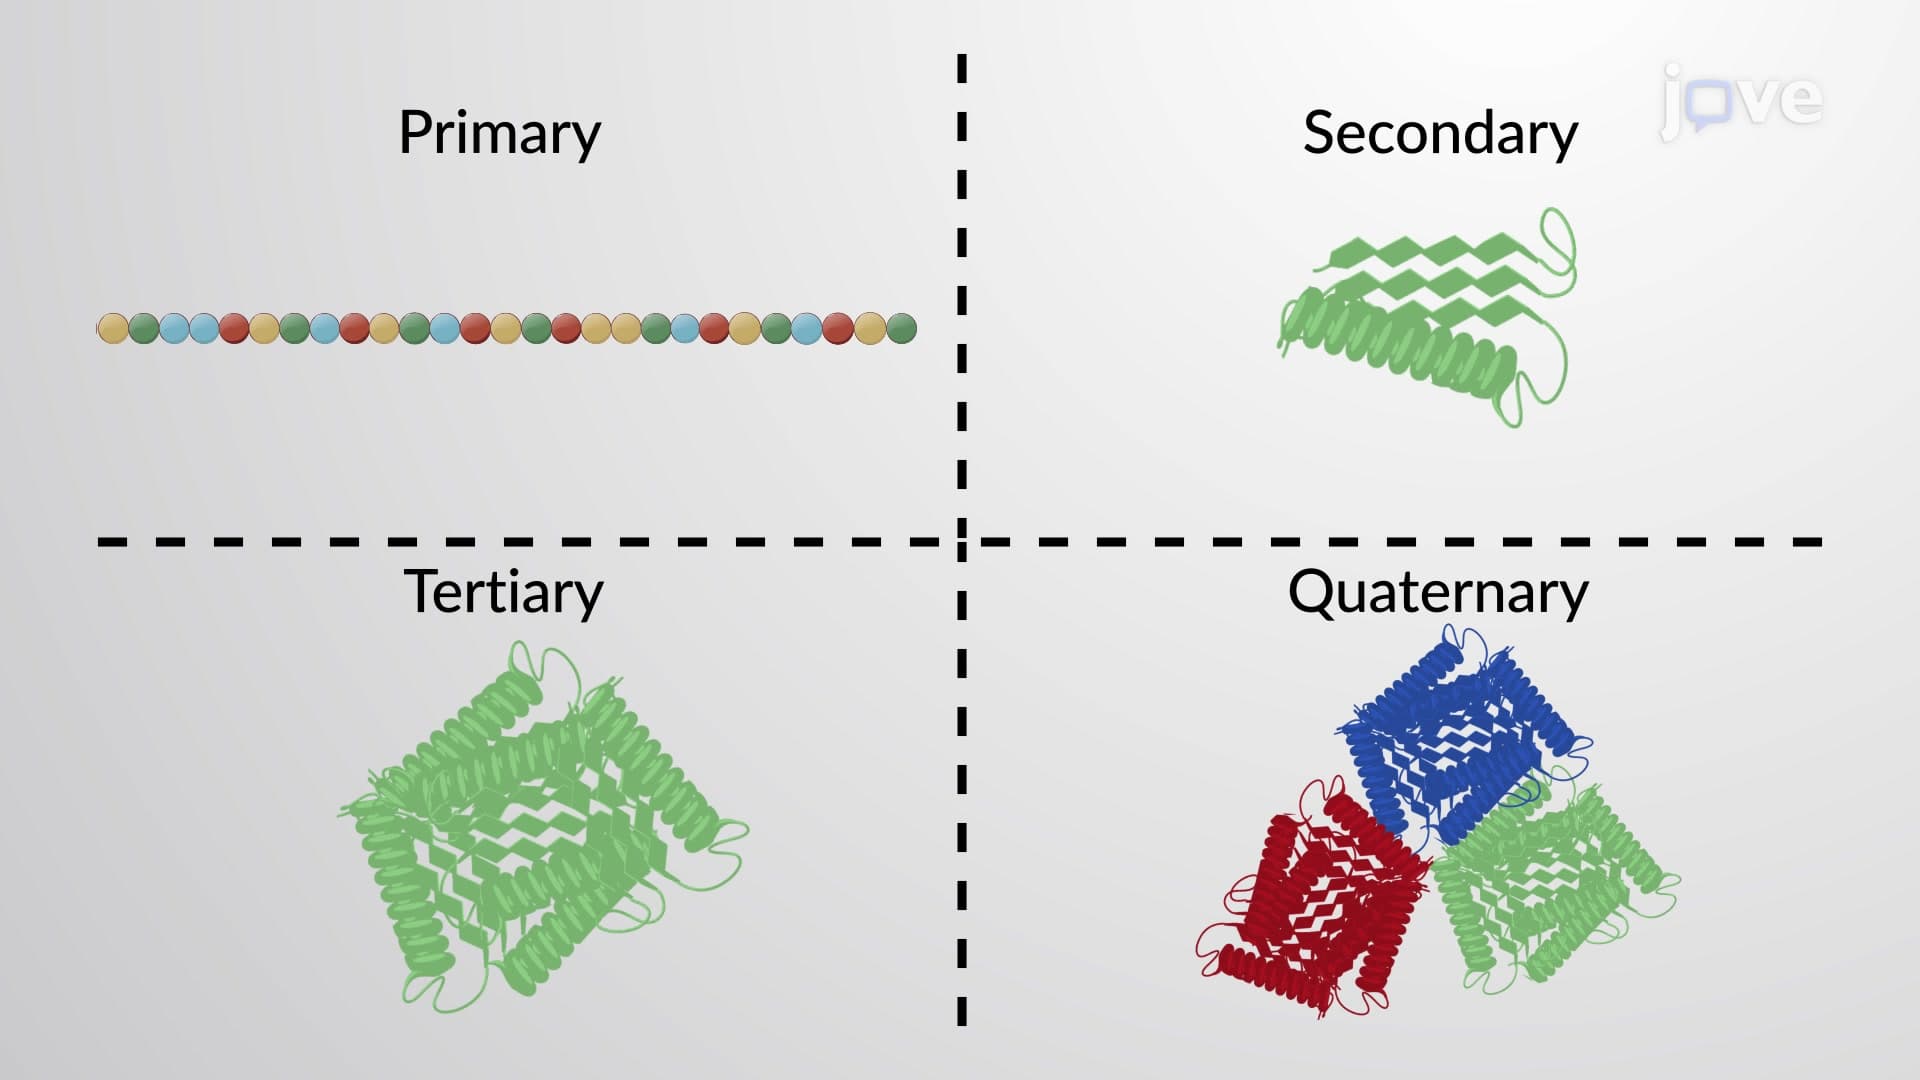
A protein's shape is critical to its function. For example, an enzyme can...
 02:51
Multi-species Conserved Sequences
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...
 01:13
Mean Absolute Deviation
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...