Related Experiment Video
Updated: Aug 18, 2026


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
Reproductive correlation and mean-variance scaling of reproductive output for a forest model
Ford Ballantyne1, Andrew J Kerkhoff
1Department of Biology, University of New Mexico, Albuquerque, NM 87131, USA. fballantyne@ucsd.edu

Abstract:
We analyse the mean-variance scaling of reproductive output for a previously published forest model. The model relates individual reproductive effort and pollen limitation to the degree of synchrony in reproduction throughout a forest. We show that the exponent of Taylor's power law reflects the degree of synchrony of reproduction because it indicates the covariance of reproductive behavior. Further, we are able to relate the three components of masting, individual variability, population variability and synchrony in reproductive output, using Taylor's power law. Therefore Taylor's power law can be used as a synoptic index of masting.
Related Concept Videos
 01:26
Estimating Population Standard Deviation
 01:16
Estimating Population Mean with Known Standard Deviation
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate + error bound)
The...
 01:19
Variation
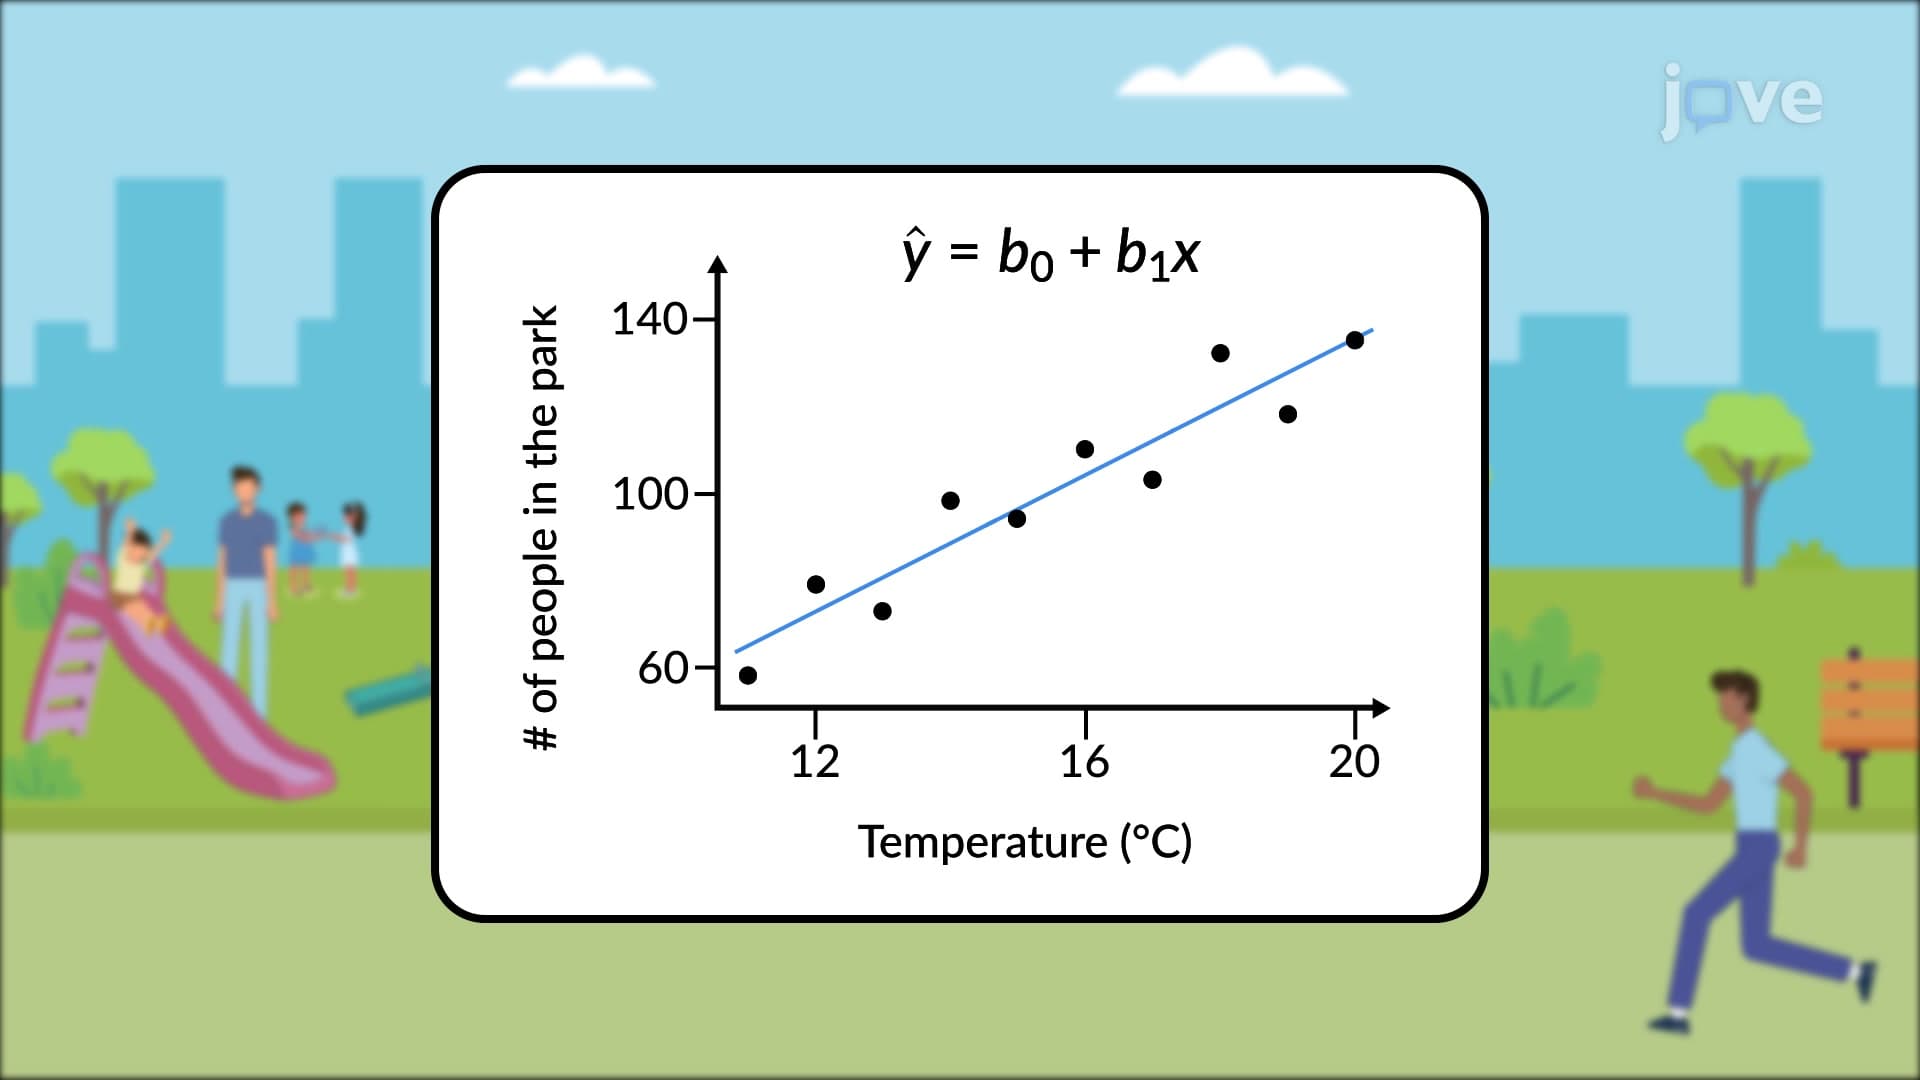
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:23
Correlation of Experimental Data
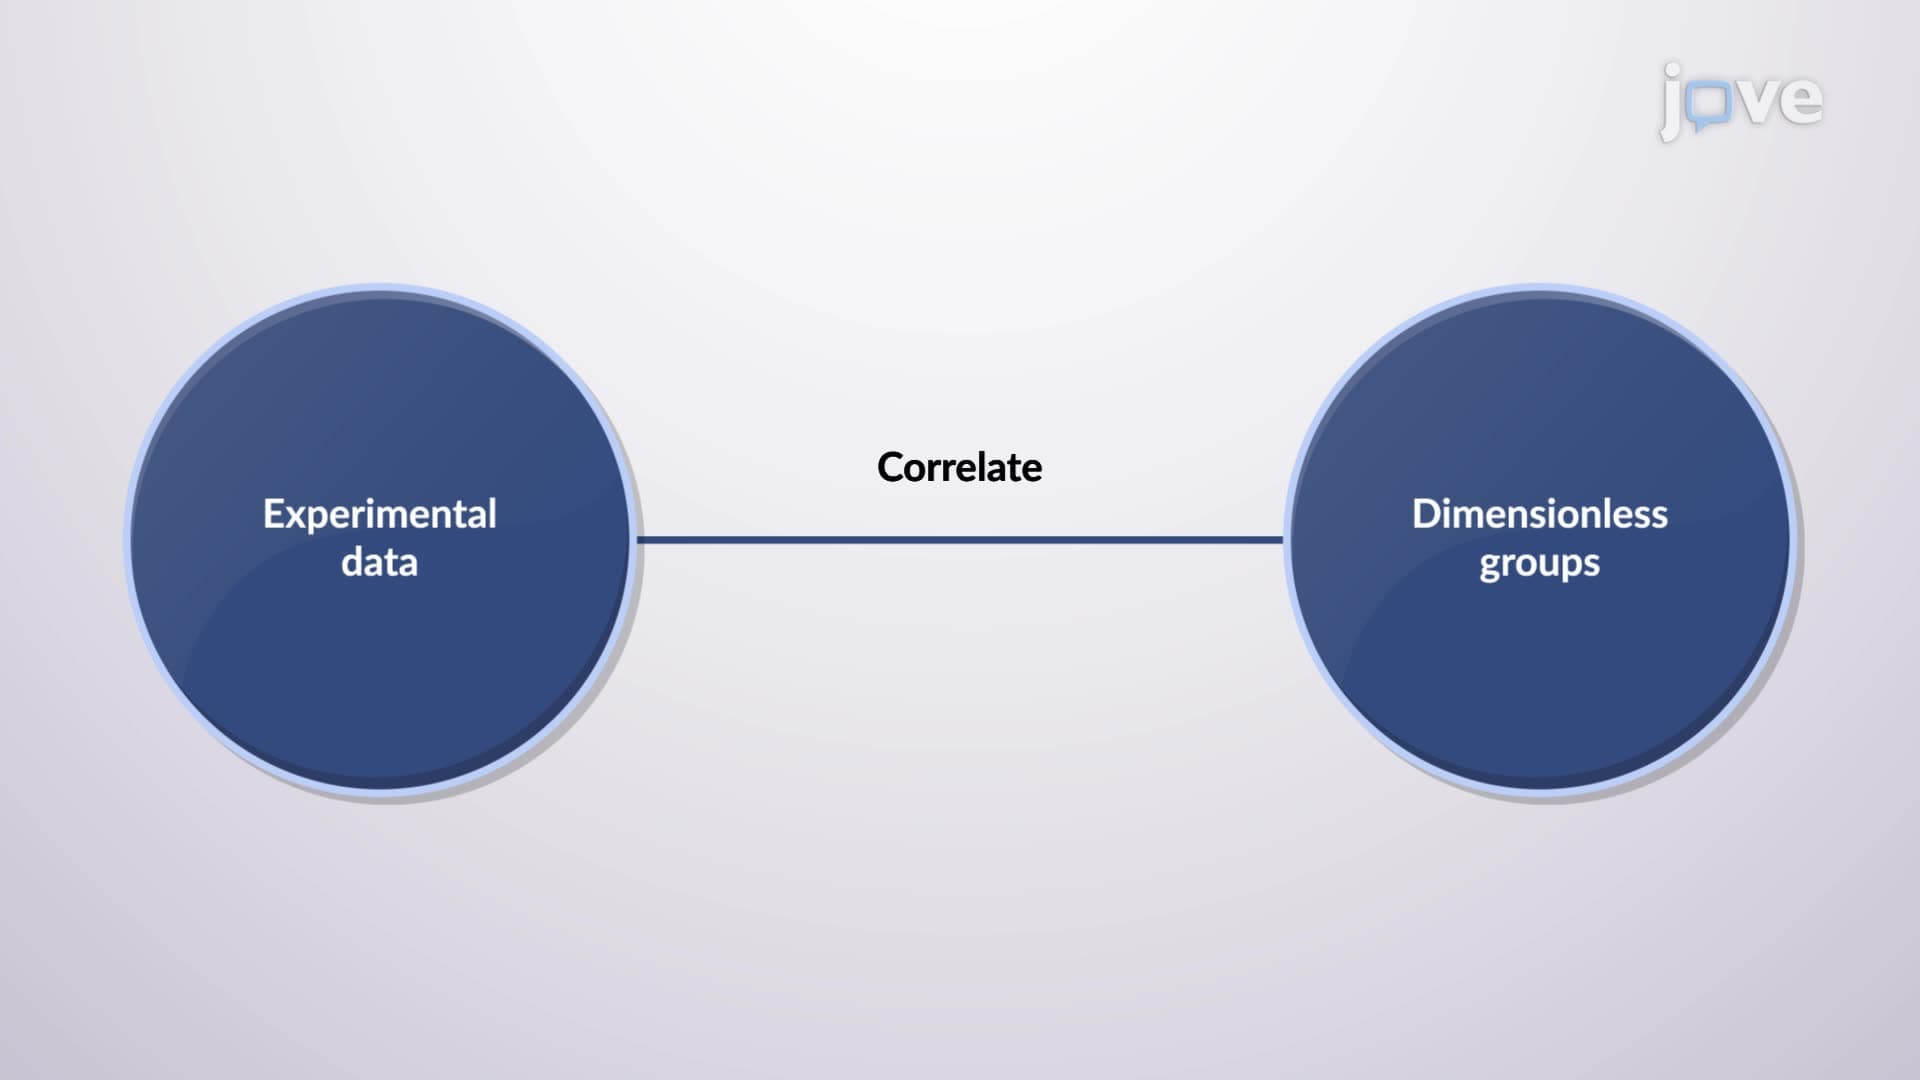
For example, a spherical particle moving through a viscous fluid experiences drag. Dimensional analysis shows that the drag force depends on the particle's diameter, velocity, and...
 01:12
Coefficient of Correlation
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the strength of the linear...
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...