Related Experiment Video
Updated: Aug 16, 2026

Profiling of Estrogen-regulated MicroRNAs in Breast Cancer Cells
Published on: February 21, 2014
Bias in the estimation of false discovery rate in microarray studies
Yudi Pawitan1, Karuturi R Krishna Murthy, Stefan Michiels
1Department of Medical Epidemiology and Biostatistics, Karolinska Institutet, Stockholm, Sweden. yudi.pawitan@meb.ki.se

Motivation:
The false discovery rate (FDR) provides a key statistical assessment for microarray studies. Its value depends on the proportion pi(0) of non-differentially expressed (non-DE) genes. In most microarray studies, many genes have small effects not easily separable from non-DE genes. As a result, current methods often overestimate pi(0) and FDR, leading to unnecessary loss of power in the overall analysis.
Methods:
For the common two-sample comparison we derive a natural mixture model of the test statistic and an explicit bias formula in the standard estimation of pi(0). We suggest an improved estimation of pi(0) based on the mixture model and describe a practical likelihood-based procedure for this purpose.
Results:
The analysis shows that a large bias occurs when pi(0) is far from 1 and when the non-centrality parameters of the distribution of the test statistic are near zero. The theoretical result also explains substantial discrepancies between non-parametric and model-based estimates of pi(0). Simulation studies indicate mixture-model estimates are less biased than standard estimates. The method is applied to breast cancer and lymphoma data examples.
Availability:
An R-package OCplus containing functions to compute pi(0) based on the mixture model, the resulting FDR and other operating characteristics of microarray data, is freely available at http://www.meb.ki.se/~yudpaw
Contact:
yudi.pawitan@meb.ki.se and alexander.ploner@meb.ki.se.
Insights
This study introduces a new mixture model to accurately estimate the proportion of non-differentially expressed genes (pi(0)) in microarray analysis. This improved estimation reduces bias and increases statistical power in identifying significant gene expression changes.
Area of Science:
- Genomics
- Statistical Bioinformatics
Background:
- The false discovery rate (FDR) is crucial for microarray studies, but its accuracy depends on estimating pi(0), the proportion of non-differentially expressed genes.
- Current methods often overestimate pi(0) and FDR, leading to reduced statistical power in identifying significant genes.
Purpose of the Study:
- To develop an improved method for estimating pi(0) in two-sample microarray comparisons.
- To address the bias in standard pi(0) estimation, particularly when pi(0) is far from 1 or test statistic non-centrality parameters are small.
Main Methods:
- Derived a natural mixture model for the test statistic in two-sample comparisons.
- Developed an explicit bias formula for standard pi(0) estimation.
- Proposed a practical, likelihood-based procedure for improved pi(0) estimation using the mixture model.
Main Results:
- Identified significant bias in standard pi(0) estimation under specific conditions.
- Demonstrated that mixture-model estimates of pi(0) are less biased than standard estimates through simulations.
- Explained discrepancies between non-parametric and model-based pi(0) estimates.
Conclusions:
- The proposed mixture model and likelihood-based procedure offer a more accurate estimation of pi(0) for microarray data.
- This improved estimation enhances the reliability of FDR calculations and increases statistical power.
- An R-package, OCplus, is available for implementing these methods.
Related Concept Videos
 02:34
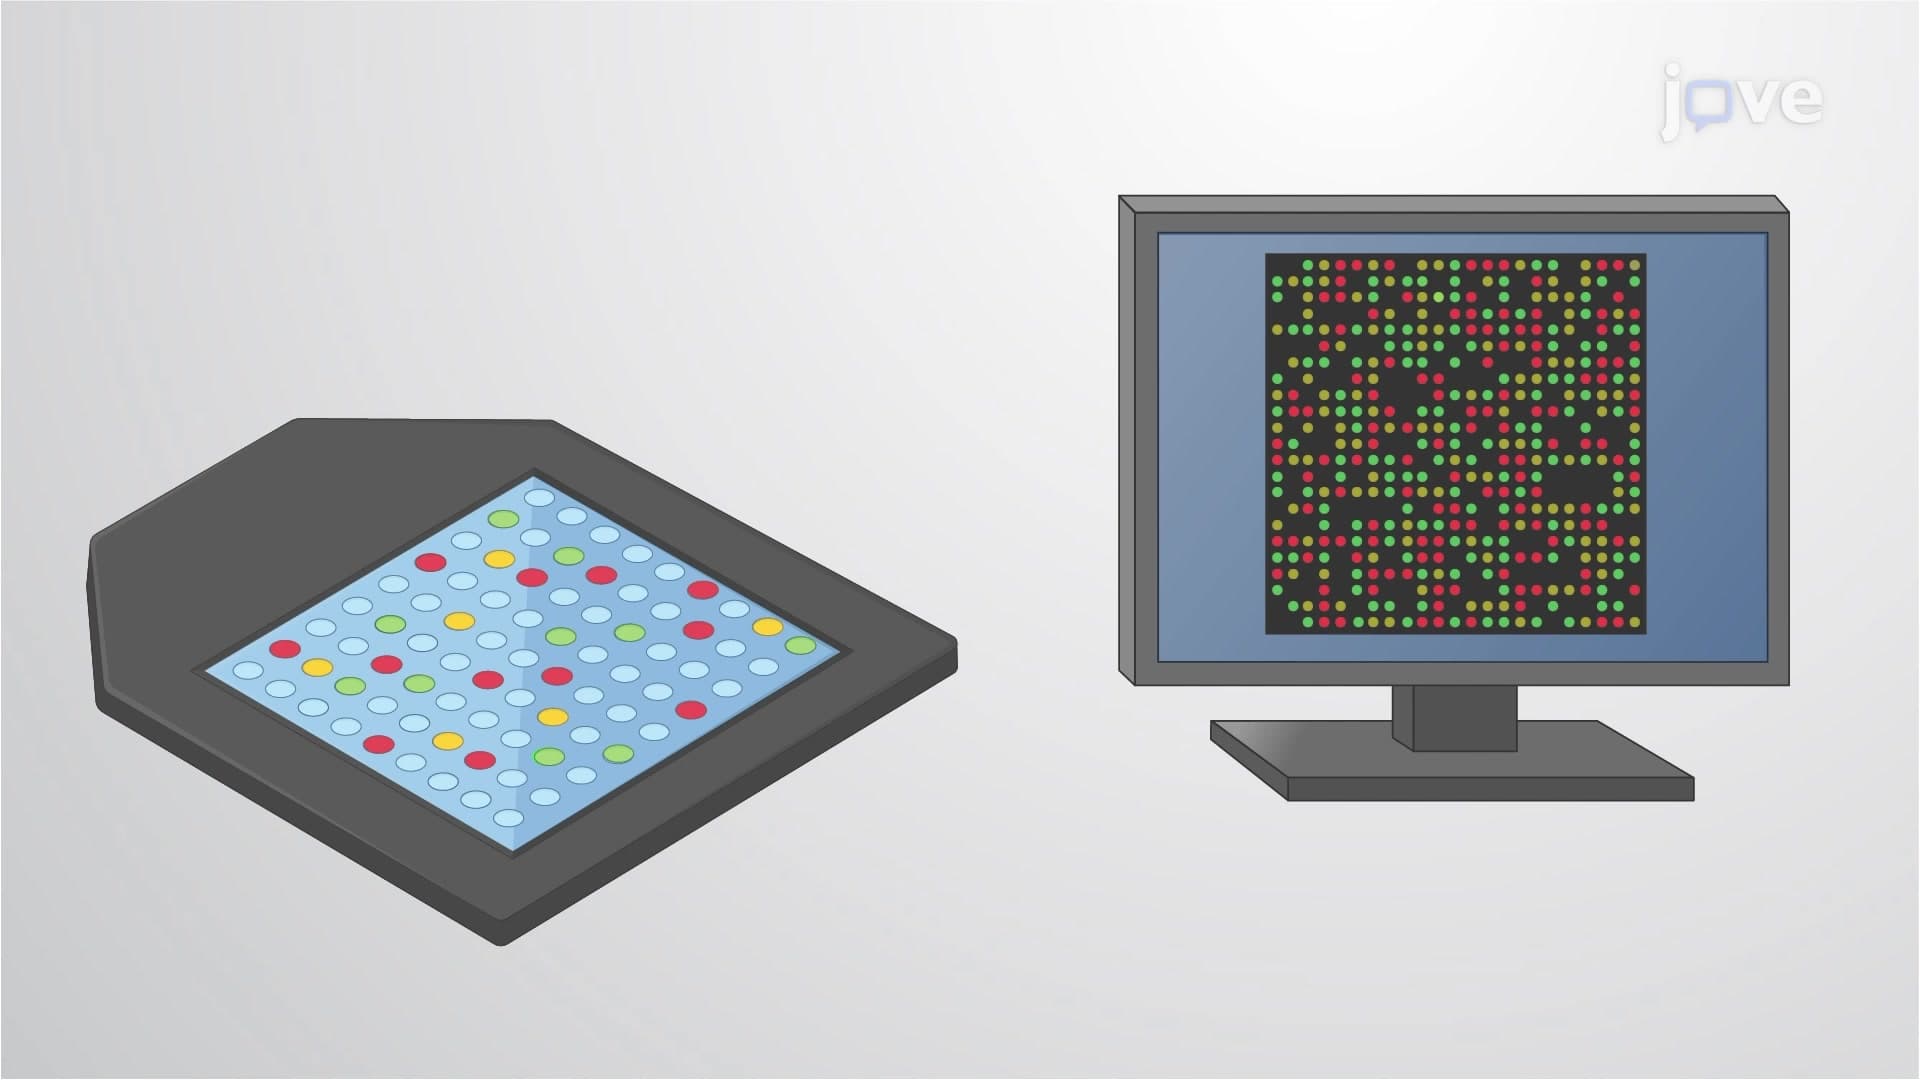
DNA Microarrays
 01:22
Bias
In statistics, a sampling bias is created when a sample is collected from a population, and some members of the population are not as likely to be chosen as others (remember, each member...
 01:29
Bias in Epidemiological Studies
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...