Related Experiment Video
Updated: Jul 31, 2026

O-cresol Concentration Online Measurement Based On Near Infrared Spectroscopy Via Partial Least Square Regression
Published on: November 8, 2019
Local lazy regression: making use of the neighborhood to improve QSAR predictions
Rajarshi Guha1, Debojyoti Dutta, Peter C Jurs
1Department of Chemistry, Pennsylvania State University, University Park, Pennsylvania 16802, USA. rxg218@psu.edu

Abstract:
Traditional quantitative structure-activity relationship (QSAR) models aim to capture global structure-activity trends present in a data set. In many situations, there may be groups of molecules which exhibit a specific set of features which relate to their activity or inactivity. Such a group of features can be said to represent a local structure-activity relationship. Traditional QSAR models may not recognize such local relationships. In this work, we investigate the use of local lazy regression (LLR), which obtains a prediction for a query molecule using its local neighborhood, rather than considering the whole data set. This modeling approach is especially useful for very large data sets because no a priori model need be built. We applied the technique to three biological data sets. In the first case, the root-mean-square error (RMSE) for an external prediction set was 0.94 log units versus 0.92 log units for the global model. However, LLR was able to characterize a specific group of anomalous molecules with much better accuracy (0.64 log units versus 0.70 log units for the global model). For the second data set, the LLR technique resulted in a decrease in RMSE from 0.36 log units to 0.31 log units for the external prediction set. In the third case, we obtained an RMSE of 2.01 log units versus 2.16 log units for the global model. In all cases, LLR led to a few observations being poorly predicted compared to the global model. We present an analysis of why this was observed and possible improvements to the local regression approach.

Related Concept Videos
 01:52
Regression Toward the Mean
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:20
Calibration Curves: Linear Least Squares
For data that follow a straight line, the standard method for fitting is the linear...
 01:23
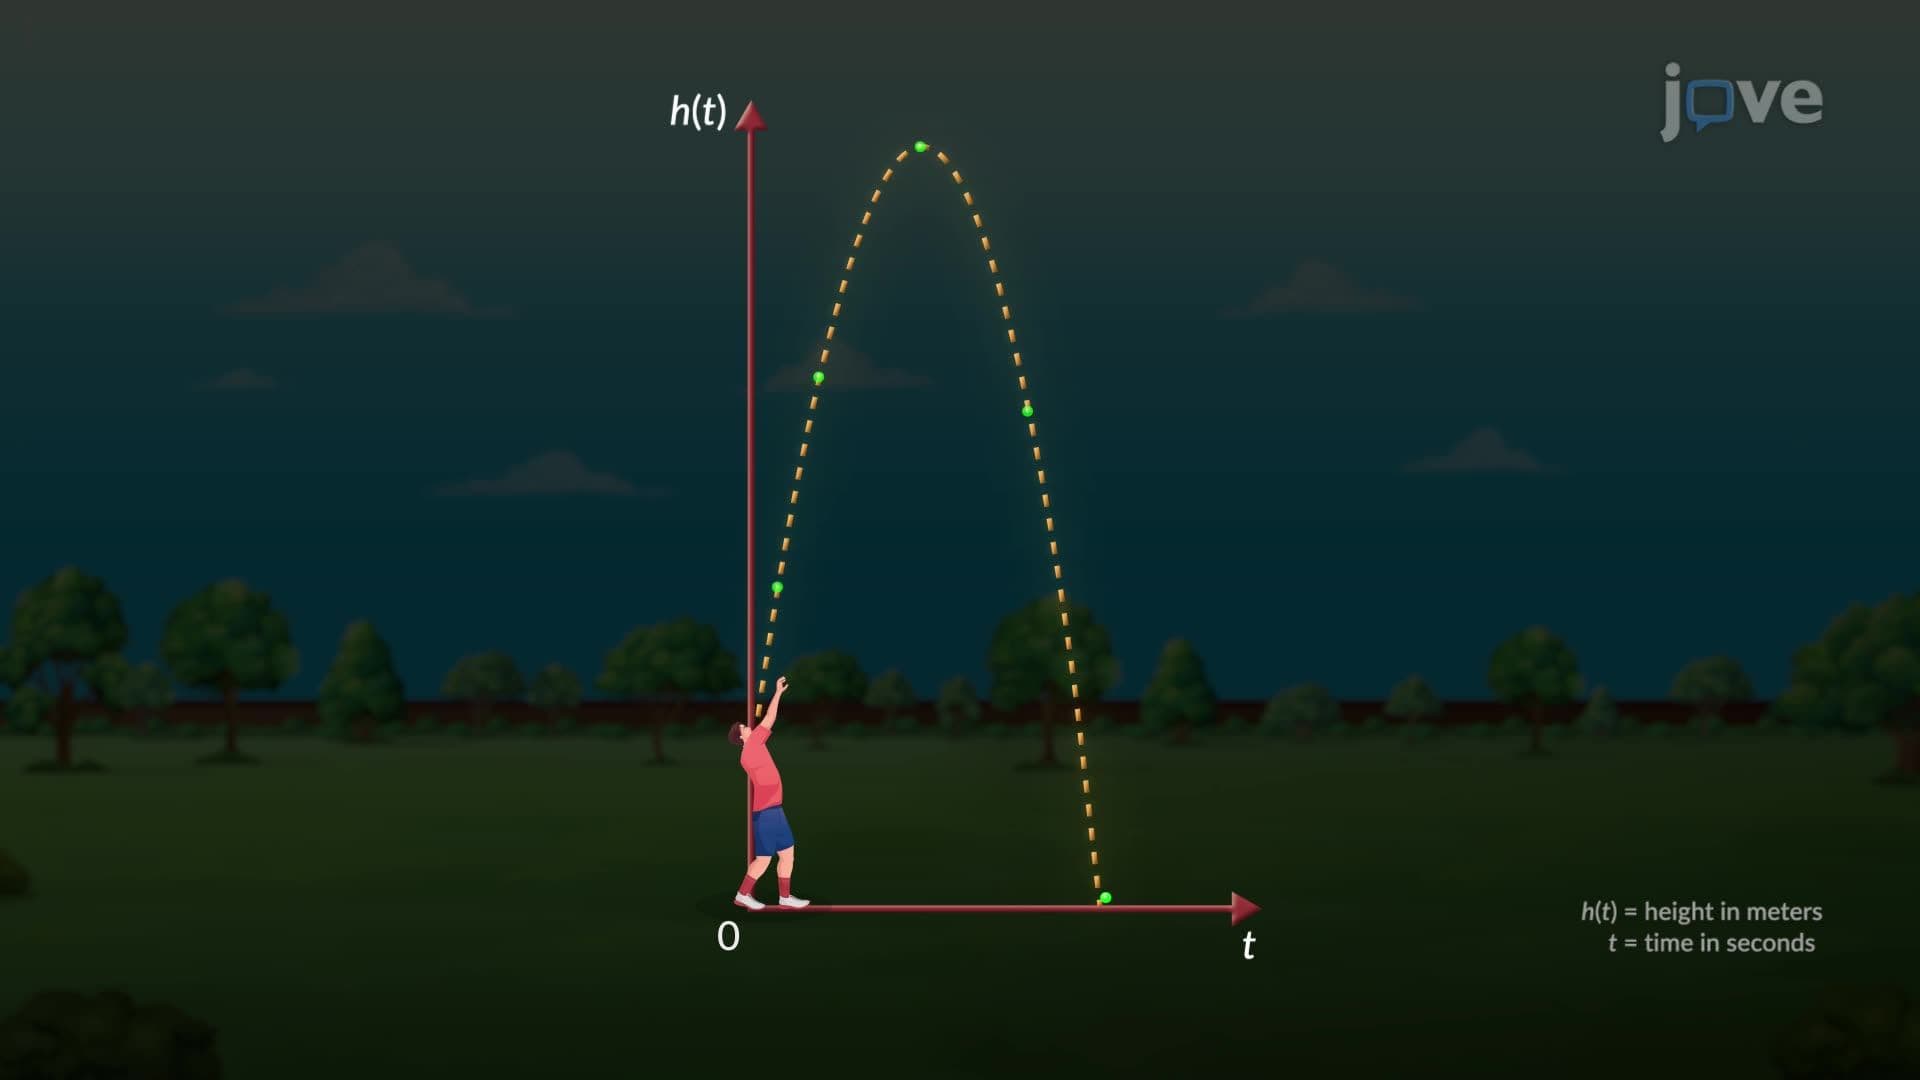
Quadratic Models
 01:23
Linear Approximations