Related Experiment Video
Updated: Jul 20, 2026


Inverse Probability of Treatment Weighting (Propensity Score) using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
Using the outcome for imputation of missing predictor values was preferred
Karel G M Moons1, Rogier A R T Donders, Theo Stijnen
1Julius Center for Health Sciences and General Practice, University Medical Center, Utrecht, P.O. Box 80035, 3508 GA Utrecht, The Netherlands. K.G.M.Moons@umcutrecht.nl

Background And Objective:
Epidemiologic studies commonly estimate associations between predictors (risk factors) and outcome. Most software automatically exclude subjects with missing values. This commonly causes bias because missing values seldom occur completely at random (MCAR) but rather selectively based on other (observed) variables, missing at random (MAR). Multiple imputation (MI) of missing predictor values using all observed information including outcome is advocated to deal with selective missing values. This seems a self-fulfilling prophecy.
Methods:
We tested this hypothesis using data from a study on diagnosis of pulmonary embolism. We selected five predictors of pulmonary embolism without missing values. Their regression coefficients and standard errors (SEs) estimated from the original sample were considered as "true" values. We assigned missing values to these predictors--both MCAR and MAR--and repeated this 1,000 times using simulations. Per simulation we multiple imputed the missing values without and with the outcome, and compared the regression coefficients and SEs to the truth.
Results:
Regression coefficients based on MI including outcome were close to the truth. MI without outcome yielded very biased--underestimated--coefficients. SEs and coverage of the 90% confidence intervals were not different between MI with and without outcome. Results were the same for MCAR and MAR.
Conclusion:
For all types of missing values, imputation of missing predictor values using the outcome is preferred over imputation without outcome and is no self-fulfilling prophecy.
Related Concept Videos
 01:09
Truncation in Survival Analysis
Left truncation occurs when individuals who experienced the event of interest before a certain time are not included in the study. This is often due to a "delayed entry" into the study where only those who survive until a certain entry point are observed.
 01:24
Kaplan-Meier Approach
 01:15
Assumptions of Survival Analysis
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:09
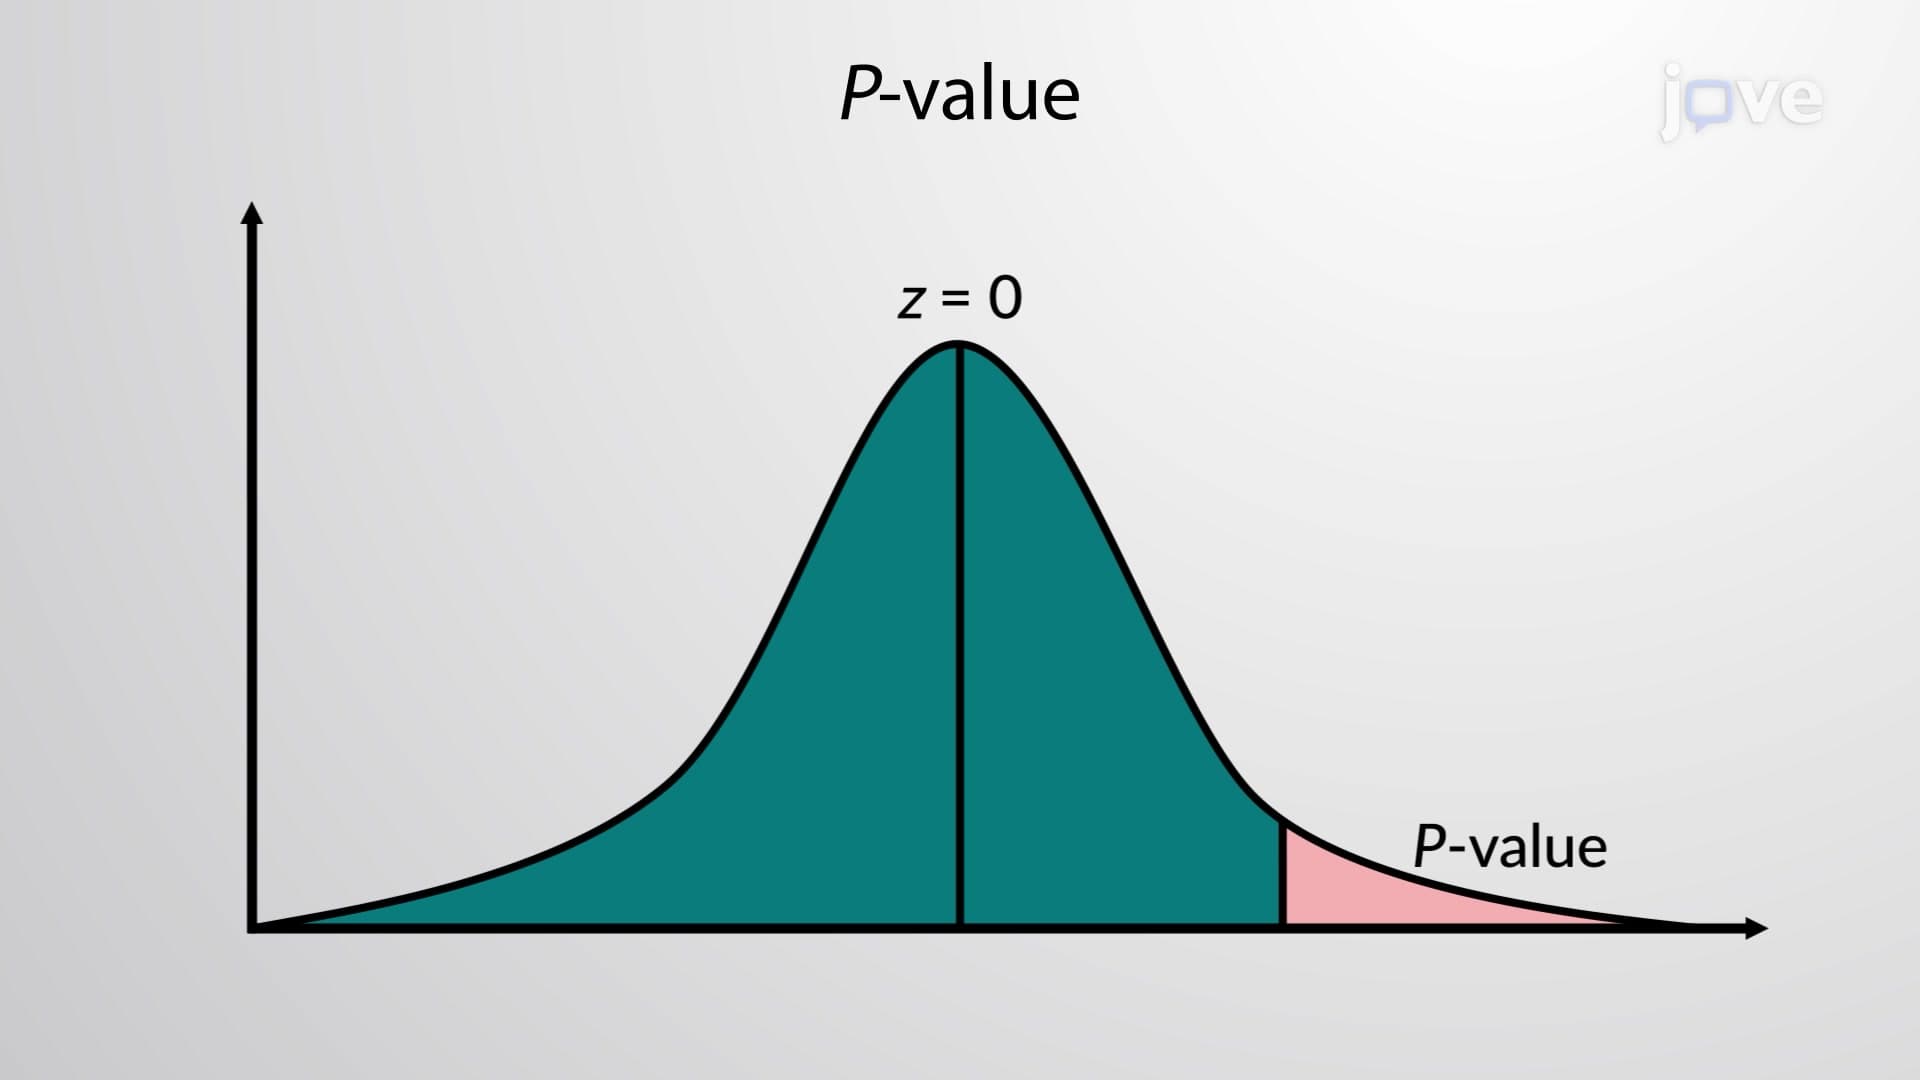
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:00
Detection of Gross Error: The Q Test