Related Experiment Video
Updated: Jul 19, 2026
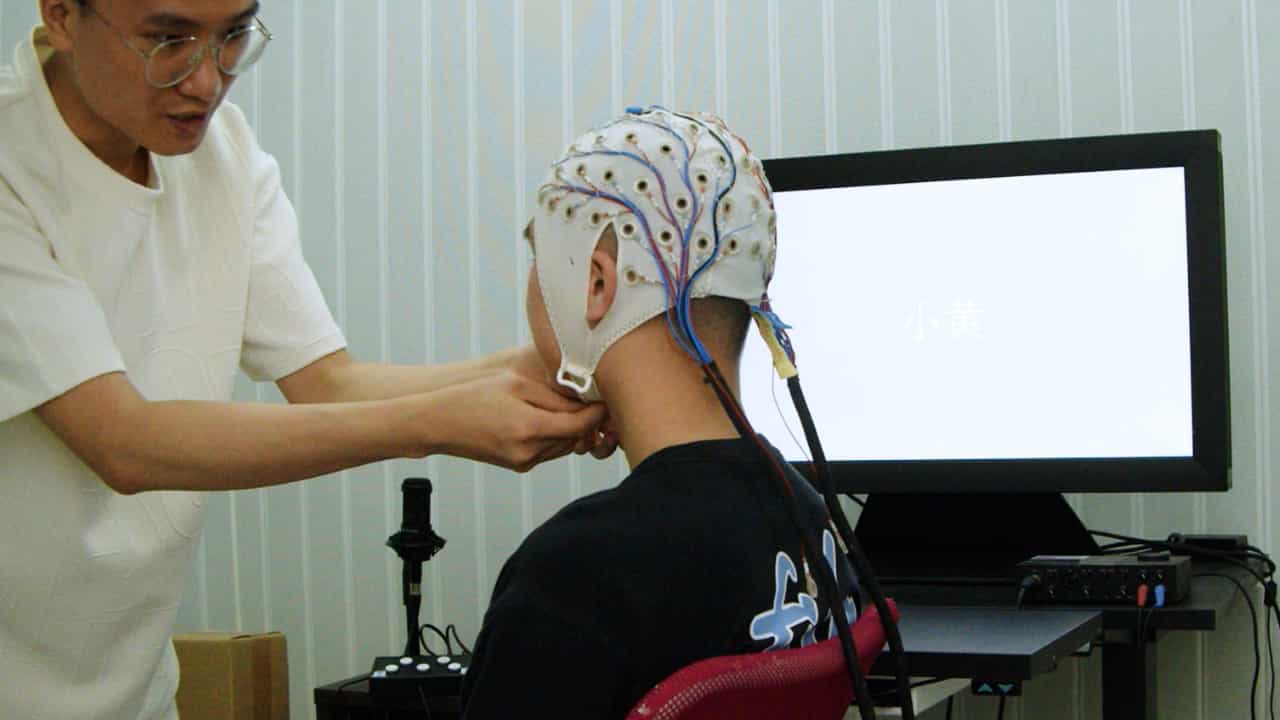
Memorization-Based Training and Testing Paradigm for Robust Vocal Identity Recognition in Expressive Speech Using Event-Related Potentials Analysis
Published on: August 9, 2024
Performance enhancement for audio-visual speaker identification using dynamic facial muscle model
Vahid Asadpour1, Farzad Towhidkhah, Mohammad Mehdi Homayounpour
1Department of Biomedical Engineering, Amirkabir University of Technology, Tehran, Iran. asadpour@aut.ac.ir

Abstract:
Science of human identification using physiological characteristics or biometry has been of great concern in security systems. However, robust multimodal identification systems based on audio-visual information has not been thoroughly investigated yet. Therefore, the aim of this work to propose a model-based feature extraction method which employs physiological characteristics of facial muscles producing lip movements. This approach adopts the intrinsic properties of muscles such as viscosity, elasticity, and mass which are extracted from the dynamic lip model. These parameters are exclusively dependent on the neuro-muscular properties of speaker; consequently, imitation of valid speakers could be reduced to a large extent. These parameters are applied to a hidden Markov model (HMM) audio-visual identification system. In this work, a combination of audio and video features has been employed by adopting a multistream pseudo-synchronized HMM training method. Noise robust audio features such as Mel-frequency cepstral coefficients (MFCC), spectral subtraction (SS), and relative spectra perceptual linear prediction (J-RASTA-PLP) have been used to evaluate the performance of the multimodal system once efficient audio feature extraction methods have been utilized. The superior performance of the proposed system is demonstrated on a large multispeaker database of continuously spoken digits, along with a sentence that is phonetically rich. To evaluate the robustness of algorithms, some experiments were performed on genetically identical twins. Furthermore, changes in speaker voice were simulated with drug inhalation tests. In 3 dB signal to noise ratio (SNR), the dynamic muscle model improved the identification rate of the audio-visual system from 91 to 98%. Results on identical twins revealed that there was an apparent improvement on the performance for the dynamic muscle model-based system, in which the identification rate of the audio-visual system was enhanced from 87 to 96%.
Related Concept Videos
 01:14
Muscles for Facial Expressions
 01:24
Facial Feedback Hypothesis