Related Experiment Video
Updated: Jul 19, 2026


An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
Quantile-function based null distribution in resampling based multiple testing
Mark J van der Laan1, Alan E Hubbard
1Division of Biostatistics, School of Public Health, University of California, Berkeley, CA, USA. laan@stat.berkeley.edu

Abstract:
Simultaneously testing a collection of null hypotheses about a data generating distribution based on a sample of independent and identically distributed observations is a fundamental and important statistical problem involving many applications. Methods based on marginal null distributions (i.e., marginal p-values) are attractive since the marginal p-values can be based on a user supplied choice of marginal null distributions and they are computationally trivial, but they, by necessity, are known to either be conservative or to rely on assumptions about the dependence structure between the test-statistics. Re-sampling based multiple testing (Westfall and Young, 1993) involves sampling from a joint null distribution of the test-statistics, and controlling (possibly in a, for example, step-down fashion) the user supplied type-I error rate under this joint null distribution for the test-statistics. A generally asymptotically valid null distribution avoiding the need for the subset pivotality condition for the vector of test-statistics was proposed in Pollard, van der Laan (2003) for null hypotheses about general real valued parameters. This null distribution was generalized in Dudoit, vanderLaan, Pollard (2004) to general null hypotheses and test-statistics. In ongoing recent work van der Laan, Hubbard (2005), we propose a new generally asymptotically valid null distribution for the test-statistics and a corresponding bootstrap estimate, whose marginal distributions are user supplied, and can thus be set equal to the (most powerful) marginal null distributions one would use in univariate testing to obtain a p-value. Previous proposed null distributions either relied on a restrictive subset pivotality condition (Westfall and Young) or did not guarantee this latter property (Dudoit, vanderLaan, Pollard, 2004). It is argued and illustrated that the resulting new re-sampling based multiple testing methods provide more accurate control of the wished Type-I error in finite samples and are more powerful. We establish formal results and investigate the practical performance of this methodology in a simulation and data analysis.
Related Concept Videos
 01:26
Distributions to Estimate Population Parameter
 01:15
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
 01:28
Introduction to Nonparametric Statistics
One of...
 01:16
Critical Region, Critical Values and Significance Level
In hypothesis testing, a sample statistic is converted to a test statistic using z, t, or chi-square distribution. A critical region is an area under the curve in probability distributions demarcated by the critical value. When the test statistic falls in this region, it suggests that the null hypothesis must be rejected. As this region contains all those values of the test...
 01:32
Probability Distributions
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson probability...
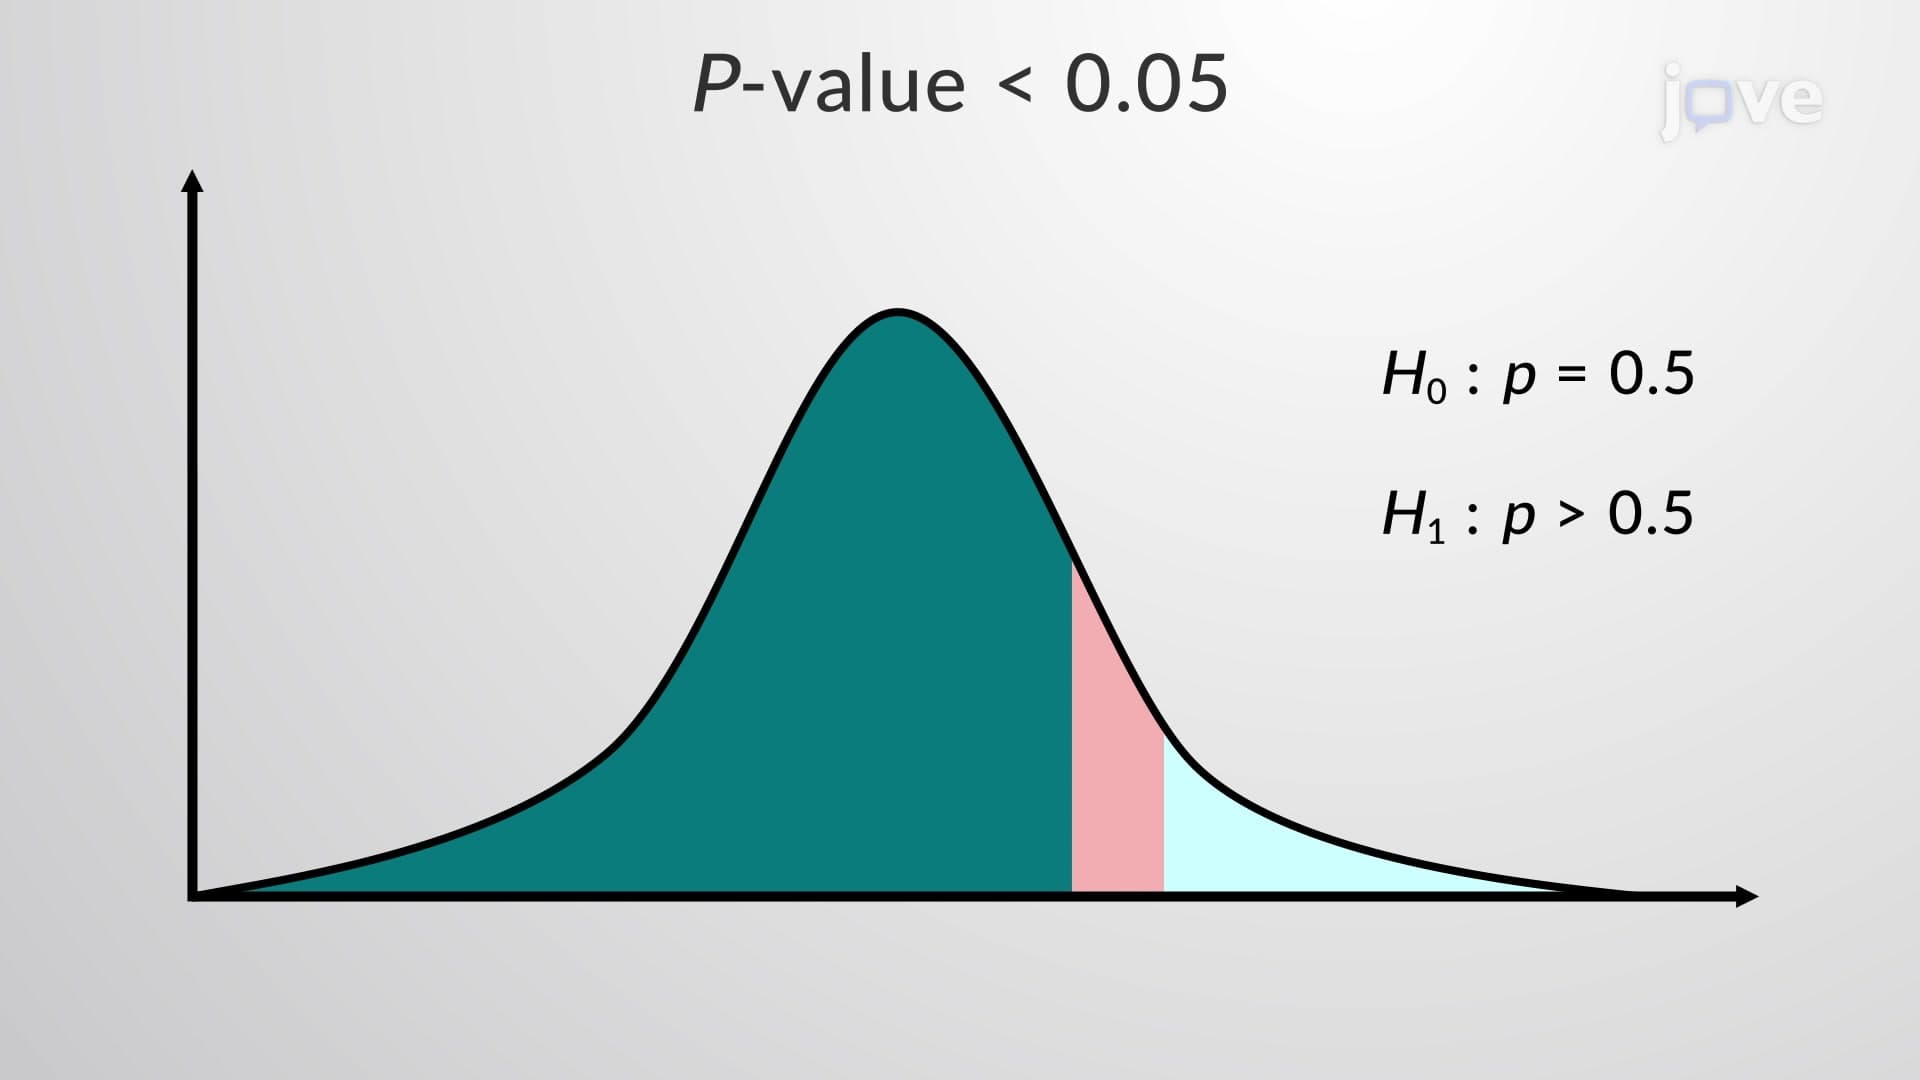 01:10
P-value
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more unlikely...