Related Experiment Video
Updated: Jul 14, 2026
Creating Objects and Object Categories for Studying Perception and Perceptual Learning
Published on: November 2, 2012
Information discriminant analysis: feature extraction with an information-theoretic objective
1Department of Biomedical Engineering, University of California, Irvine, 3120 Natural Sciences II, Irvine, CA 92697-2715, USA. znenadic@uci.edu

Abstract:
Using elementary information-theoretic tools, we develop a novel technique for linear transformation from the space of observations into a low-dimensional (feature) subspace for the purpose of classification. The technique is based on a numerical optimization of an information-theoretic objective function, which can be computed analytically. The advantages of the proposed method over several other techniques are discussed and the conditions under which the method reduces to linear discriminant analysis are given. We show that the novel objective function enjoys many of the properties of the mutual information and the Bayes error and we give sufficient conditions for the method to be Bayes-optimal. Since the objective function is maximized numerically, we show how the calculations can be accelerated to yield feasible solutions. The performance of the method compares favorably to other linear discriminant-based feature extraction methods on a number of simulated and real-world data sets.

Related Concept Videos
 01:14
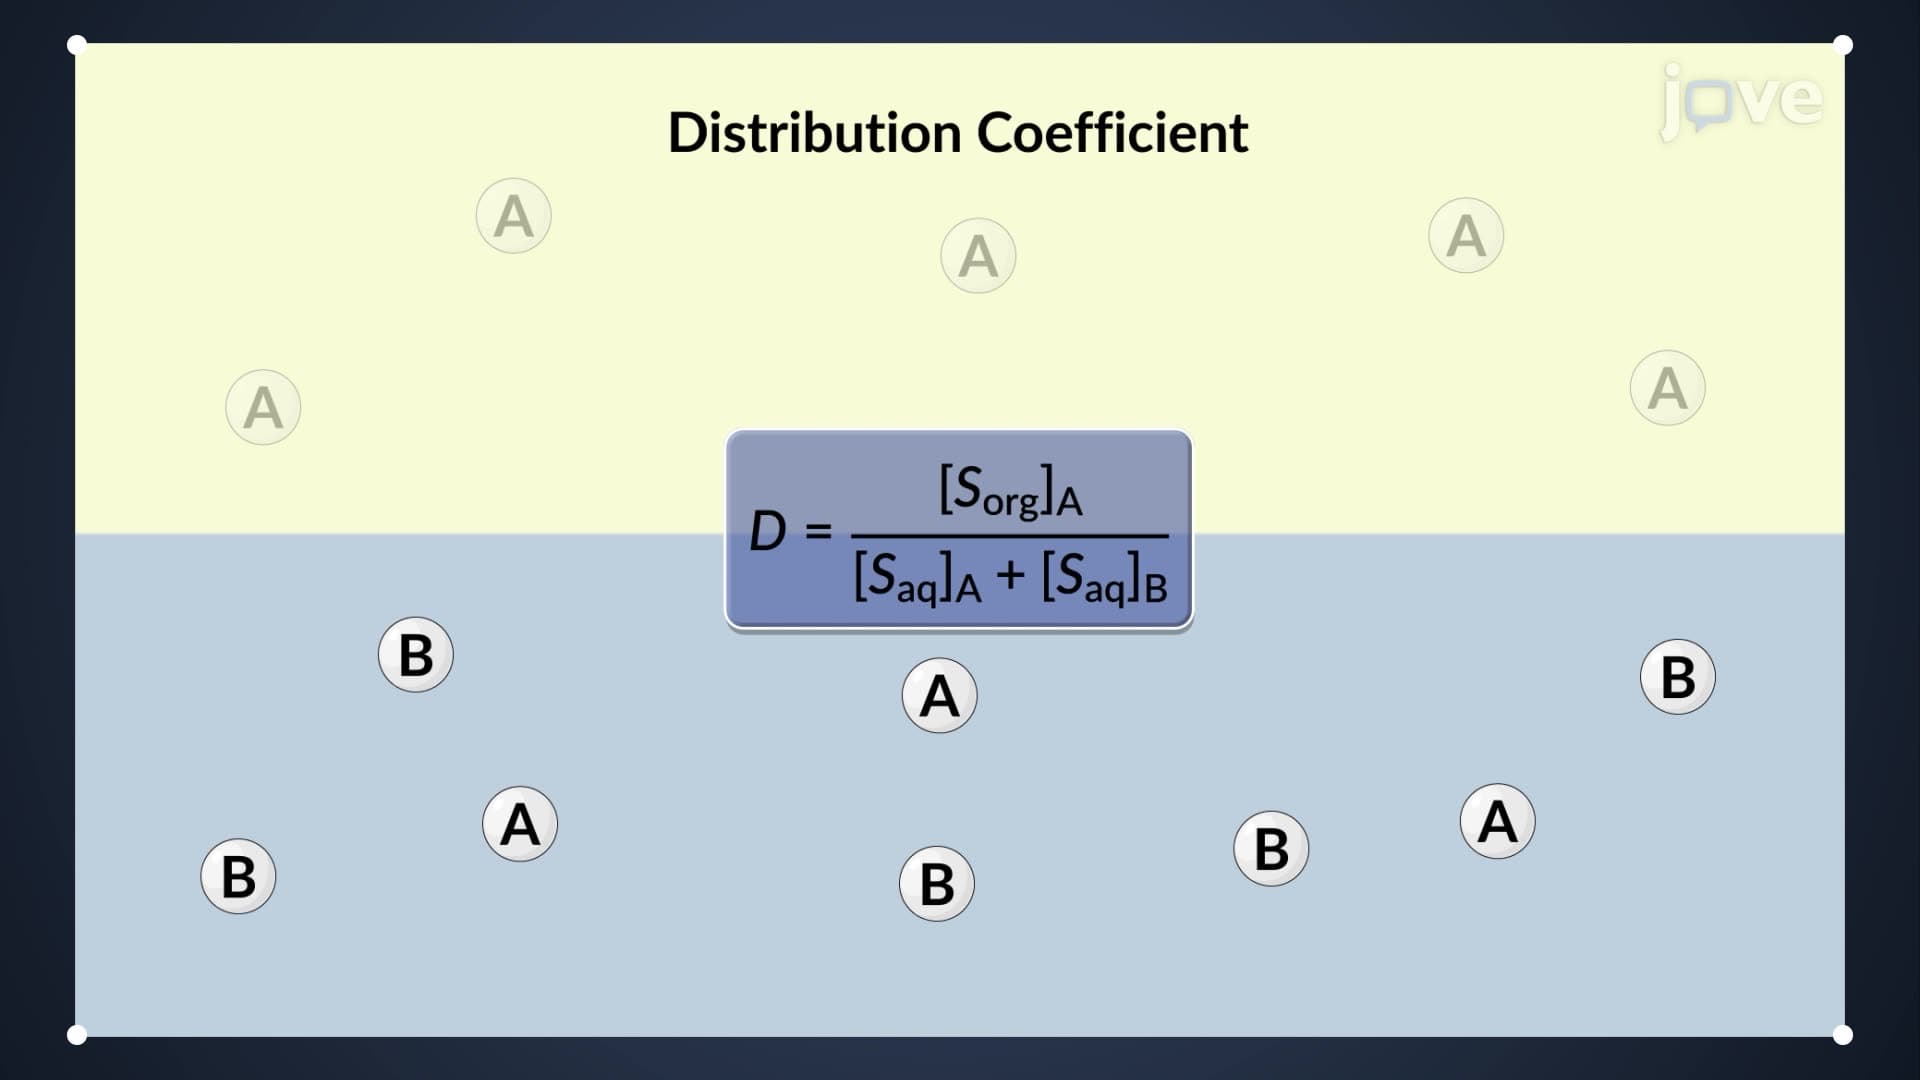
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an organic...
 01:08
Outliers and Influential Points
 01:05
Difference from Background: Limit of Detection
The LOD indicates the presence or absence...
 02:01
Factorial Design
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
 01:19
Expected Frequencies in Goodness-of-Fit Tests