Predicting and improving the protein sequence alignment quality by support vector regression
Related Experiment Video
Updated: Jul 9, 2026

Optimization of Synthetic Proteins: Identification of Interpositional Dependencies Indicating Structurally and/or Functionally Linked Residues
Published on: July 14, 2015
Minho Lee1, Chan-seok Jeong, Dongsup Kim
1Department of Bio and Brain Engineering, Korea Advanced Institute of Science and Technology, Daejeon, Republic of Korea. MinhoLee@kaist.edu

Background:
For successful protein structure prediction by comparative modeling, in addition to identifying a good template protein with known structure, obtaining an accurate sequence alignment between a query protein and a template protein is critical. It has been known that the alignment accuracy can vary significantly depending on our choice of various alignment parameters such as gap opening penalty and gap extension penalty. Because the accuracy of sequence alignment is typically measured by comparing it with its corresponding structure alignment, there is no good way of evaluating alignment accuracy without knowing the structure of a query protein, which is obviously not available at the time of structure prediction. Moreover, there is no universal alignment parameter option that would always yield the optimal alignment.
Results:
In this work, we develop a method to predict the quality of the alignment between a query and a template. We train the support vector regression (SVR) models to predict the MaxSub scores as a measure of alignment quality. The alignment between a query protein and a template of length n is transformed into a (n + 1)-dimensional feature vector, then it is used as an input to predict the alignment quality by the trained SVR model. Performance of our work is evaluated by various measures including Pearson correlation coefficient between the observed and predicted MaxSub scores. Result shows high correlation coefficient of 0.945. For a pair of query and template, 48 alignments are generated by changing alignment options. Trained SVR models are then applied to predict the MaxSub scores of those and to select the best alignment option which is chosen specifically to the query-template pair. This adaptive selection procedure results in 7.4% improvement of MaxSub scores, compared to those when the single best parameter option is used for all query-template pairs.
Conclusion:
The present work demonstrates that the alignment quality can be predicted with reasonable accuracy. Our method is useful not only for selecting the optimal alignment parameters for a chosen template based on predicted alignment quality, but also for filtering out problematic templates that are not suitable for structure prediction due to poor alignment accuracy. This is implemented as a part in FORECAST, the server for fold-recognition and is freely available on the web at http://pbil.kaist.ac.kr/forecast.

Related Concept Videos
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 01:29
Protein Folding Quality Check in the RER
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 02:15
Protein and Protein Structure
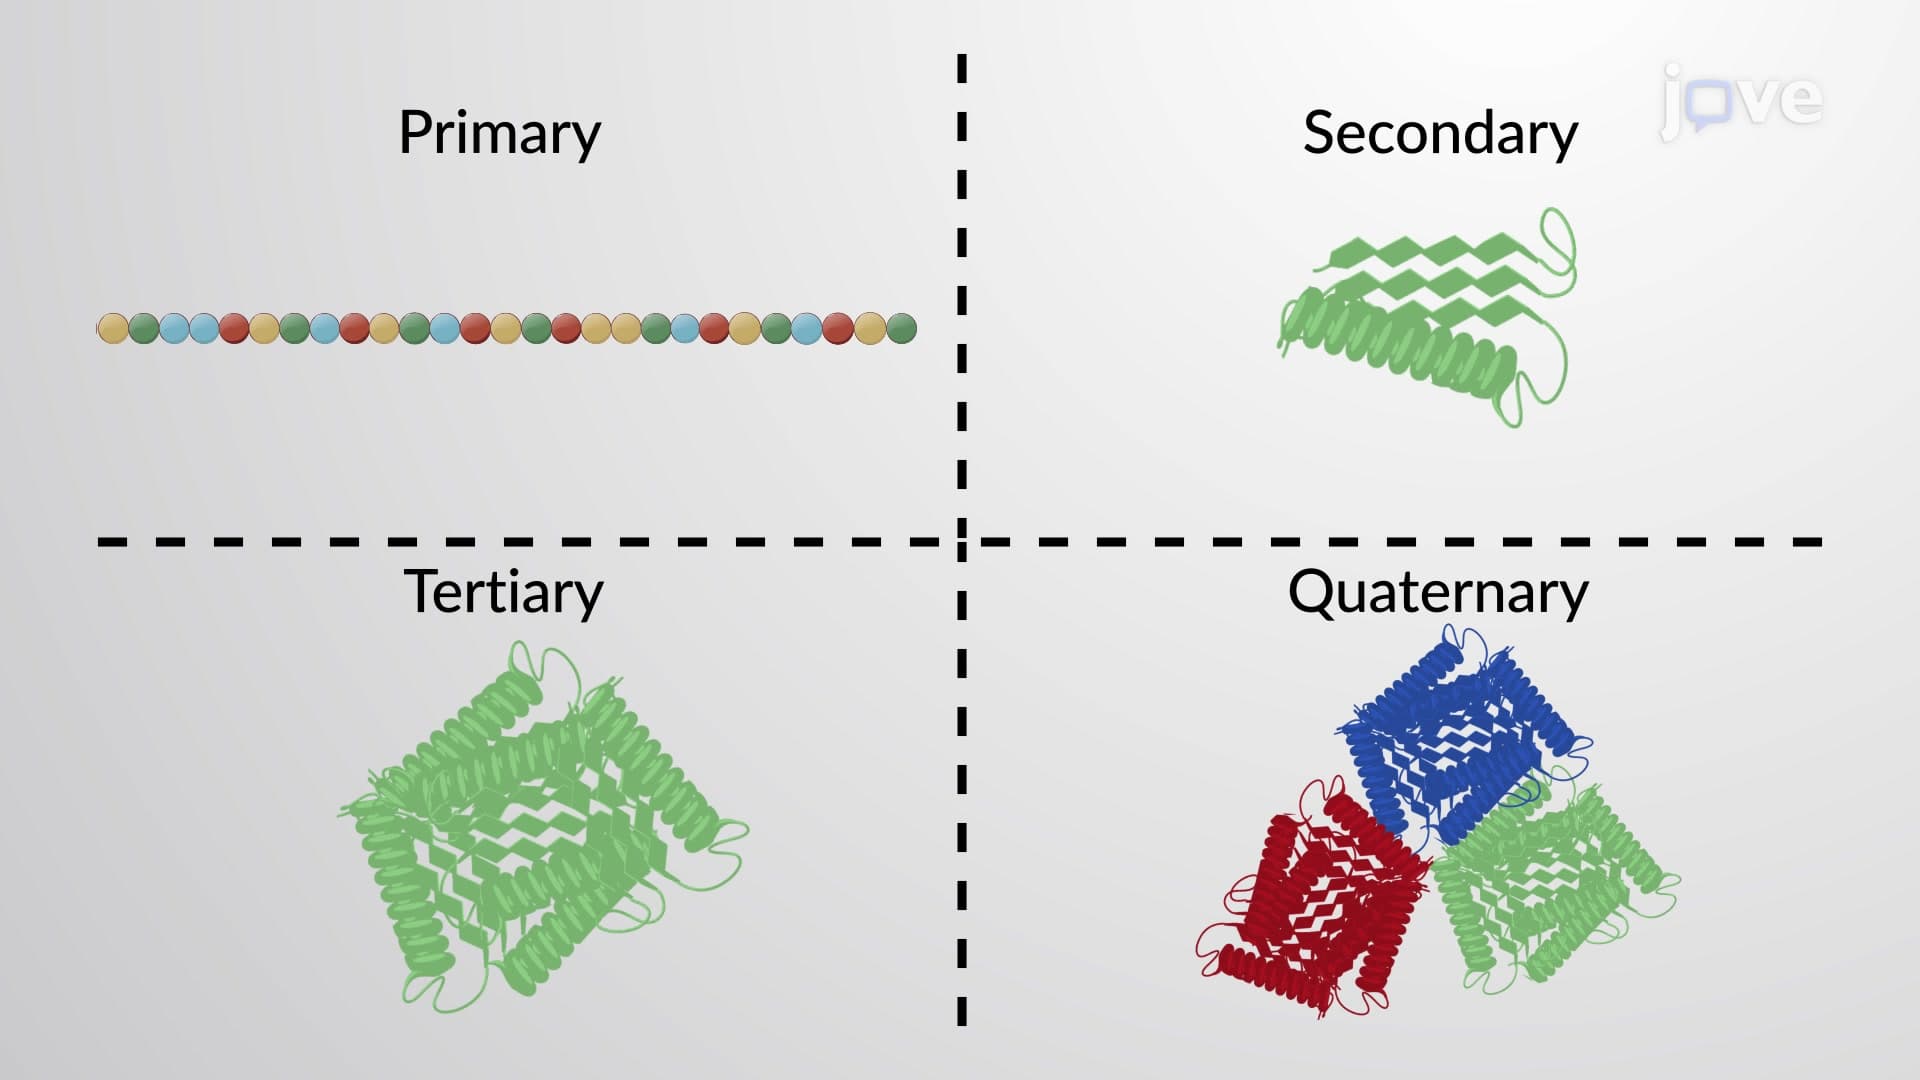
A protein's shape is critical to its function. For example, an enzyme can...
 02:24
Ribosome Profiling
Applications of ribosome profiling
Ribosome profiling has many applications, including in vivo monitoring of translation inside a particular organ or tissue type and quantifying new protein synthesis levels.
The technique helps...