An efficient parallel-processing method for transposing large matrices in place
Related Experiment Video
Updated: Jul 7, 2026
2D and 3D Matrices to Study Linear Invadosome Formation and Activity
Published on: June 2, 2017
1Lawrence Livermore Nat. Lab., CA 94550, USA.

Abstract:
We have developed an efficient algorithm for transposing large matrices in place. The algorithm is efficient because data are accessed either sequentially in blocks or randomly within blocks small enough to fit in cache, and because the same indexing calculations are shared among identical procedures operating on independent subsets of the data. This inherent parallelism makes the method well suited for a multiprocessor computing environment. The algorithm is easy to implement because the same two procedures are applied to the data in various groupings to carry out the complete transpose operation. Using only a single processor, we have demonstrated nearly an order of magnitude increase in speed over the previously published algorithm by Gate and Twigg for transposing a large rectangular matrix in place. With multiple processors operating in parallel, the processing speed increases almost linearly with the number of processors. A simplified version of the algorithm for square matrices is presented as well as an extension for matrices large enough to require virtual memory.
Related Concept Videos
 01:20
Parallel Processing
 01:24
Fast Decoupled and DC Powerflow
 01:12
Parallel-Axis Theorem for an Area
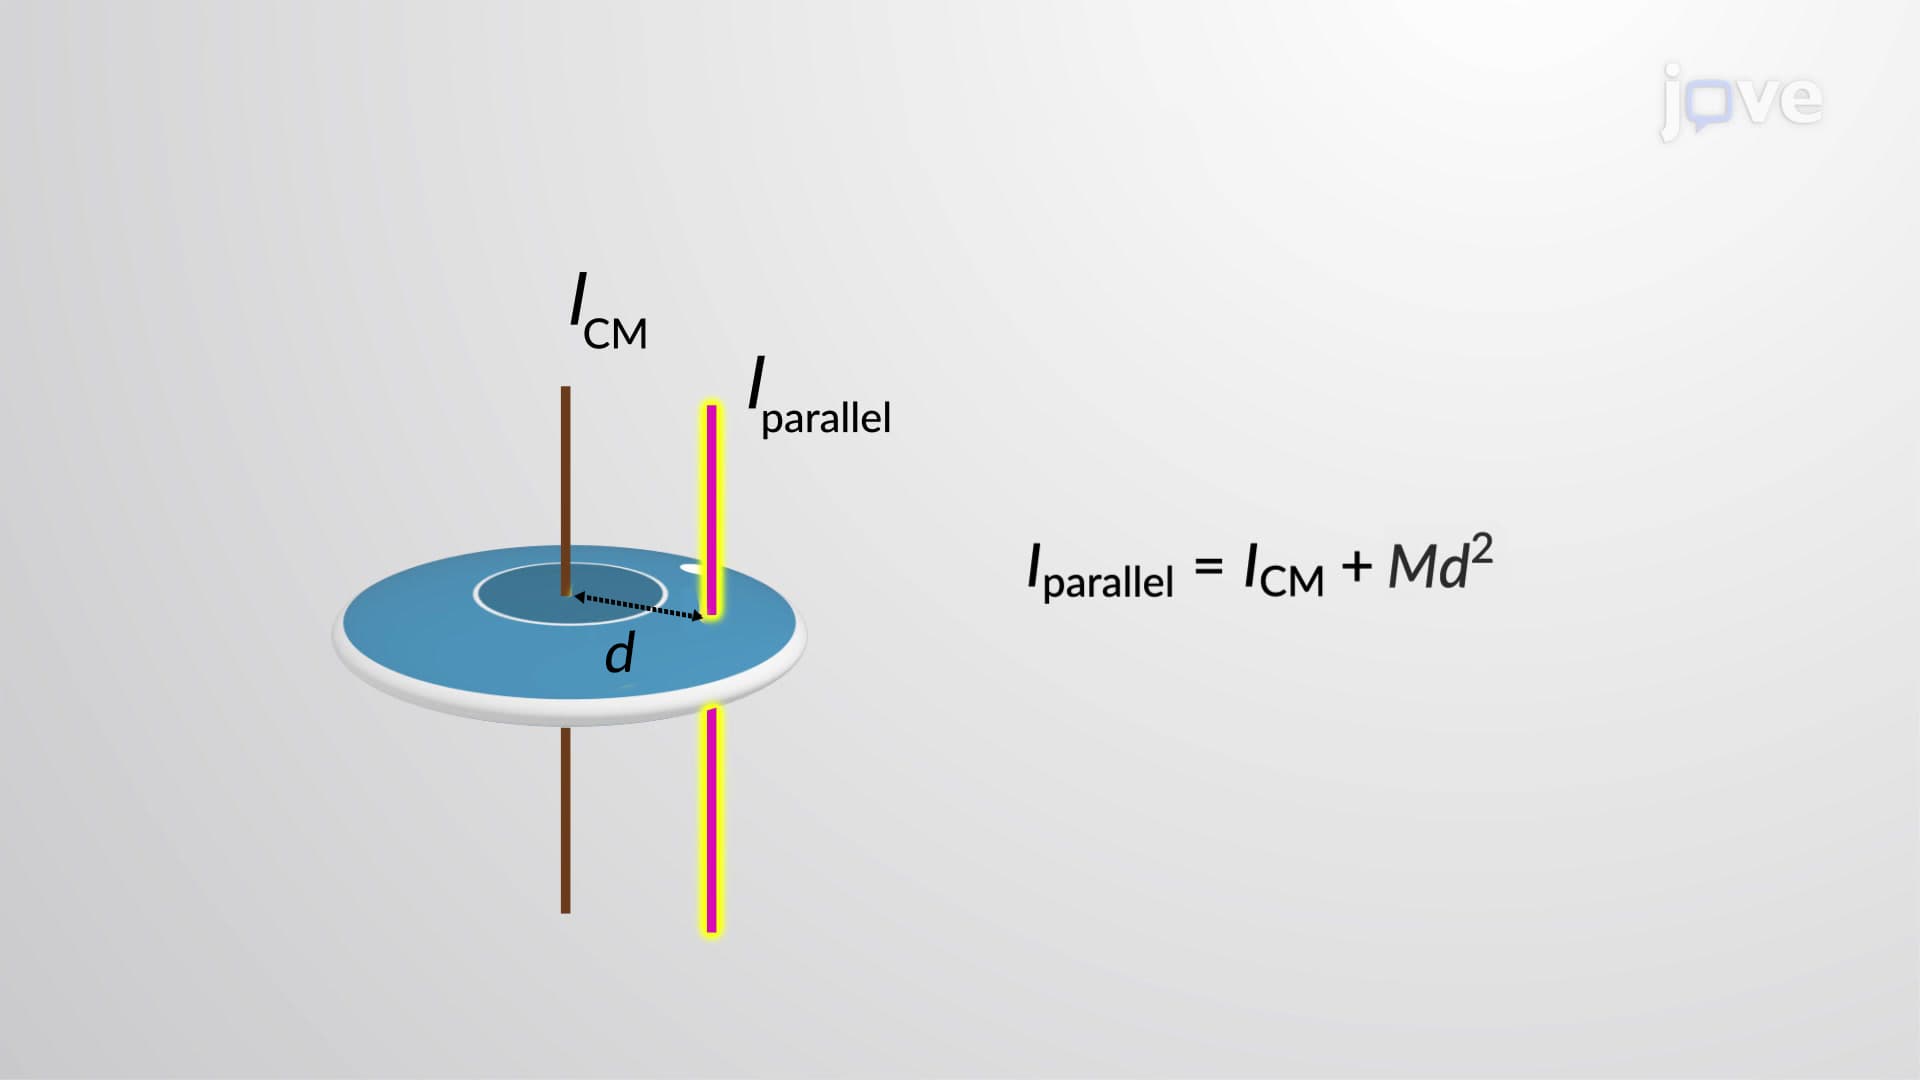
For a flywheel approximated as a solid disc, consider an infinitesimal differential element with an arbitrary distance...
 01:06
Parallel-axis Theorem
 01:24
Overview of Cell-Matrix Interactions
 01:10
Column Efficiency: Plate Theory
A higher number of theoretical plates signifies better column efficiency and improved separation capabilities. Plate height affects bandwidth and separation quality; it is inversely...