Related Experiment Video
Updated: Jul 5, 2026


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Genetic association studies for gene expressions: permutation-based mutual information in a comparison with standard
Silke Szymczak1, Angelo Nuzzo2, Christian Fuchsberger3
1Institute of Medical Biometry and Statistics, University Hospital Schleswig-Holstein, Campus Lübeck, University at Lübeck, Ratzeburger Allee 160, 23538 Lübeck, Germany.

Abstract:
Mutual information (MI) is a robust nonparametric statistical approach for identifying associations between genotypes and gene expression levels. Using the data of Problem 1 provided for the Genetic Analysis Workshop 15, we first compared a quantitative MI (Tsalenko et al. 2006 J Bioinform Comput Biol 4:259-4) with the standard analysis of variance (ANOVA) and the nonparametric Kruskal-Wallis (KW) test. We then proposed a novel feature selection approach using MI in a classification scenario to address the small n - large p problem and compared it with a feature selection that relies on an asymptotic chi2 distribution. In both applications, we used a permutation-based approach for evaluating the significance of MI. Substantial discrepancies in significance were observed between MI, ANOVA, and KW that can be explained by different empirical distributions of the data. In contrast to ANOVA and KW, MI detects shifts in location when the data are non-normally distributed, skewed, or contaminated with outliers. ANOVA but not MI is often significant if one genotype with a small frequency had a remarkable difference in the average gene expression level relative to the other two genotypes. MI depends on genotype frequencies and cannot detect these differences. In the classification scenario, we show that our novel approach for feature selection identifies a smaller list of markers with higher accuracy compared to the standard method. In conclusion, permutation-based MI approaches provide reliable and flexible statistical frameworks which seem to be well suited for data that are non-normal, skewed, or have an otherwise peculiar distribution. They merit further methodological investigation.
Related Concept Videos
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:12
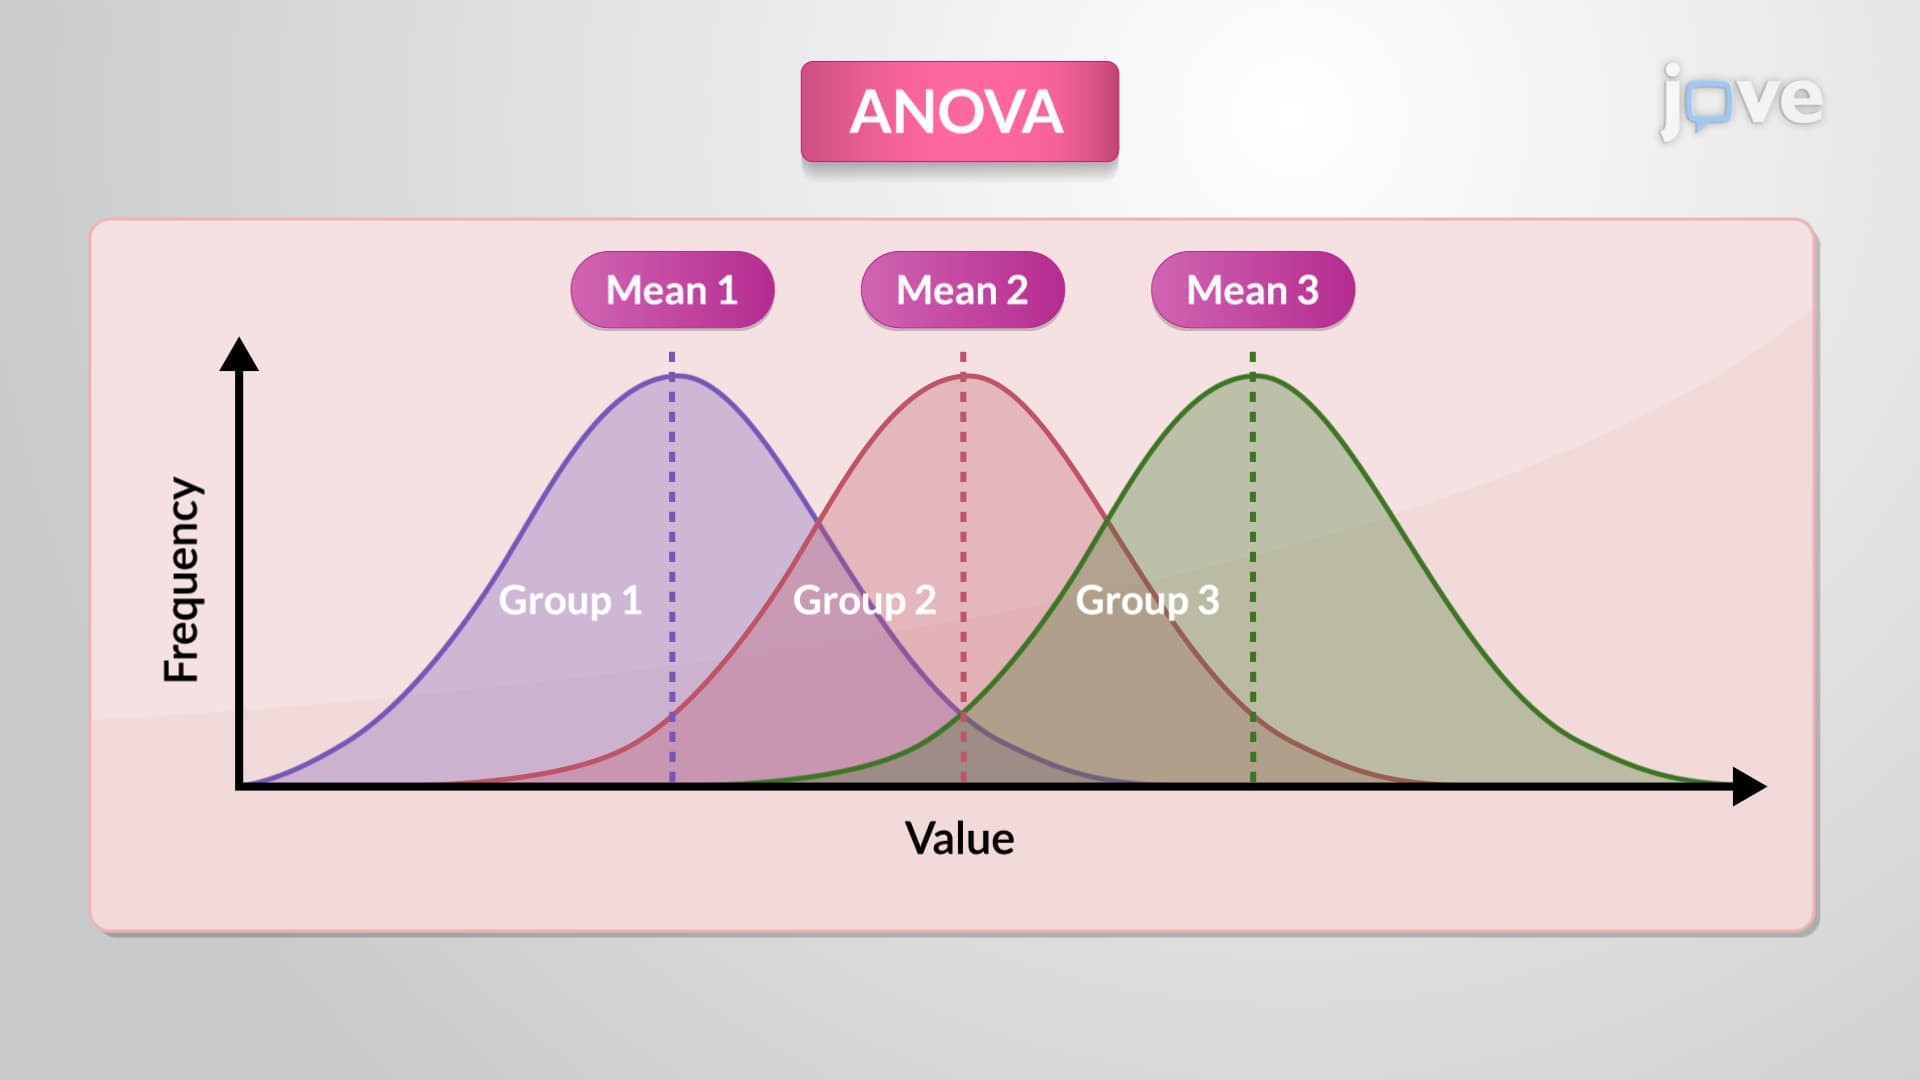
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares the...
 01:18
One-Way ANOVA
 01:16
What is an ANOVA?
Before performing ANOVA, one must ensure that the samples used for this analysis have three crucial characteristics or statistical assumptions. The first assumption states that the samples should be drawn from normally distributed samples, while the second requires that all the drawn samples should be randomly and...
 01:13
What is ANOVA?
Before performing ANOVA, one must ensure that the samples used for this analysis have three crucial characteristics or statistical assumptions. The first assumption states that the samples should be drawn from normally distributed samples, while the second requires that all the drawn samples be randomly and independently...
 02:26
Comparing Copy Number Variations and SNPs
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...