Related Experiment Video
Updated: Jul 2, 2026

Quantifying Spatiotemporal Parameters of Cellular Exocytosis in Micropatterned Cells
Published on: September 16, 2020
Splitting the tail of the displacement kernel shows the unimportance of kurtosis
Tom Lindström1, Nina Håkansson, Lars Westerberg
1IFM, Theory and Modelling, Linköpings Universitet, Linköpings, Sweden.

Abstract:
Animals disperse in space through different movement behaviors, resulting in different displacement distances. This is often described with a displacement kernel where the long-distance dispersers are within the tail of the kernel. A displacement with a large proportion of long-distance dispersers may have impact on different aspects of spatial ecology such as invasion speed, population persistence, and distribution. It is, however, unclear whether the kurtosis of the kernel plays a major role since a fatter tail also influences the variance of the kernel. We modeled displacement in landscapes with different amounts and configurations of habitats and handled kurtosis and variance separately to study how these affected population distribution and transition time. We conclude that kurtosis is not important for any of these aspects of spatial ecology. The variance of the kernel, on the other hand, was of great importance to both population distribution and transition time. We argue that separating variance and kurtosis can cast new light on the way in which long-distance dispersers are important in ecological processes. Consequences for empirical studies are discussed.
Related Concept Videos
 01:24
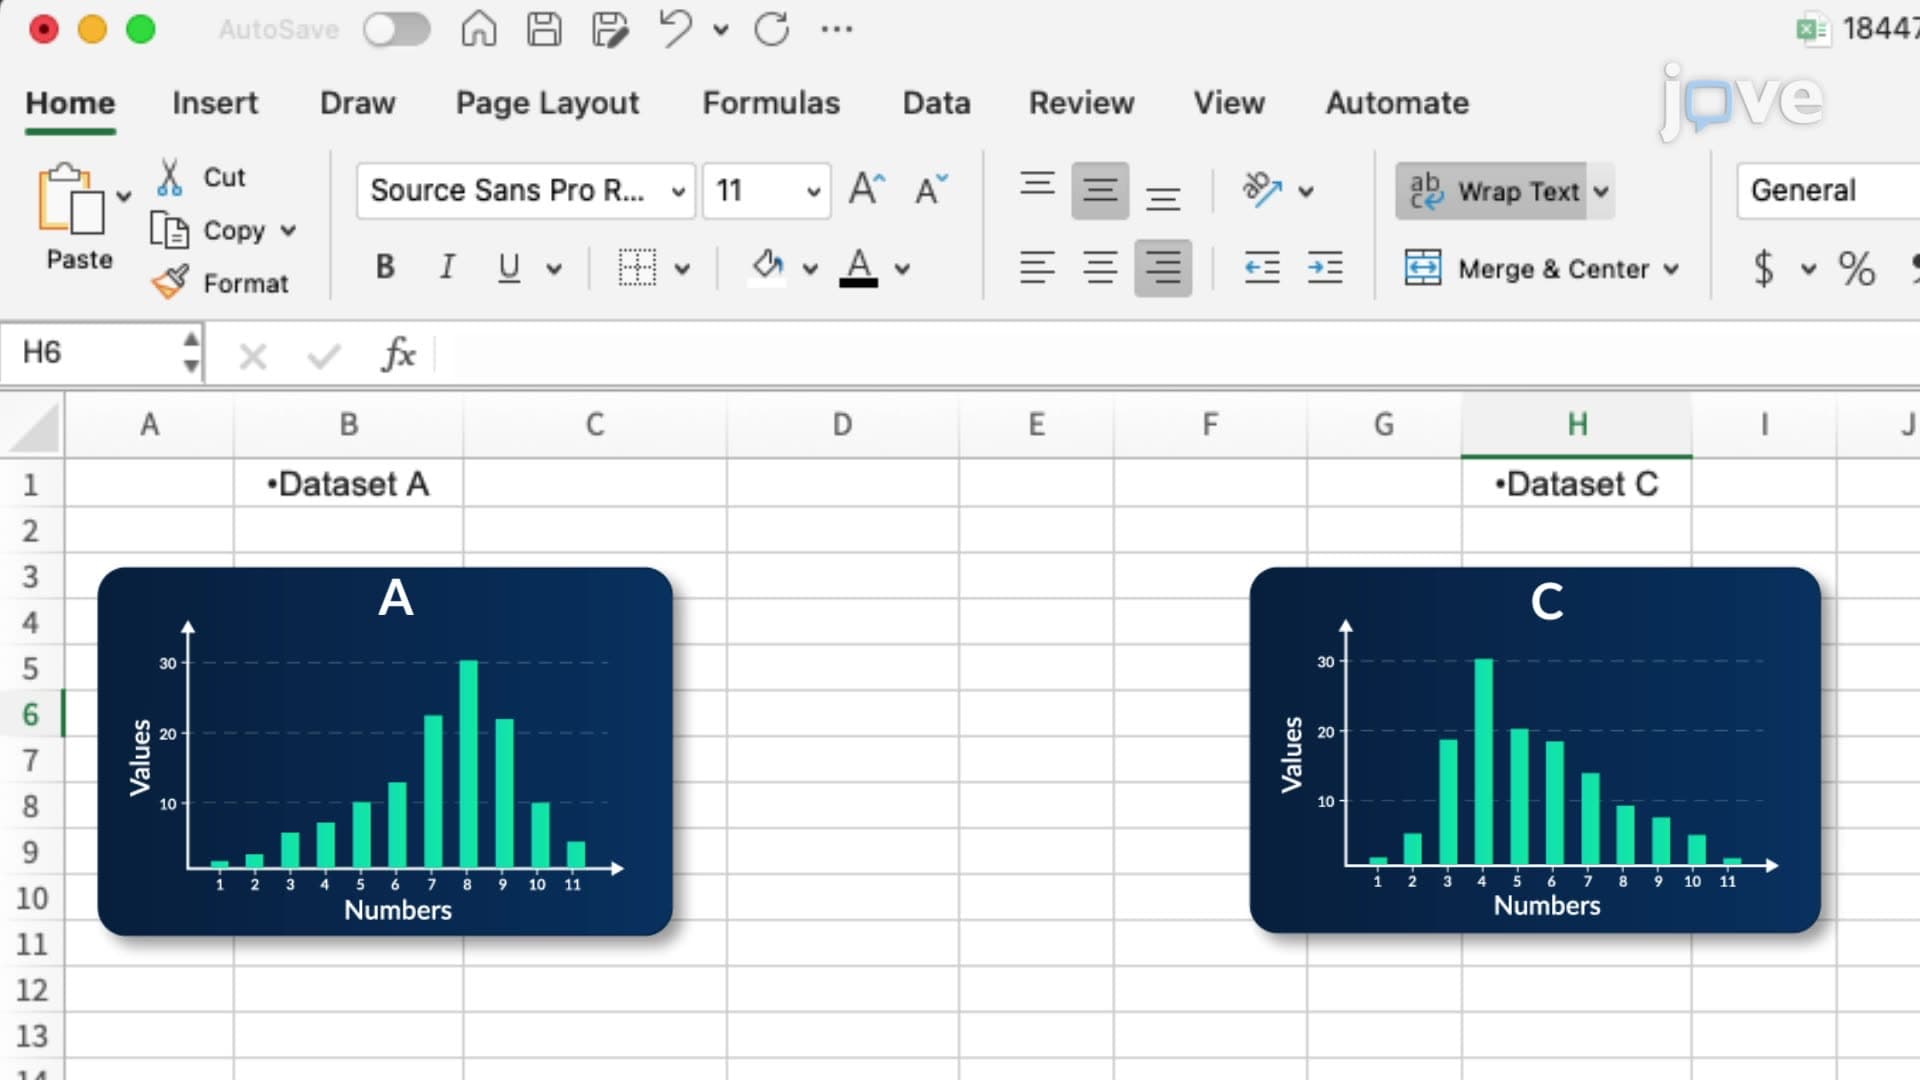
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
 00:57
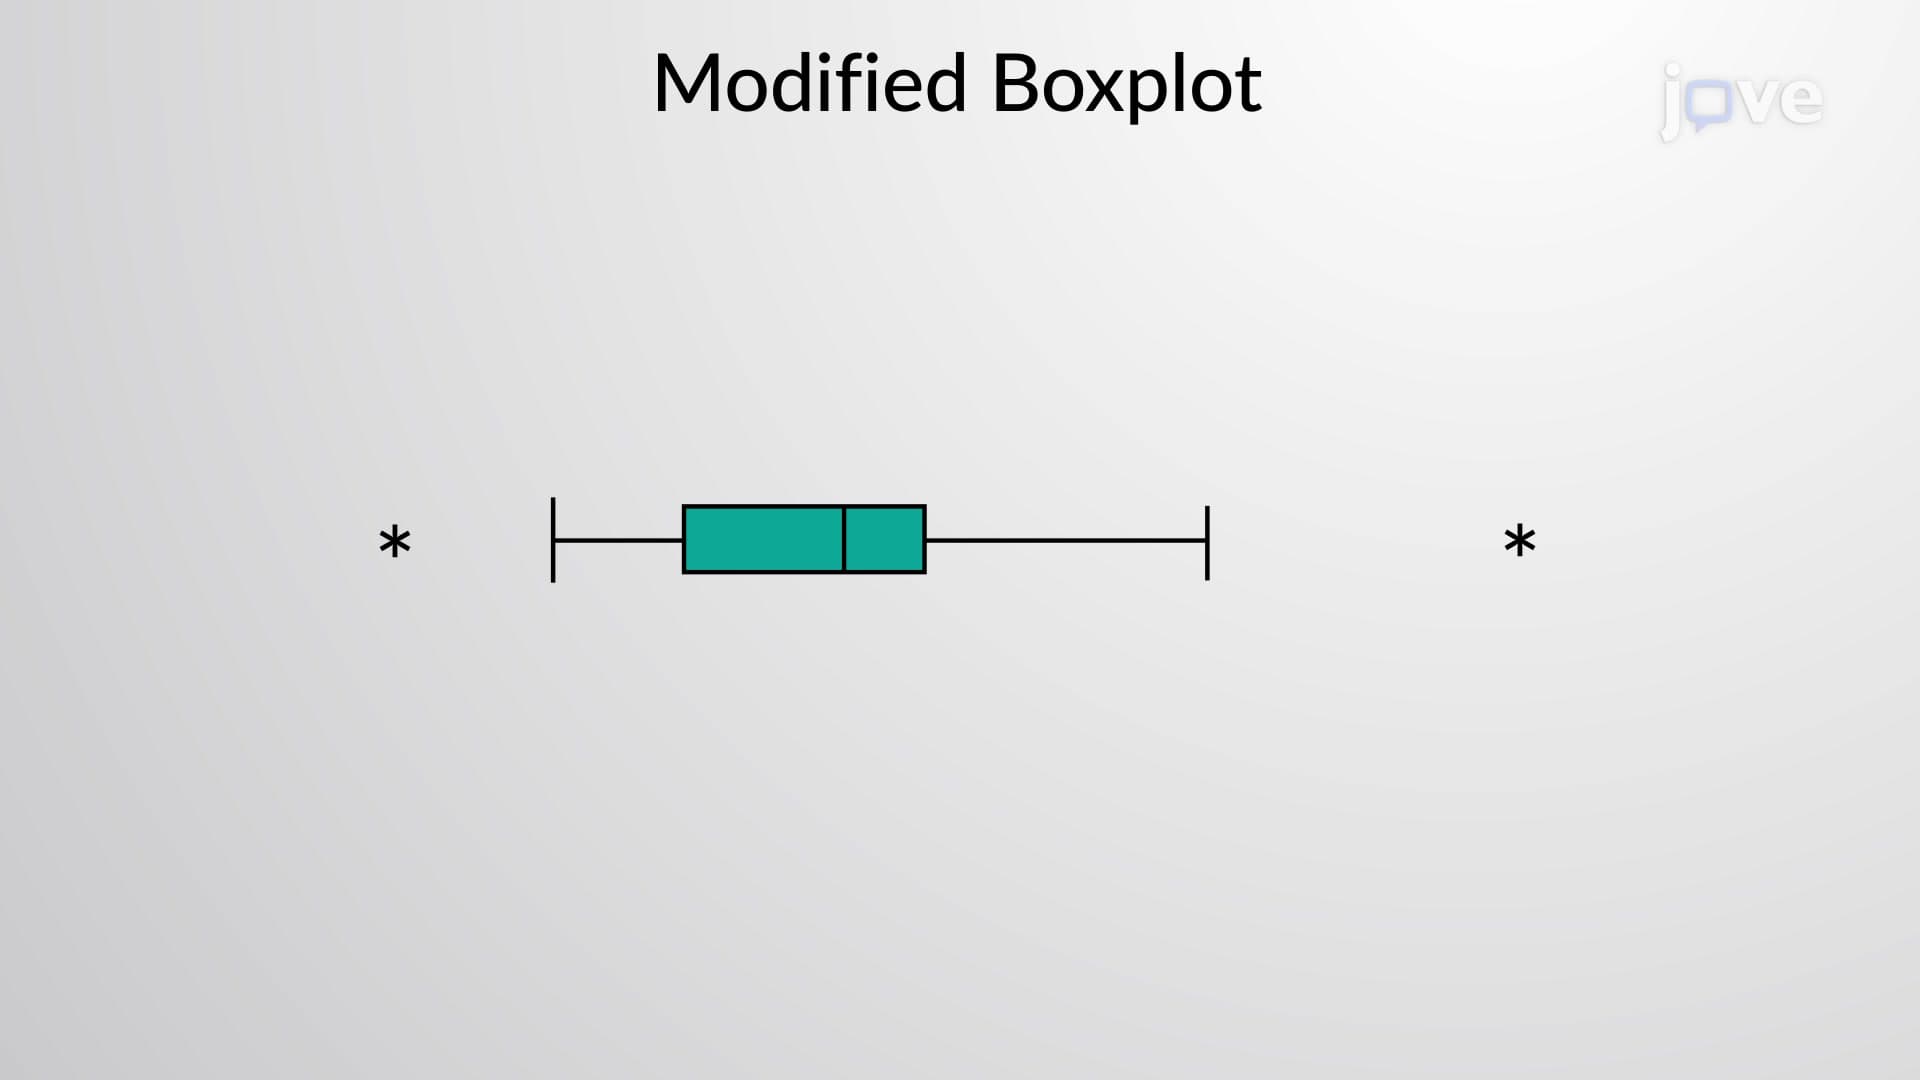
Modified Boxplots
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
 01:06
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency are...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:15
Chebyshev's Theorem to Interpret Standard Deviation
 01:08
Outliers and Influential Points