Probability fold change: a robust computational approach for identifying differentially expressed gene lists
Related Experiment Video
Updated: Jun 29, 2026
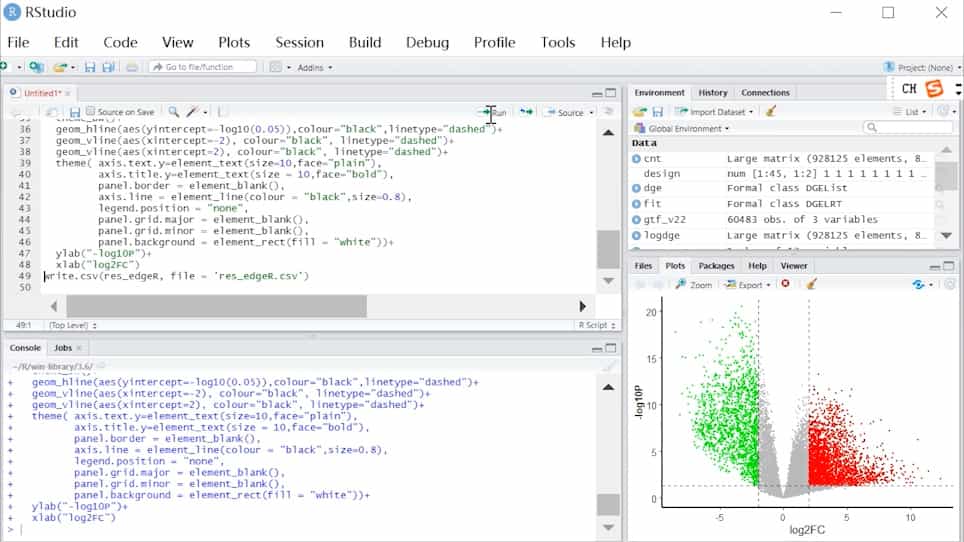
Three Differential Expression Analysis Methods for RNA Sequencing: limma, EdgeR, DESeq2
Published on: September 18, 2021
Xutao Deng1, Jun Xu, James Hui
1Transcriptional Genomics Core, Cedars-Sinai Medical Center, David Geffen School of Medicine at UCLA, Los Angeles, CA 90048, USA. dengx@ucla.edu

Abstract:
Identifying genes that are differentially expressed under different experimental conditions is a fundamental task in microarray studies. However, different ranking methods generate very different gene lists, and this could profoundly impact follow-up analyses and biological interpretation. Therefore, developing improved ranking methods are critical in microarray data analysis. We developed a new algorithm, the probabilistic fold change (PFC), which ranks genes based on a confidence interval estimate of fold change. We performed extensive testing using multiple benchmark data sources including the MicroArray Quality Control (MAQC) data sets. We corroborated our observations with MAQC data sets using qRT-PCR data sets and Latin square spike-in data sets. Along with PFC, we tested six other popular ranking algorithms including Mean Fold Change (FC), SAM, t-statistic (T), Bayesian-t (BAYT), Intensity-Conditional Fold Change (CFC), and Rank Product (RP). PFC achieved reproducibility and accuracy that are consistently among the best of the seven ranking algorithms while other ranking algorithms would show weakness in some cases. Contrary to common belief, our results demonstrated that statistical accuracy will not translate to biological reproducibility and therefore both quality aspects need to be evaluated.