Related Experiment Video
Updated: Jun 27, 2026

An Allele-specific Gene Expression Assay to Test the Functional Basis of Genetic Associations
Published on: November 3, 2010
Variance component estimation for mixed model analysis of cDNA microarray data
Barbara Sarholz1, Hans-Peter Piepho
1General Motors Powertrain Germany GmbH, Rüsselsheim, Germany.

Abstract:
Microarrays provide a valuable tool for the quantification of gene expression. Usually, however, there is a limited number of replicates leading to unsatisfying variance estimates in a gene-wise mixed model analysis. As thousands of genes are available, it is desirable to combine information across genes. When more than two tissue types or treatments are to be compared it might be advisable to consider the array effect as random. Then information between arrays may be recovered, which can increase accuracy in estimation. We propose a method of variance component estimation across genes for a linear mixed model with two random effects. The method may be extended to models with more than two random effects. We assume that the variance components follow a log-normal distribution. Assuming that the sums of squares from the gene-wise analysis, given the true variance components, follow a scaled chi(2)-distribution, we adopt an empirical Bayes approach. The variance components are estimated by the expectation of their posterior distribution. The new method is evaluated in a simulation study. Differentially expressed genes are more likely to be detected by tests based on these variance estimates than by tests based on gene-wise variance estimates. This effect is most visible in studies with small array numbers. Analyzing a real data set on maize endosperm the method is shown to work well.
More Related Videos
Related Concept Videos
 01:11
Variability: Analysis
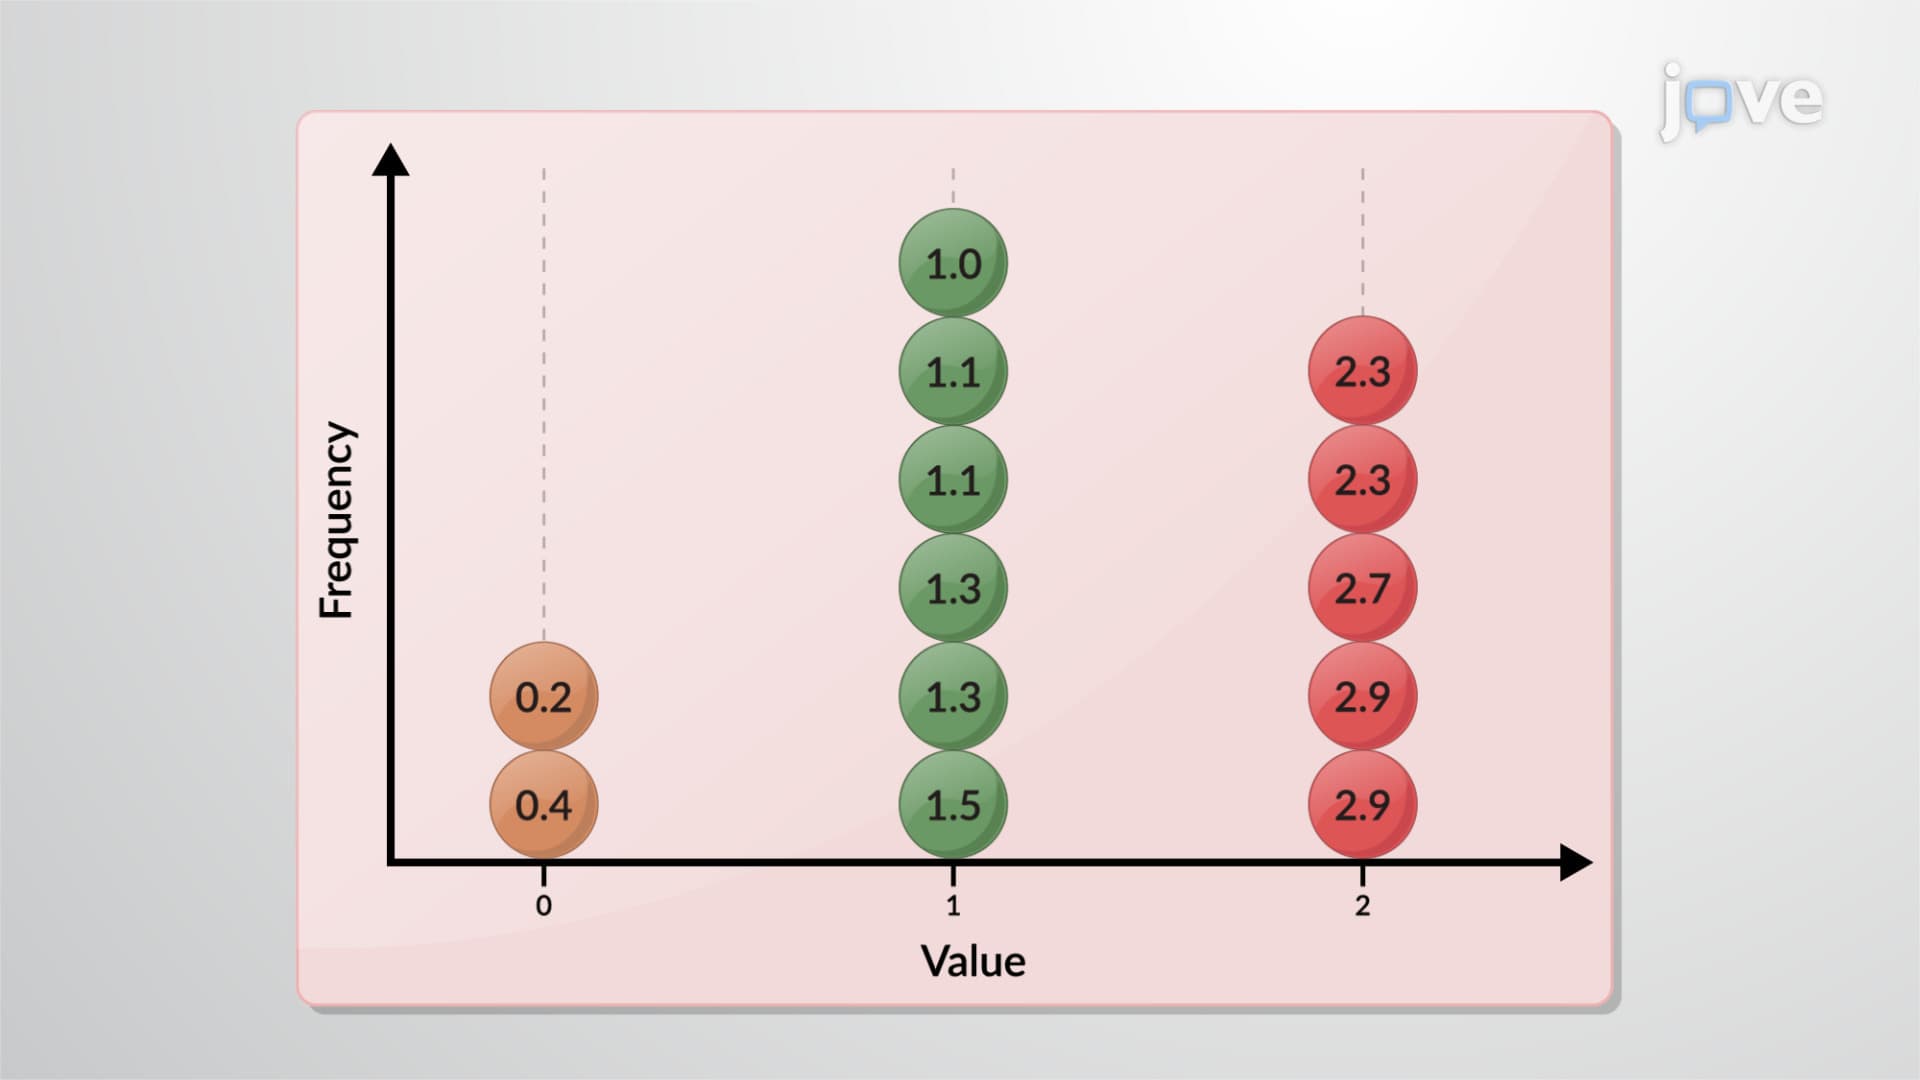
The range is a simple measure of variability, indicating the difference between the highest and...
 01:15
Variance
 01:15
One-Way ANOVA: Equal Sample Sizes
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 02:34
DNA Microarrays
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...