Related Experiment Video
Updated: Jun 26, 2026

Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
Variance components linkage analysis with repeated measurements
Liming Liang1, Wei-Min Chen, Pak C Sham
1Department of Biostatistics, University of Michigan, Ann Arbor, Mich., USA. lianglim@umich.edu

Background:
When subjects are measured multiple times, linkage analysis needs to appropriately model these repeated measures. A number of methods have been proposed to model repeated measures in linkage analysis. Here, we focus on assessing the impact of repeated measures on the power and cost of a linkage study.
Methods:
We describe three alternative extensions of the variance components approach to accommodate repeated measures in a quantitative trait linkage study. We explicitly relate power and cost through the number of measures for different designs. Based on these models, we derive general formulas for optimal number of repeated measures for a given power or cost and use analytical calculations and simulations to compare power for different numbers of repeated measures across several scenarios. We give rigorous proof for the results under the balanced design.
Results:
Repeated measures substantially improve power and the proportional increase in LOD score depends mostly on measurement error and total heritability but not much on marker map, the number of alleles per marker or family structure. When measurement error takes up 20% of the trait variability and 4 measures/subject are taken, the proportional increase in LOD score ranges from 38% for traits with heritability of approximately 20% to 63% for traits with heritability of approximately 80%. An R package is provided to determine optimal number of repeated measures for given measurement error and cost. Variance component and regression based implementations of our methods are included in the MERLIN package to facilitate their use in practical studies.

Related Concept Videos
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:14
What is Variation?
The range, standard deviation, standard error, and variance are the different measures of variation.
Range: The range is the difference between its maximum and...
 01:19
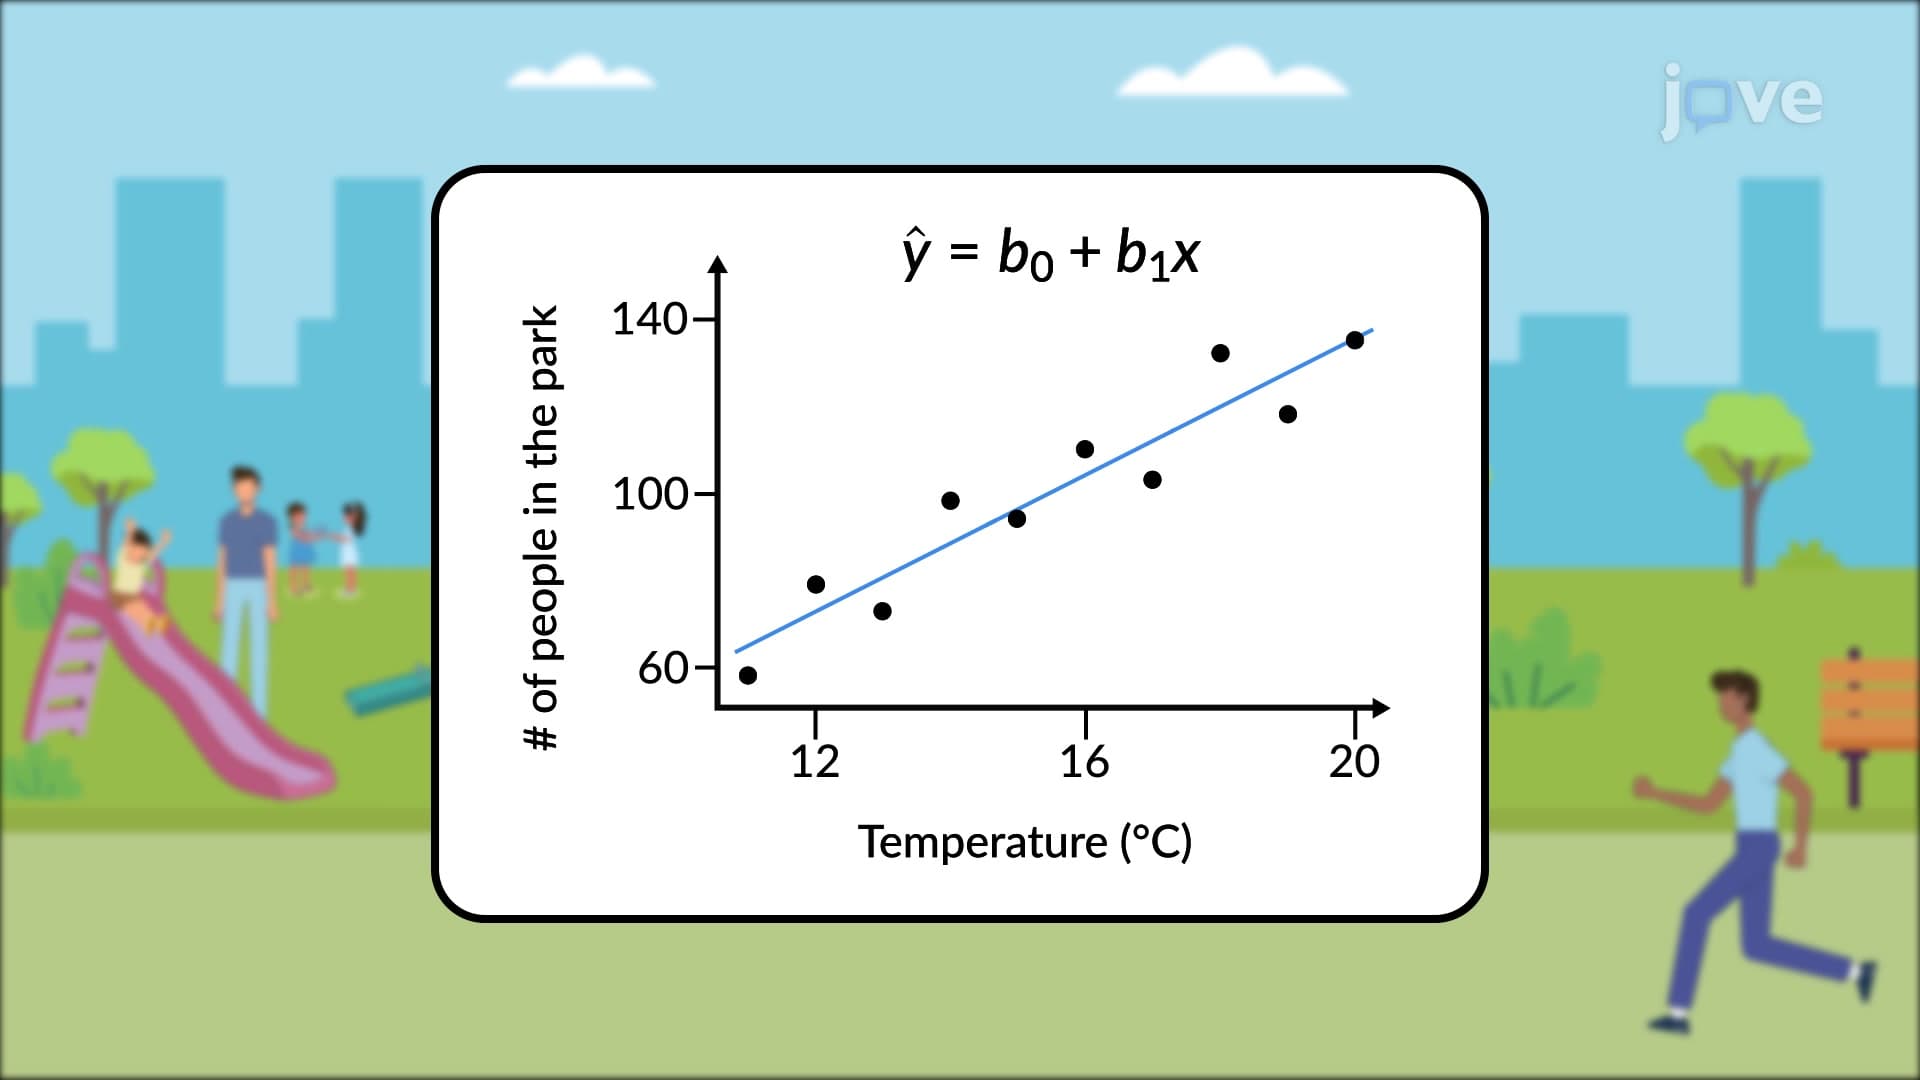
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:18
One-Way ANOVA
 01:15
Variance