Related Experiment Video
Updated: Jun 25, 2026


A Protocol for Computer-Based Protein Structure and Function Prediction
Published on: November 3, 2011
Multiple classifier integration for the prediction of protein structural classes
Lei Chen1, Lin Lu, Kairui Feng
1Shanghai Key Laboratory of Trustworthy Computing, East China Normal University, Shanghai 200062, People's Republic of China.

Abstract:
Supervised classifiers, such as artificial neural network, partition trees, and support vector machines, are often used for the prediction and analysis of biological data. However, choosing an appropriate classifier is not straightforward because each classifier has its own strengths and weaknesses, and each biological dataset has its own characteristics. By integrating many classifiers together, people can avoid the dilemma of choosing an individual classifier out of many to achieve an optimized classification results (Rahman et al., Multiple Classifier Combination for Character Recognition: Revisiting the Majority Voting System and Its Variation, Springer, Berlin, 2002, 167-178). The classification algorithms come from Weka (Witten and Frank, Data Mining: Practical Machine Learning Tools and Techniques, Morgan Kaufmann, San Francisco, 2005) (a collection of software tools for machine learning algorithms). By integrating many predictors (classifiers) together through simple voting, the correct prediction (classification) rates are 65.21% and 65.63% for a basic training dataset and an independent test set, respectively. These results are better than any single machine learning algorithm collected in Weka when exactly the same data are used. Furthermore, we introduce an integration strategy which takes care of both classifier weightings and classifier redundancy. A feature selection strategy, called minimum redundancy maximum relevance (mRMR), is transferred into algorithm selection to deal with classifier redundancy in this research, and the weightings are based on the performance of each classifier. The best classification results are obtained when 11 algorithms are selected by mRMR method, and integrated together through majority votes with weightings. As a result, the prediction correct rates are 68.56% and 69.29% for the basic training dataset and the independent test dataset, respectively. The web-server is available at http://chemdata.shu.edu.cn/protein_st/.

Related Concept Videos
 02:15
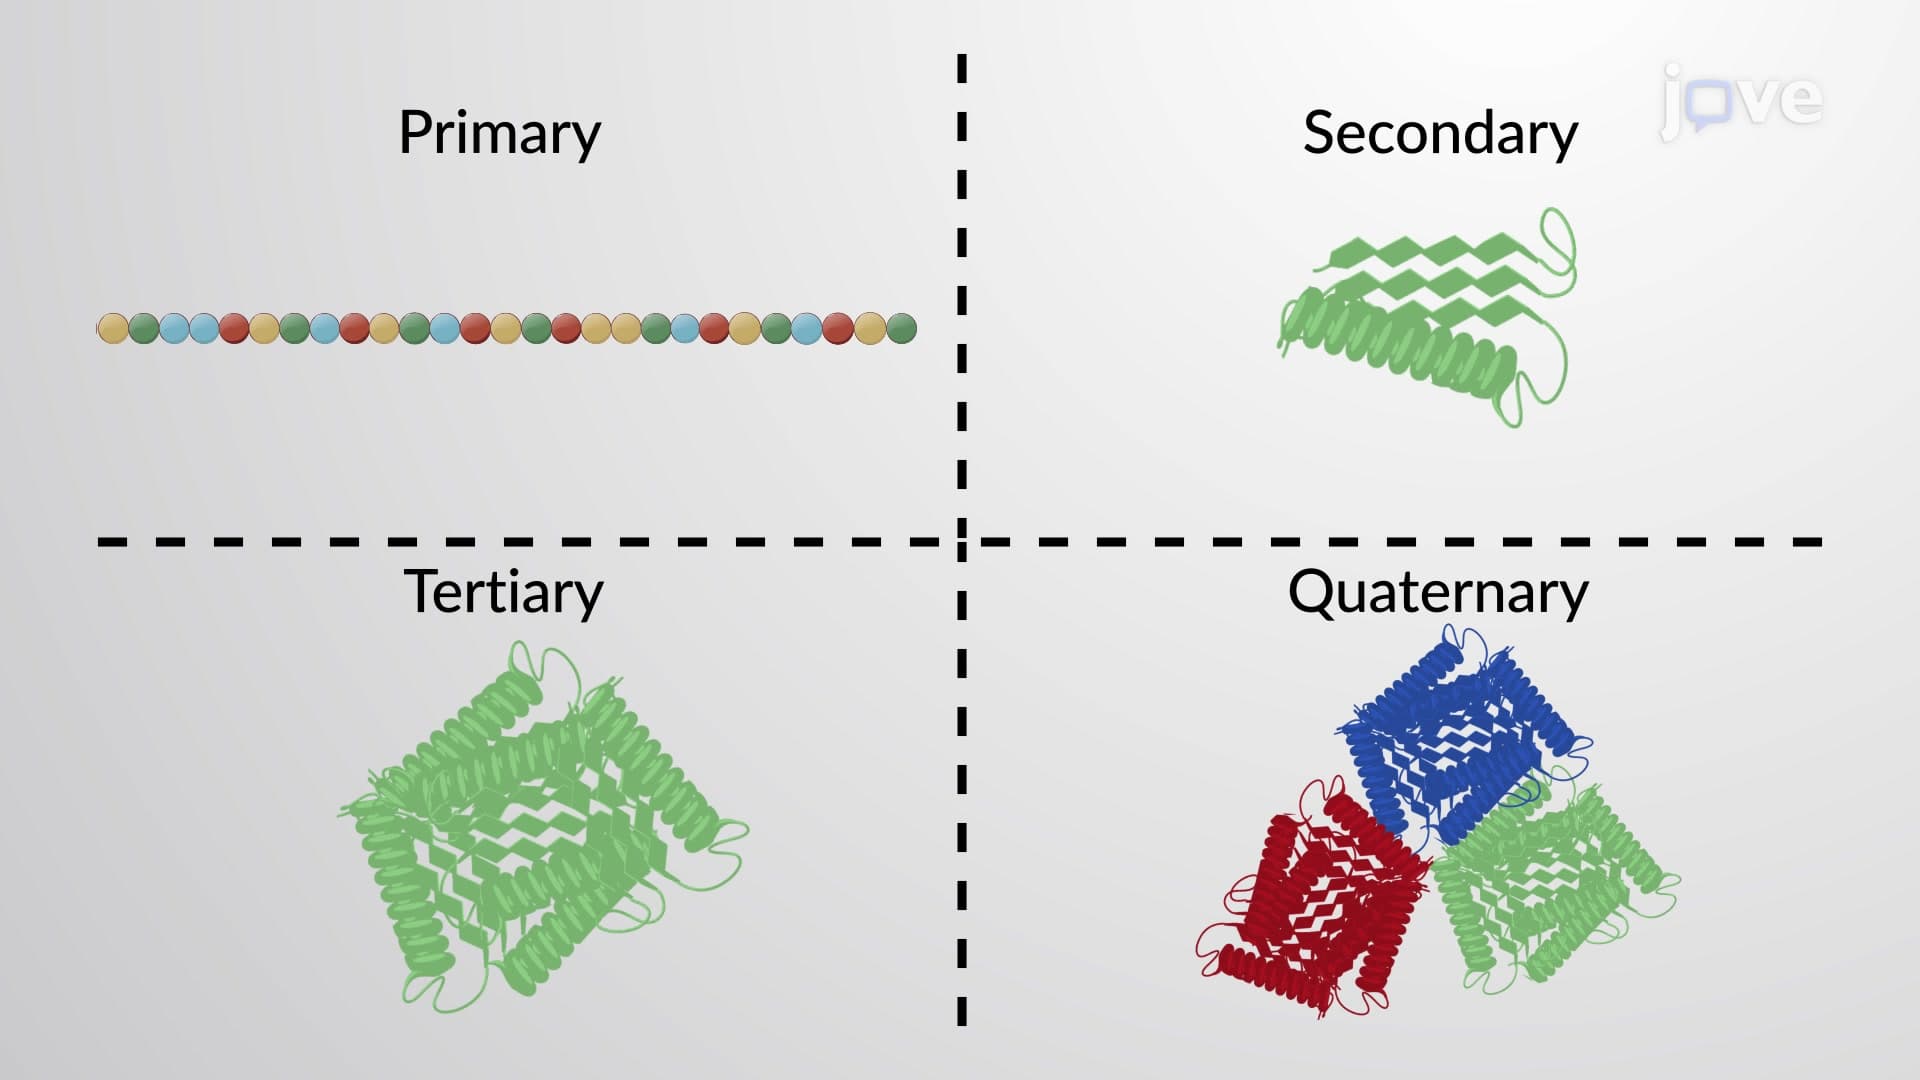
Protein and Protein Structure
A protein's shape is critical to its function. For example, an enzyme can...
 01:25
Antibody Structure and Classes
The basic structure of an antibody consists of four protein chains: two identical heavy chains and two identical light chains. These chains are held together by disulfide bonds and other non-covalent interactions, forming a Y-shaped structure.
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:57
Protein Complexes with Interchangeable Parts
The SCF ubiquitin ligase is a protein complex of five individual proteins. This complex attaches ubiquitin to other target proteins to mark them for degradation. In order to...
01:57Protein Complexes with Interchangeable Parts
The SCF ubiquitin ligase is a protein complex of five individual proteins. This complex attaches ubiquitin to other target proteins to mark them for degradation. In order to...
02:15Protein and Protein Structures
A protein's shape is critical to its function. For example, an enzyme can...