Kernel discriminant analysis for positive definite and indefinite kernels
Related Experiment Videos
Elzbieta Pekalska1, Bernard Haasdonk
1School of Computer Science, University of Manchester, Oxford Road, M13 9PL Manchester, UK. pekalska@cs.man.ac.uk

Abstract:
Kernel methods are a class of well established and successful algorithms for pattern analysis thanks to their mathematical elegance and good performance. Numerous nonlinear extensions of pattern recognition techniques have been proposed so far based on the so-called kernel trick. The objective of this paper is twofold. First, we derive an additional kernel tool that is still missing, namely kernel quadratic discriminant (KQD). We discuss different formulations of KQD based on the regularized kernel Mahalanobis distance in both complete and class-related subspaces. Secondly, we propose suitable extensions of kernel linear and quadratic discriminants to indefinite kernels. We provide classifiers that are applicable to kernels defined by any symmetric similarity measure. This is important in practice because problem-suited proximity measures often violate the requirement of positive definiteness. As in the traditional case, KQD can be advantageous for data with unequal class spreads in the kernel-induced spaces, which cannot be well separated by a linear discriminant. We illustrate this on artificial and real data for both positive definite and indefinite kernels.
Related Concept Videos
 01:29
Quadratic Equations in the Complex Number System
 01:19
Routh-Hurwitz Criterion II
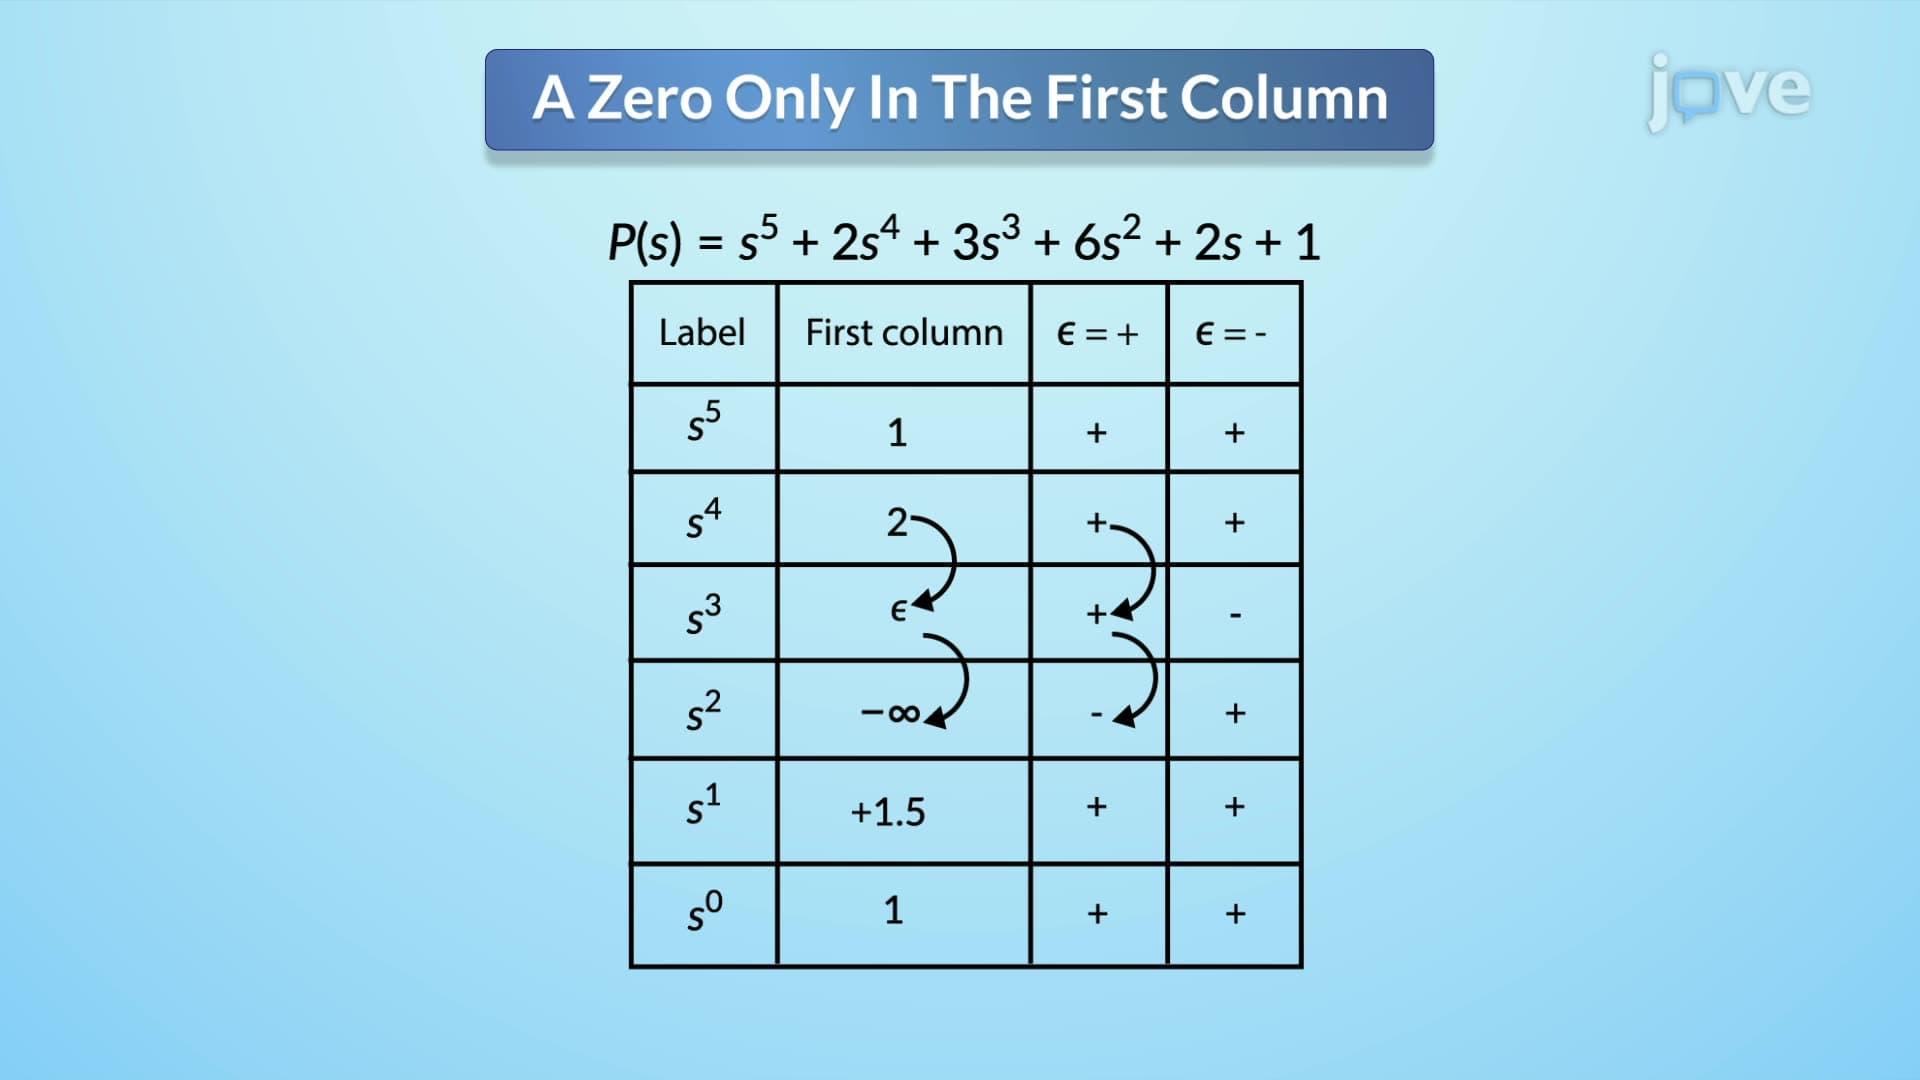
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first column of the Routh...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:15
Routh-Hurwitz Criterion I
To apply the Routh-Hurwitz criterion, a Routh table is constructed. The table's rows are labeled with powers of the complex frequency variable s, starting from the...
 01:29
Application of Nonlinear Inequalities
 01:30
Gaussian Elimination: Problem Solving