Related Experiment Video
Updated: Jun 23, 2026
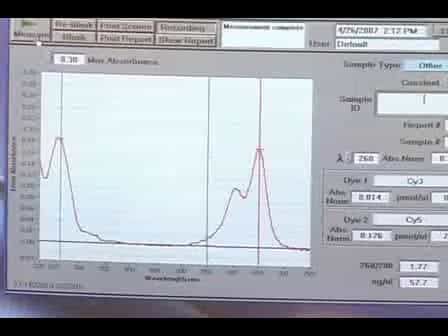

Bacterial Gene Expression Analysis Using Microarrays
Published on: May 28, 2007
Text-based over-representation analysis of microarray gene lists with annotation bias
1Department of Pathology, School of Medicine, Cardiff University, Heath Park, Cardiff CF14 4XN, UK.

Abstract:
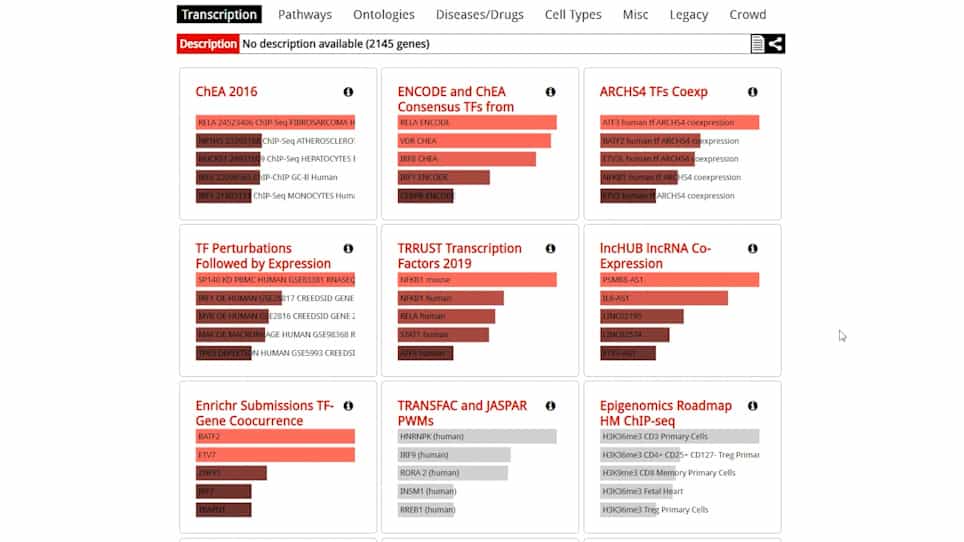
A major challenge in microarray data analysis is the functional interpretation of gene lists. A common approach to address this is over-representation analysis (ORA), which uses the hypergeometric test (or its variants) to evaluate whether a particular functionally defined group of genes is represented more than expected by chance within a gene list. Existing applications of ORA have been largely limited to pre-defined terminologies such as GO and KEGG. We report our explorations of whether ORA can be applied to a wider mining of free-text. We found that a hitherto underappreciated feature of experimentally derived gene lists is that the constituents have substantially more annotation associated with them, as they have been researched upon for a longer period of time. This bias, a result of patterns of research activity within the biomedical community, is a major problem for classical hypergeometric test-based ORA approaches, which cannot account for such bias. We have therefore developed three approaches to overcome this bias, and demonstrate their usability in a wide range of published datasets covering different species. A comparison with existing tools that use GO terms suggests that mining PubMed abstracts can reveal additional biological insight that may not be possible by mining pre-defined ontologies alone.
Related Concept Videos
 02:34
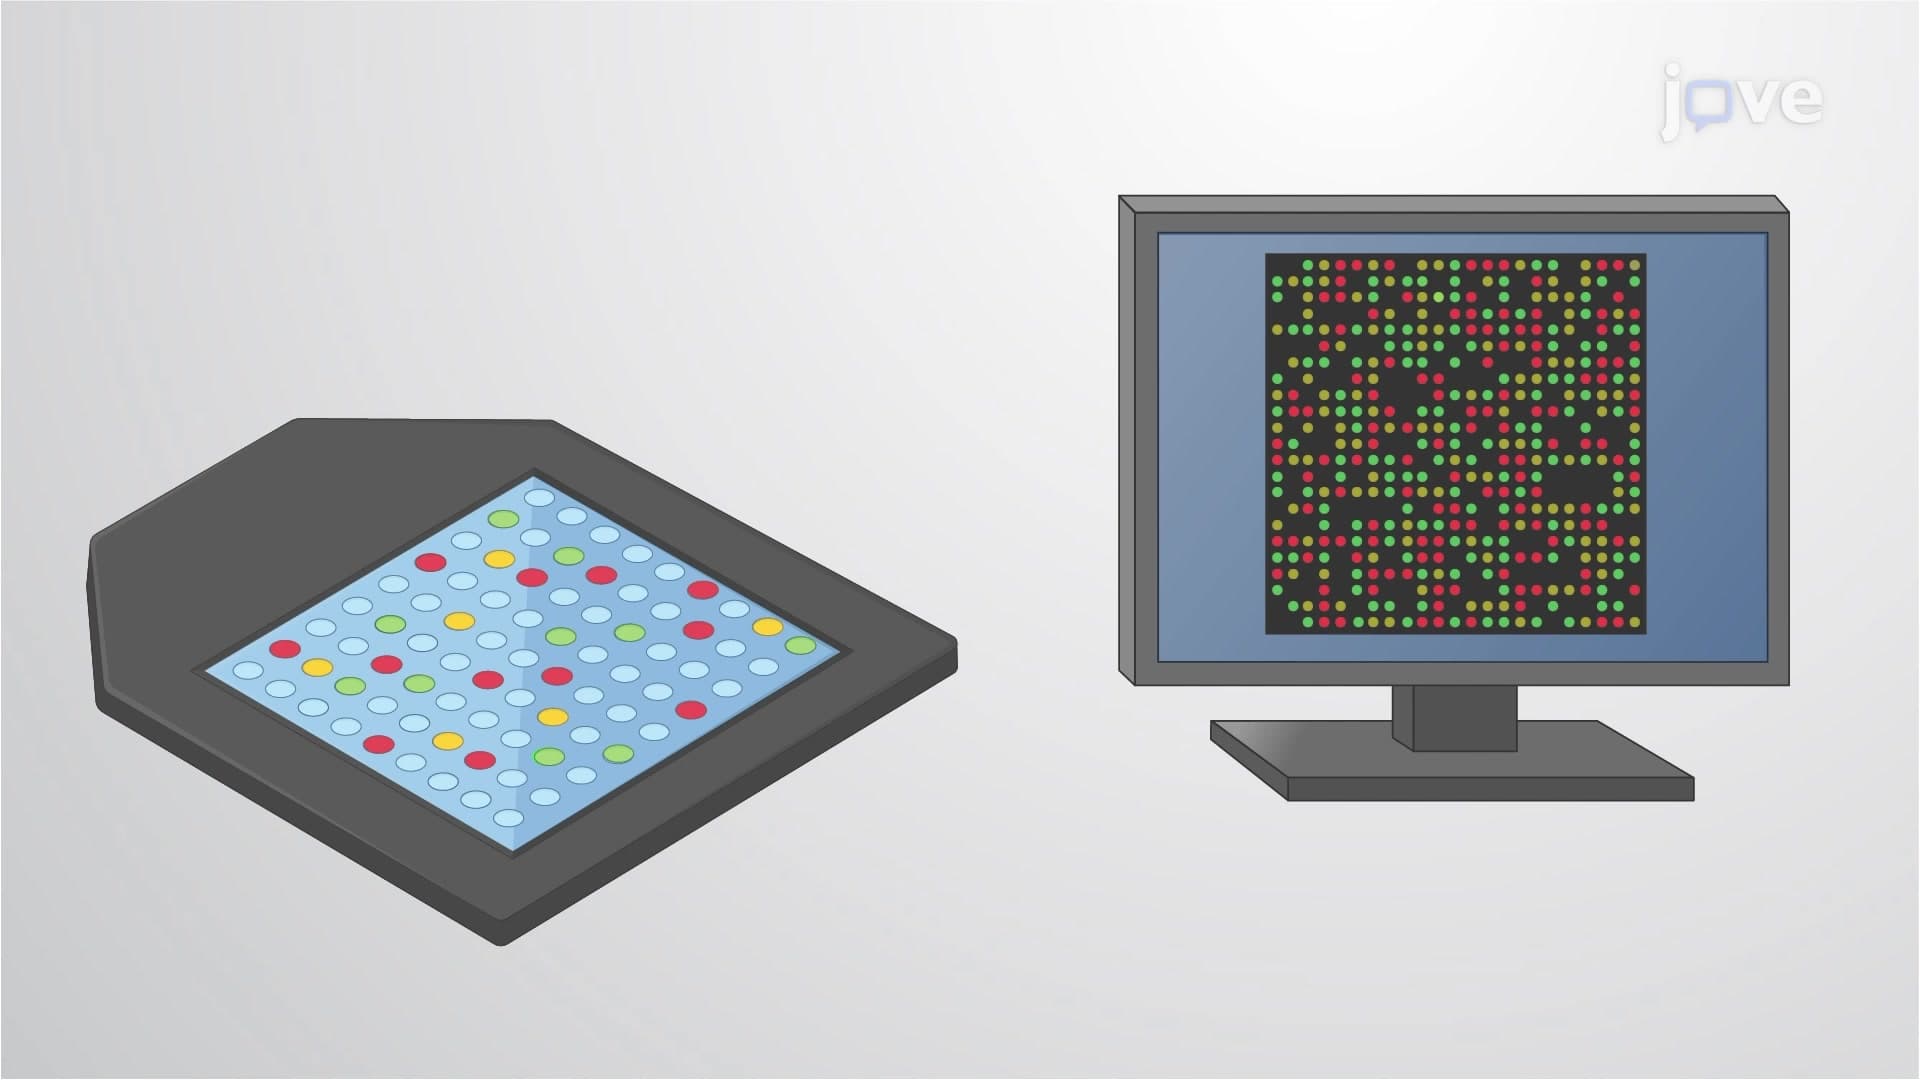
DNA Microarrays
 03:36
Genome Annotation and Assembly