Related Experiment Video
Updated: Jun 20, 2026
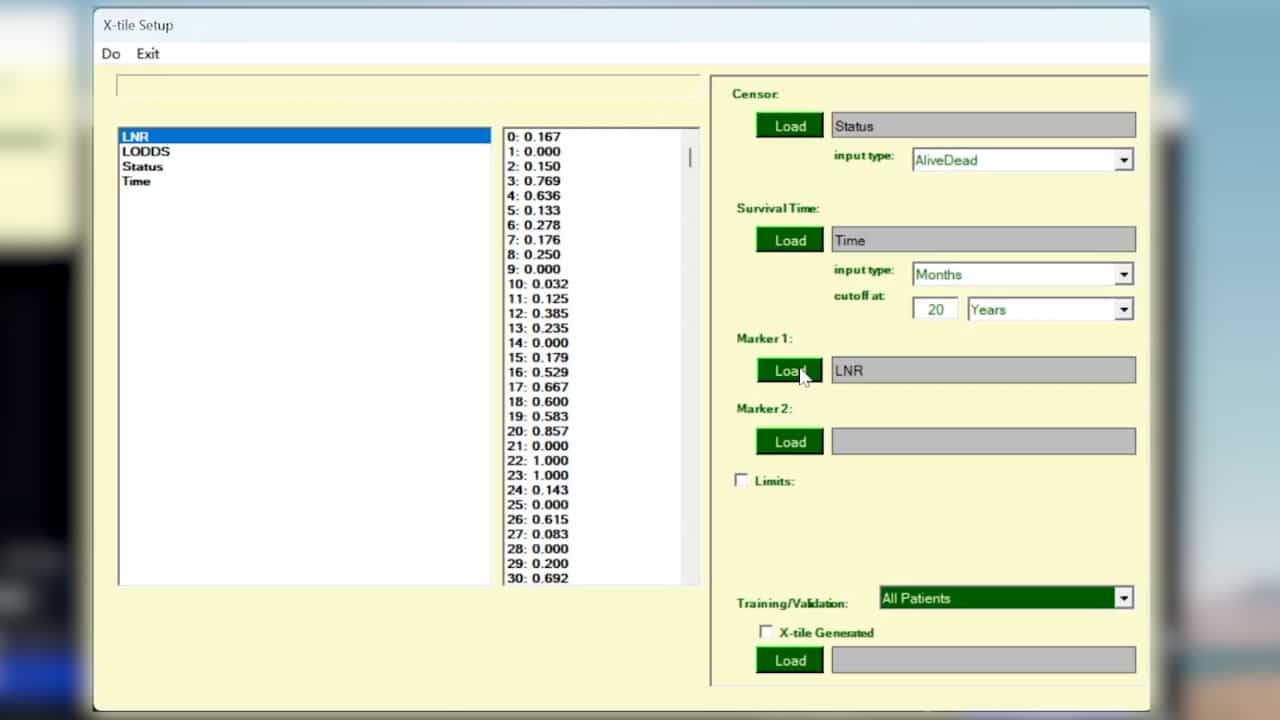

Comparison of Predictive Performance of Three Lymph Node Staging Systems in Colorectal Signet Ring Cell Carcinoma Based on Machine Learning Model
Published on: April 18, 2025
An introspective comparison of random forest-based classifiers for the analysis of cluster-correlated data by way of
Yuliya V Karpievitch1, Elizabeth G Hill, Anthony P Leclerc
1Department of Statistics, Texas A&M University, College Station, Texas, USA. yuliya@stat.tamu.edu

Abstract:
Many mass spectrometry-based studies, as well as other biological experiments produce cluster-correlated data. Failure to account for correlation among observations may result in a classification algorithm overfitting the training data and producing overoptimistic estimated error rates and may make subsequent classifications unreliable. Current common practice for dealing with replicated data is to average each subject replicate sample set, reducing the dataset size and incurring loss of information. In this manuscript we compare three approaches to dealing with cluster-correlated data: unmodified Breiman's Random Forest (URF), forest grown using subject-level averages (SLA), and RF++ with subject-level bootstrapping (SLB). RF++, a novel Random Forest-based algorithm implemented in C++, handles cluster-correlated data through a modification of the original resampling algorithm and accommodates subject-level classification. Subject-level bootstrapping is an alternative sampling method that obviates the need to average or otherwise reduce each set of replicates to a single independent sample. Our experiments show nearly identical median classification and variable selection accuracy for SLB forests and URF forests when applied to both simulated and real datasets. However, the run-time estimated error rate was severely underestimated for URF forests. Predictably, SLA forests were found to be more severely affected by the reduction in sample size which led to poorer classification and variable selection accuracy. Perhaps most importantly our results suggest that it is reasonable to utilize URF for the analysis of cluster-correlated data. Two caveats should be noted: first, correct classification error rates must be obtained using a separate test dataset, and second, an additional post-processing step is required to obtain subject-level classifications. RF++ is shown to be an effective alternative for classifying both clustered and non-clustered data. Source code and stand-alone compiled versions of command-line and easy-to-use graphical user interface (GUI) versions of RF++ for Windows and Linux as well as a user manual (Supplementary File S2) are available for download at: http://sourceforge.org/projects/rfpp/ under the GNU public license.
More Related Videos

Related Concept Videos
 01:23
Correlation of Experimental Data
For example, a spherical particle moving through a viscous fluid experiences drag. Dimensional analysis shows that the drag force depends on the particle's diameter, velocity, and...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 00:53
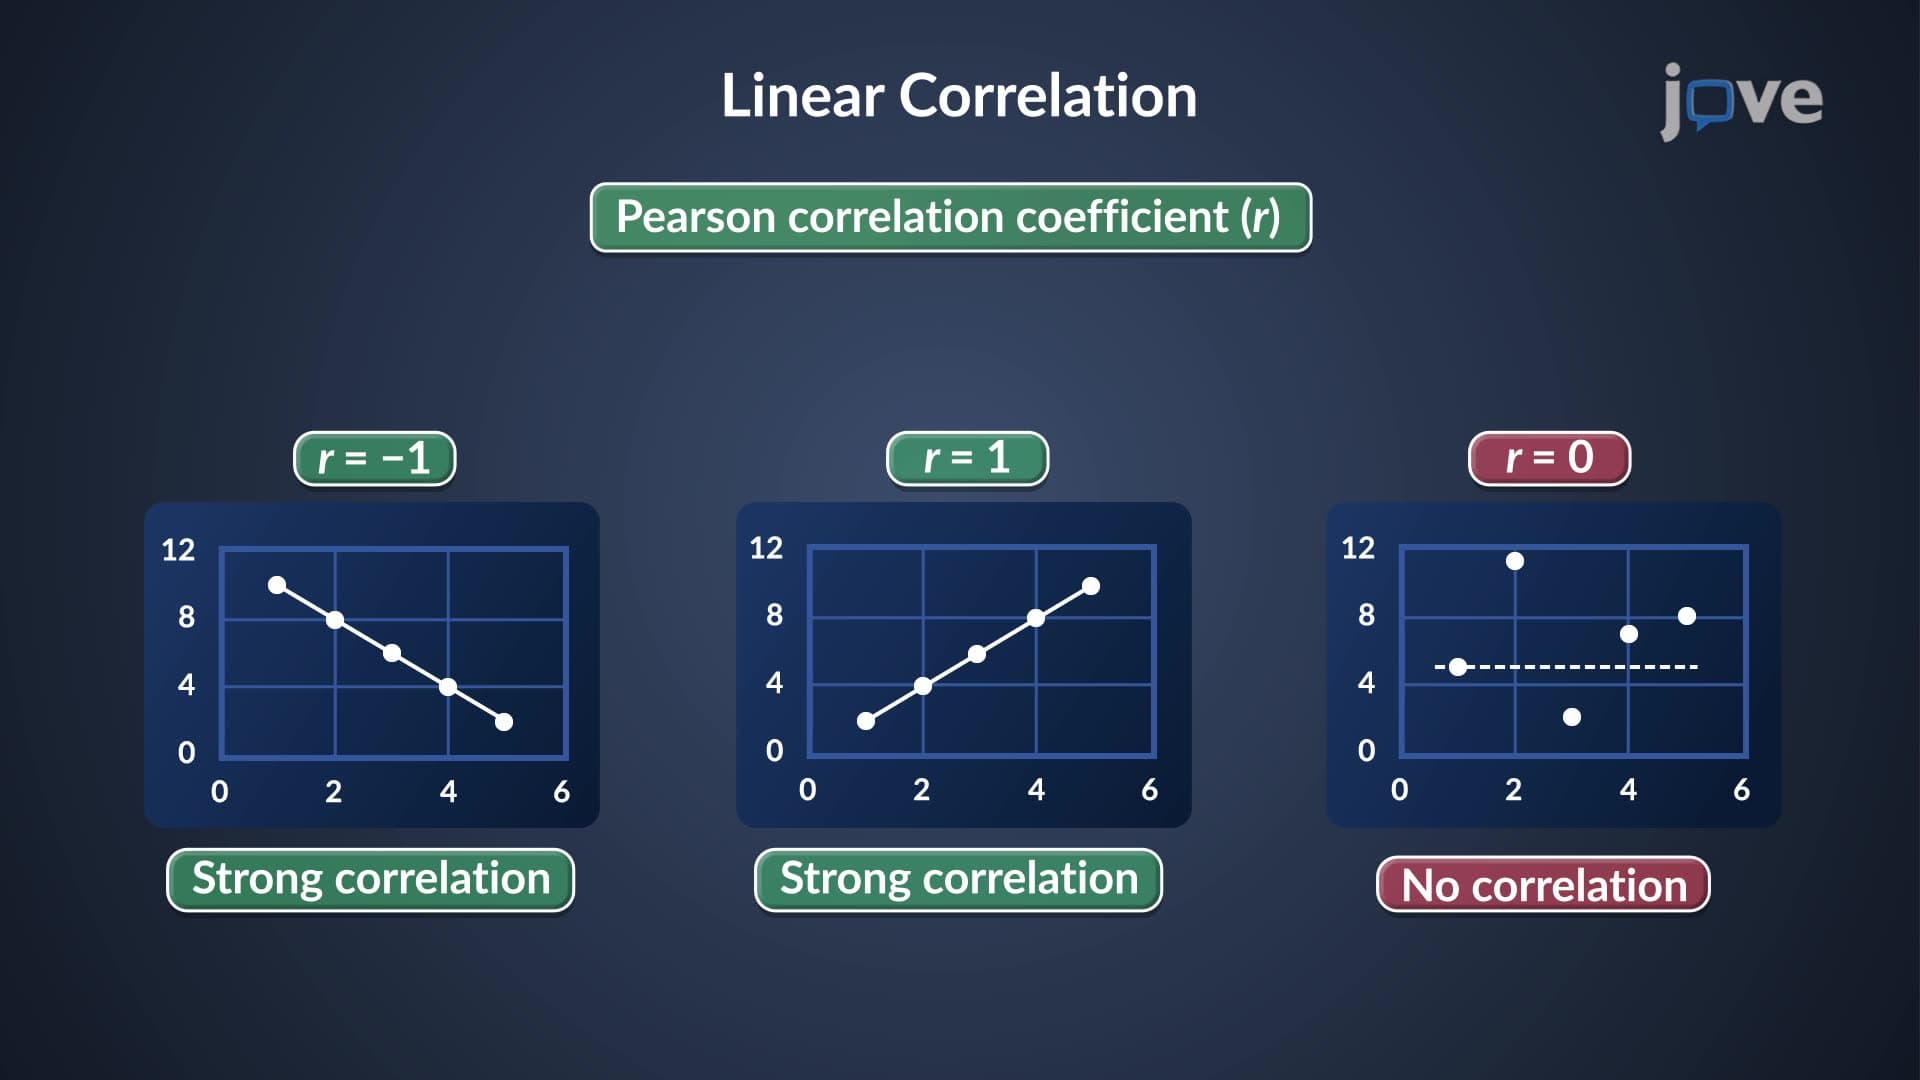
Correlation and Regression
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
 01:21
Friedman Two-way Analysis of Variance by Ranks