Related Experiment Videos
Modelling count data with excessive zeros: the need for class prediction in zero-inflated models and the issue of
Mark S Gilthorpe1, Morten Frydenberg, Yaping Cheng
1Division of Biostatistics, Centre for Epidemiology and Biostatistics, University of Leeds, Clarendon Way, Leeds, UK. m.s.gilthorpe@leeds.ac.uk

Abstract:
Count data may possess an 'excess' of zeros relative to standard distributions. Zero-inflated Poisson (ZiP) or binomial (ZiB) and generic mixture models have been proposed to deal with such data. We consider biomedical count data with an excess number of zeros and seek to address the following: (i) do zero-inflated models need covariates in the distribution part to predict class membership; (ii) what model-fit criteria have clinical relevance to predicted counts; (iii) can very different model parameterizations have near-identical fit; and (iv) how could model selection and hence model interpretation be aided by considering data generation processes? We show that covariates in the distribution part of zero-inflated models are needed to predict class membership. A range of model-fit criteria should be considered, as consensus is rarely achieved, and considering predicted outcomes may be just as valuable as likelihood-based criteria. Zero-inflated and generic mixture models may be indistinguishable according to both likelihood-based model-fit criteria and predicted outcomes, in which case model differentiation, hence, model selection and interpretation, might be guided by the consideration of a priori data generation processes. Zero-inflated models reflect whether or not there are (or have been) risk differences in disease onset and disease progression, while generic mixture models identify sub-types of individuals with similar risks of disease onset and progression. One or both modelling strategies may be used, though a priori knowledge or clinical impression of data generation might help to distinguish between two or more parameterizations that exhibit similar fit and yield near-identical predicted counts.
Related Concept Videos
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:15
Teeth
In the bud stage, the tooth germ (an aggregation of cells) starts to form in the developing jawbone. During the cap stage, the tooth germ differentiates into enamel organ, dental papilla, and dental sac, which will later develop into the tooth's enamel, dentin and...
 01:13
Parameters Affecting Nonlinear Elimination: Zero-Order Input, First-Order Absorption and Two-Compartment Model
When a drug is administered through a constant intravenous infusion and eliminated via nonlinear pharmacokinetics, it follows zero-order input. For example, oral drugs undergo first-order absorption upon administration and are eliminated through nonlinear pharmacokinetics.
In the case of subcutaneously administered drugs,...
 01:17
Clearance Models: Noncompartmental Models
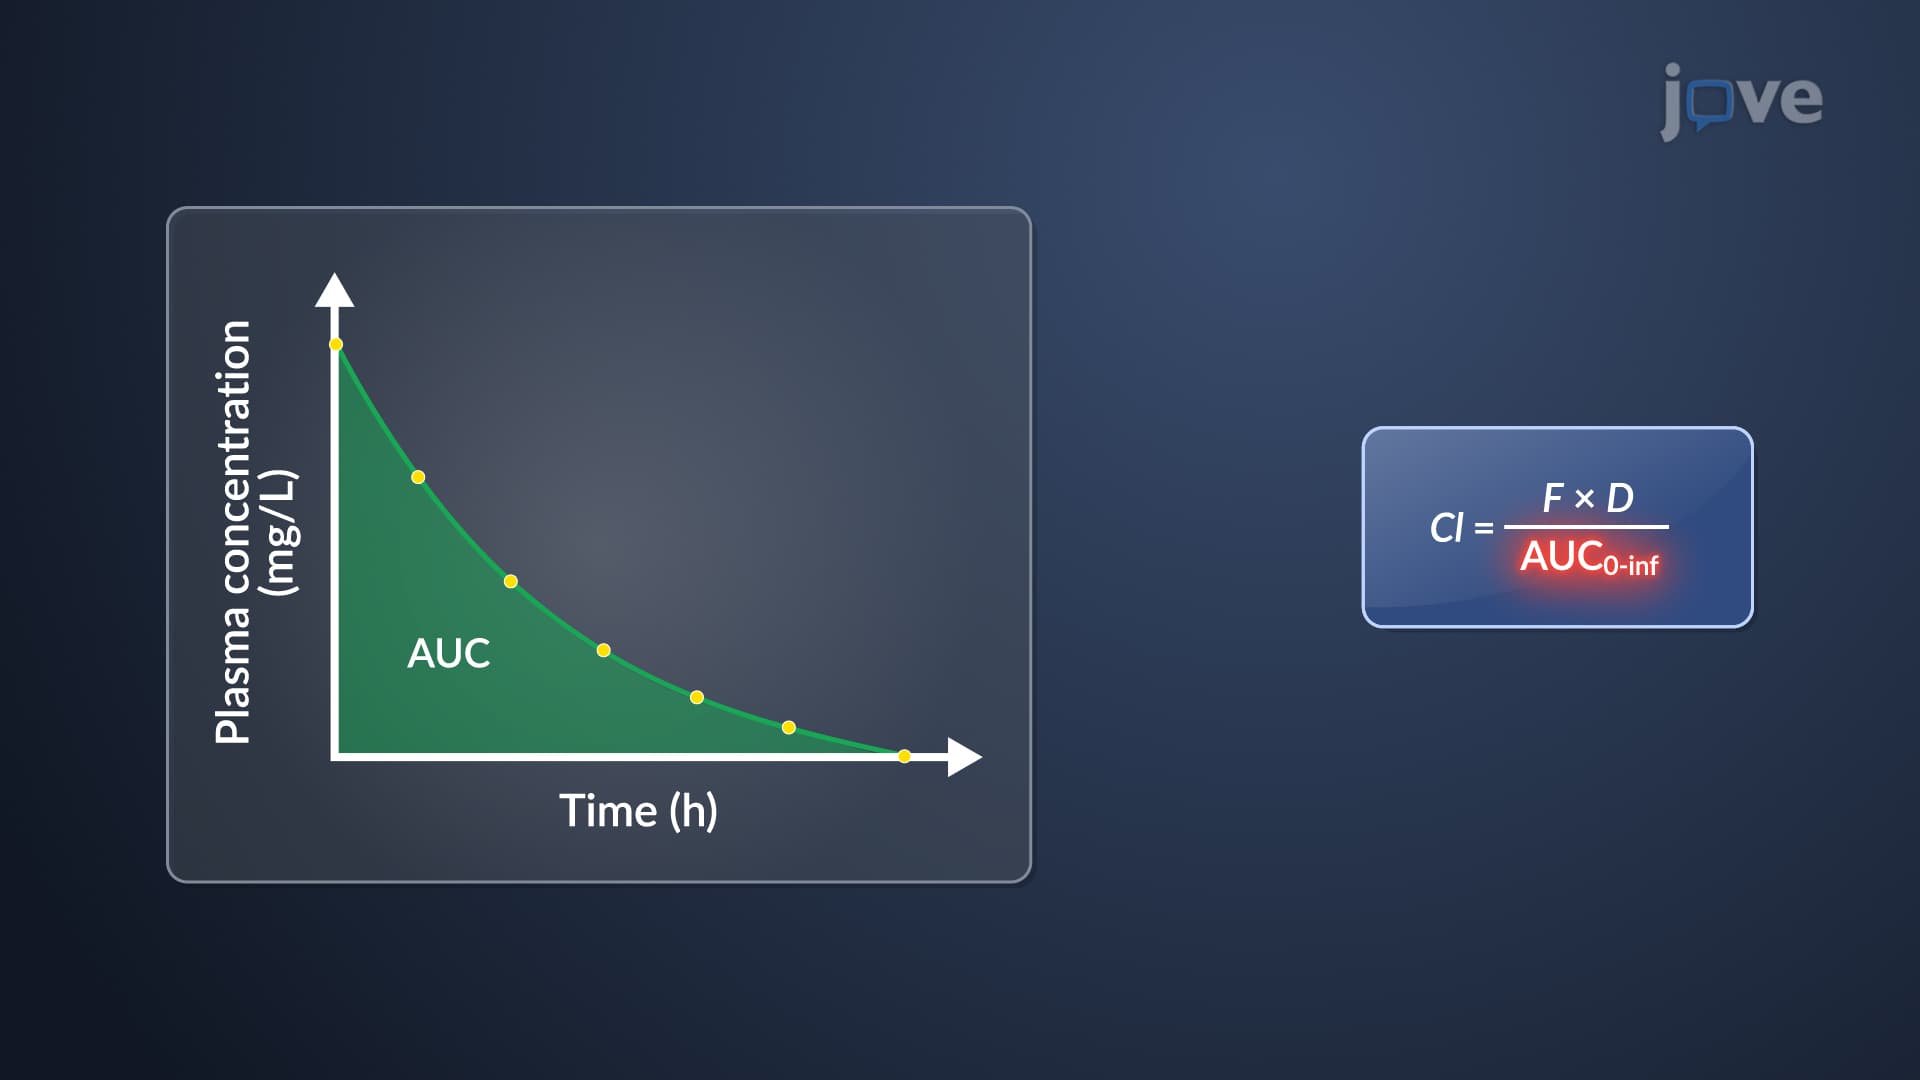
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:14
Model Approaches for Pharmacokinetic Data: Compartment Models
Two primary types of compartment models are recognized: mammillary and catenary. The more...