Related Experiment Video
Updated: Jun 18, 2026

Novel Object Recognition and Object Location Behavioral Testing in Mice on a Budget
Published on: November 20, 2018
P value and the theory of hypothesis testing: an explanation for new researchers
David Jean Biau1, Brigitte M Jolles, Raphaël Porcher
1Département de Biostatistique et Informatique Médicale, INSERM-UMR-S 717, AP-HP, Université Paris 7, Hôpital Saint Louis, 1, Avenue Claude-Vellefaux, Paris Cedex 10 75475, France. djmbiau@yahoo.fr

Abstract:
In the 1920s, Ronald Fisher developed the theory behind the p value and Jerzy Neyman and Egon Pearson developed the theory of hypothesis testing. These distinct theories have provided researchers important quantitative tools to confirm or refute their hypotheses. The p value is the probability to obtain an effect equal to or more extreme than the one observed presuming the null hypothesis of no effect is true; it gives researchers a measure of the strength of evidence against the null hypothesis. As commonly used, investigators will select a threshold p value below which they will reject the null hypothesis. The theory of hypothesis testing allows researchers to reject a null hypothesis in favor of an alternative hypothesis of some effect. As commonly used, investigators choose Type I error (rejecting the null hypothesis when it is true) and Type II error (accepting the null hypothesis when it is false) levels and determine some critical region. If the test statistic falls into that critical region, the null hypothesis is rejected in favor of the alternative hypothesis. Despite similarities between the two, the p value and the theory of hypothesis testing are different theories that often are misunderstood and confused, leading researchers to improper conclusions. Perhaps the most common misconception is to consider the p value as the probability that the null hypothesis is true rather than the probability of obtaining the difference observed, or one that is more extreme, considering the null is true. Another concern is the risk that an important proportion of statistically significant results are falsely significant. Researchers should have a minimum understanding of these two theories so that they are better able to plan, conduct, interpret, and report scientific experiments.
Related Concept Videos
 01:09
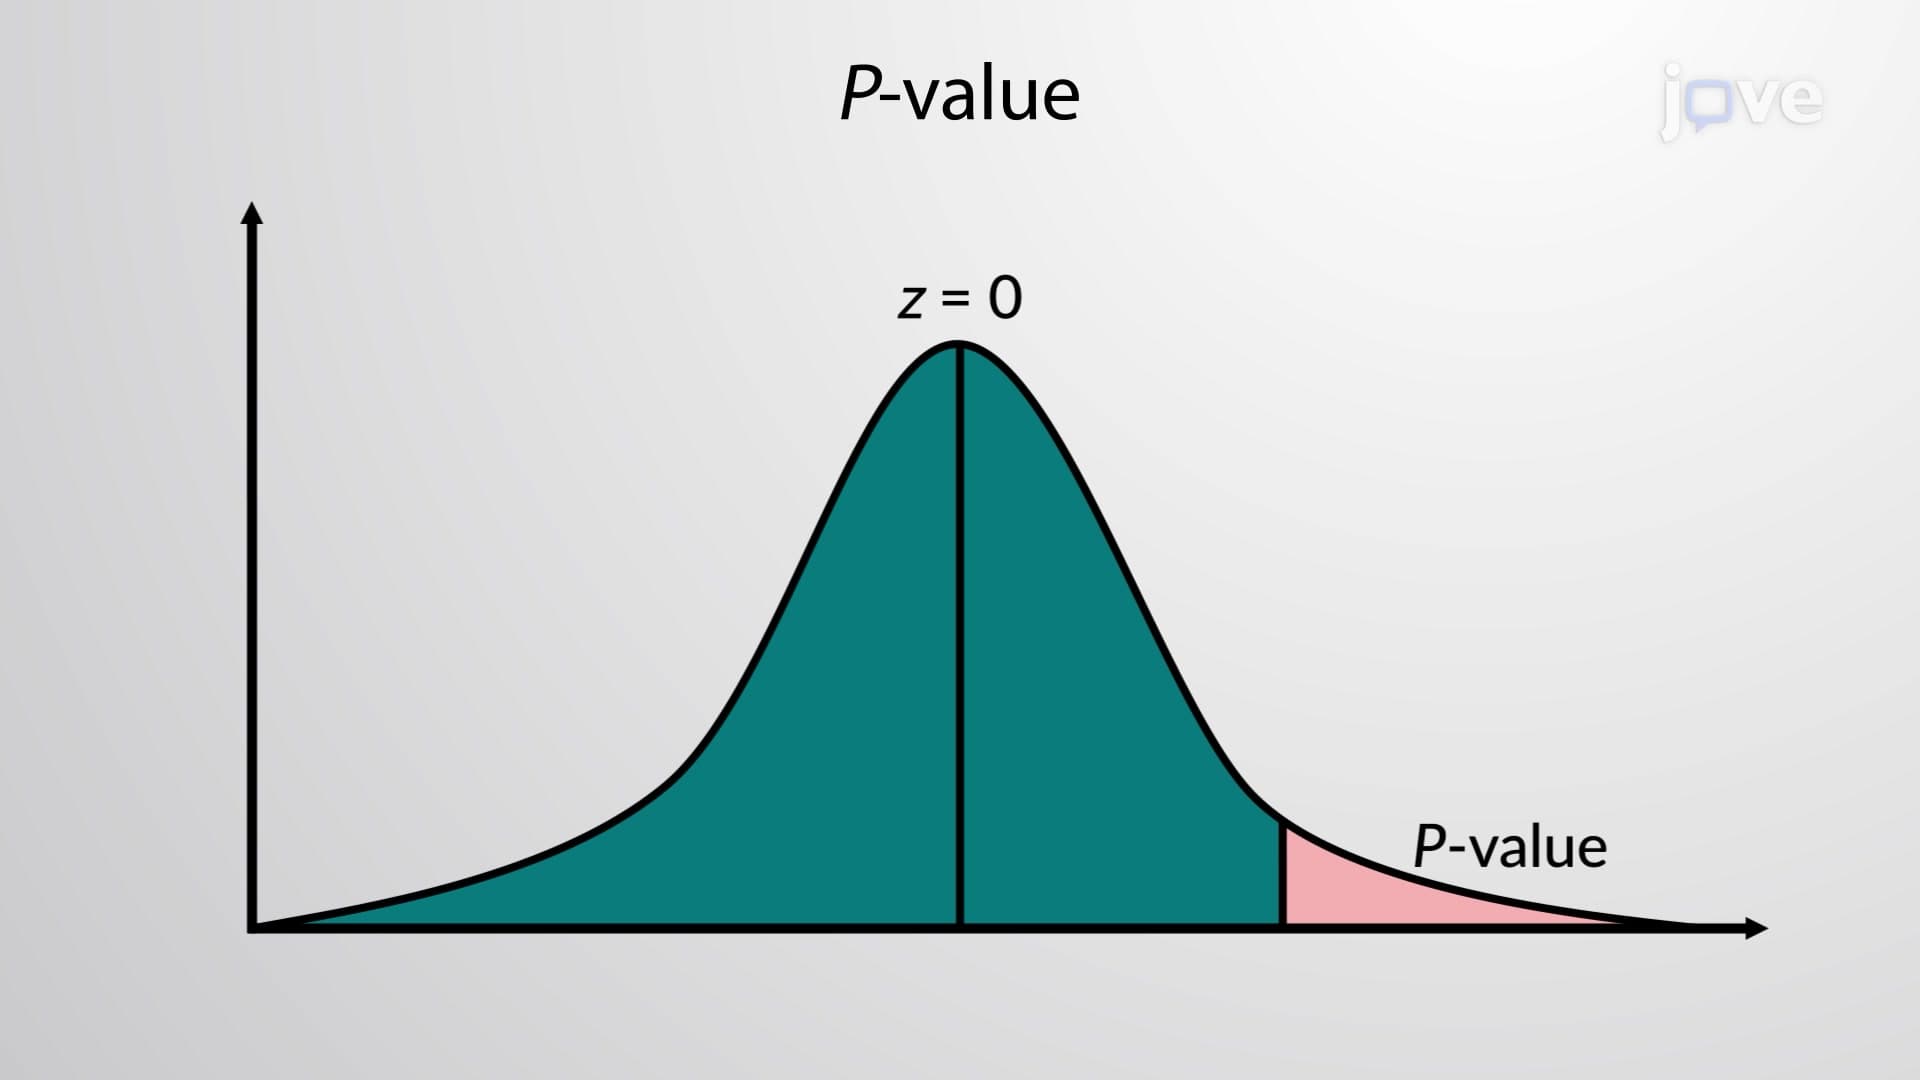
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:16
Statistical Hypothesis Testing
Statistical significance measures the probability that an observed result occurred by chance. If this probability, known as...
 01:14
Decision Making: Traditional Method
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...
 01:16
Null and Alternative Hypotheses
The null hypothesis, denoted by H0 is a statement of no difference between the variables—they are not related. This can often be considered the status quo. As a result if you cannot accept the null, it requires some action.
The alternative hypothesis, denoted by H1 or Ha, is a claim about the population that is...
 01:14
What is a Hypothesis?