Related Experiment Video
Updated: Jun 17, 2026
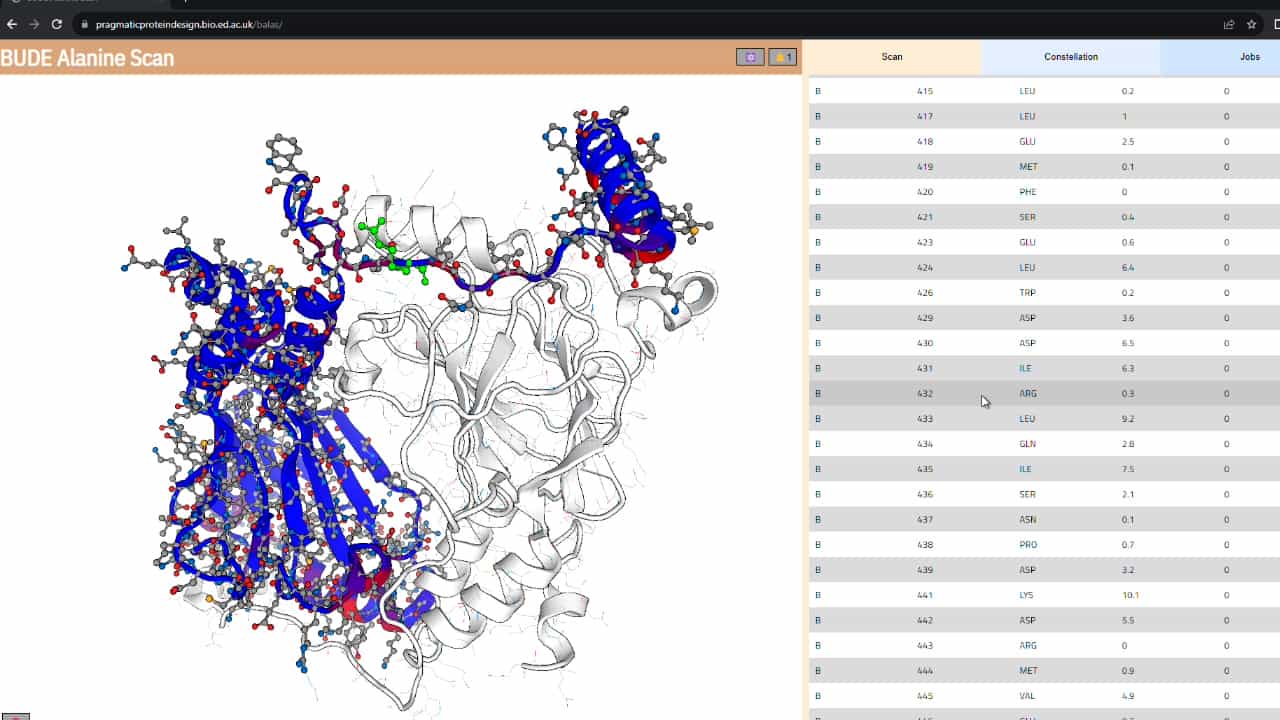
Computational Prediction of Amino Acid Preferences of Potentially Multispecific Peptide-Binding Domains Involved in Protein-Protein Interactions
Published on: January 26, 2024
Estimation and efficient computation of the true probability of recurrence of short linear protein sequence motifs in
Norman E Davey1, Richard J Edwards, Denis C Shields
1UCD Complex and Adaptive Systems Laboratory, University College Dublin, Dublin, Ireland. davey@embl.de

Background:
Large datasets of protein interactions provide a rich resource for the discovery of Short Linear Motifs (SLiMs) that recur in unrelated proteins. However, existing methods for estimating the probability of motif recurrence may be biased by the size and composition of the search dataset, such that p-value estimates from different datasets, or from motifs containing different numbers of non-wildcard positions, are not strictly comparable. Here, we develop more exact methods and explore the potential biases of computationally efficient approximations.
Results:
A widely used heuristic for the calculation of motif over-representation approximates motif probability by assuming that all proteins have the same length and composition. We introduce pv, which calculates the probability exactly. Secondly, the recently introduced SLiMFinder statistic Sig, accounts for multiple testing (across all possible motifs) in motif discovery. However, it approximates the probability of all other possible motifs, occurring with a score of p or less, as being equal to p. Here, we show that the exhaustive calculation of the probability of all possible motif occurrences that are as rare or rarer than the motif of interest, Sig', may be carried out efficiently by grouping motifs of a common probability (i.e. those which have permuted orders of the same residues). Sig'v, which corrects both approximations, is shown to be uniformly distributed in a random dataset when searching for non-ambiguous motifs, indicating that it is a robust significance measure.
Conclusions:
A method is presented to compute exactly the true probability of a non-ambiguous short protein sequence motif, and the utility of an approximate approach for novel motif discovery across a large number of datasets is demonstrated.

Related Concept Videos
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
 02:04
Protein-protein Interfaces
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 02:47
Protein Families
02:26Conservation of Protein Domains
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...