Related Experiment Videos
Efficient exploration through active learning for value function approximation in reinforcement learning
Takayuki Akiyama1, Hirotaka Hachiya, Masashi Sugiyama
1Department of Computer Science, Tokyo Institute of Technology, 2-12-1 O-okayama, Meguro-ku, Tokyo 152-8552, Japan. akiyama@sg.cs.titech.ac.jp

Abstract:
Appropriately designing sampling policies is highly important for obtaining better control policies in reinforcement learning. In this paper, we first show that the least-squares policy iteration (LSPI) framework allows us to employ statistical active learning methods for linear regression. Then we propose a design method of good sampling policies for efficient exploration, which is particularly useful when the sampling cost of immediate rewards is high. The effectiveness of the proposed method, which we call active policy iteration (API), is demonstrated through simulations with a batting robot.
Related Concept Videos
 01:09
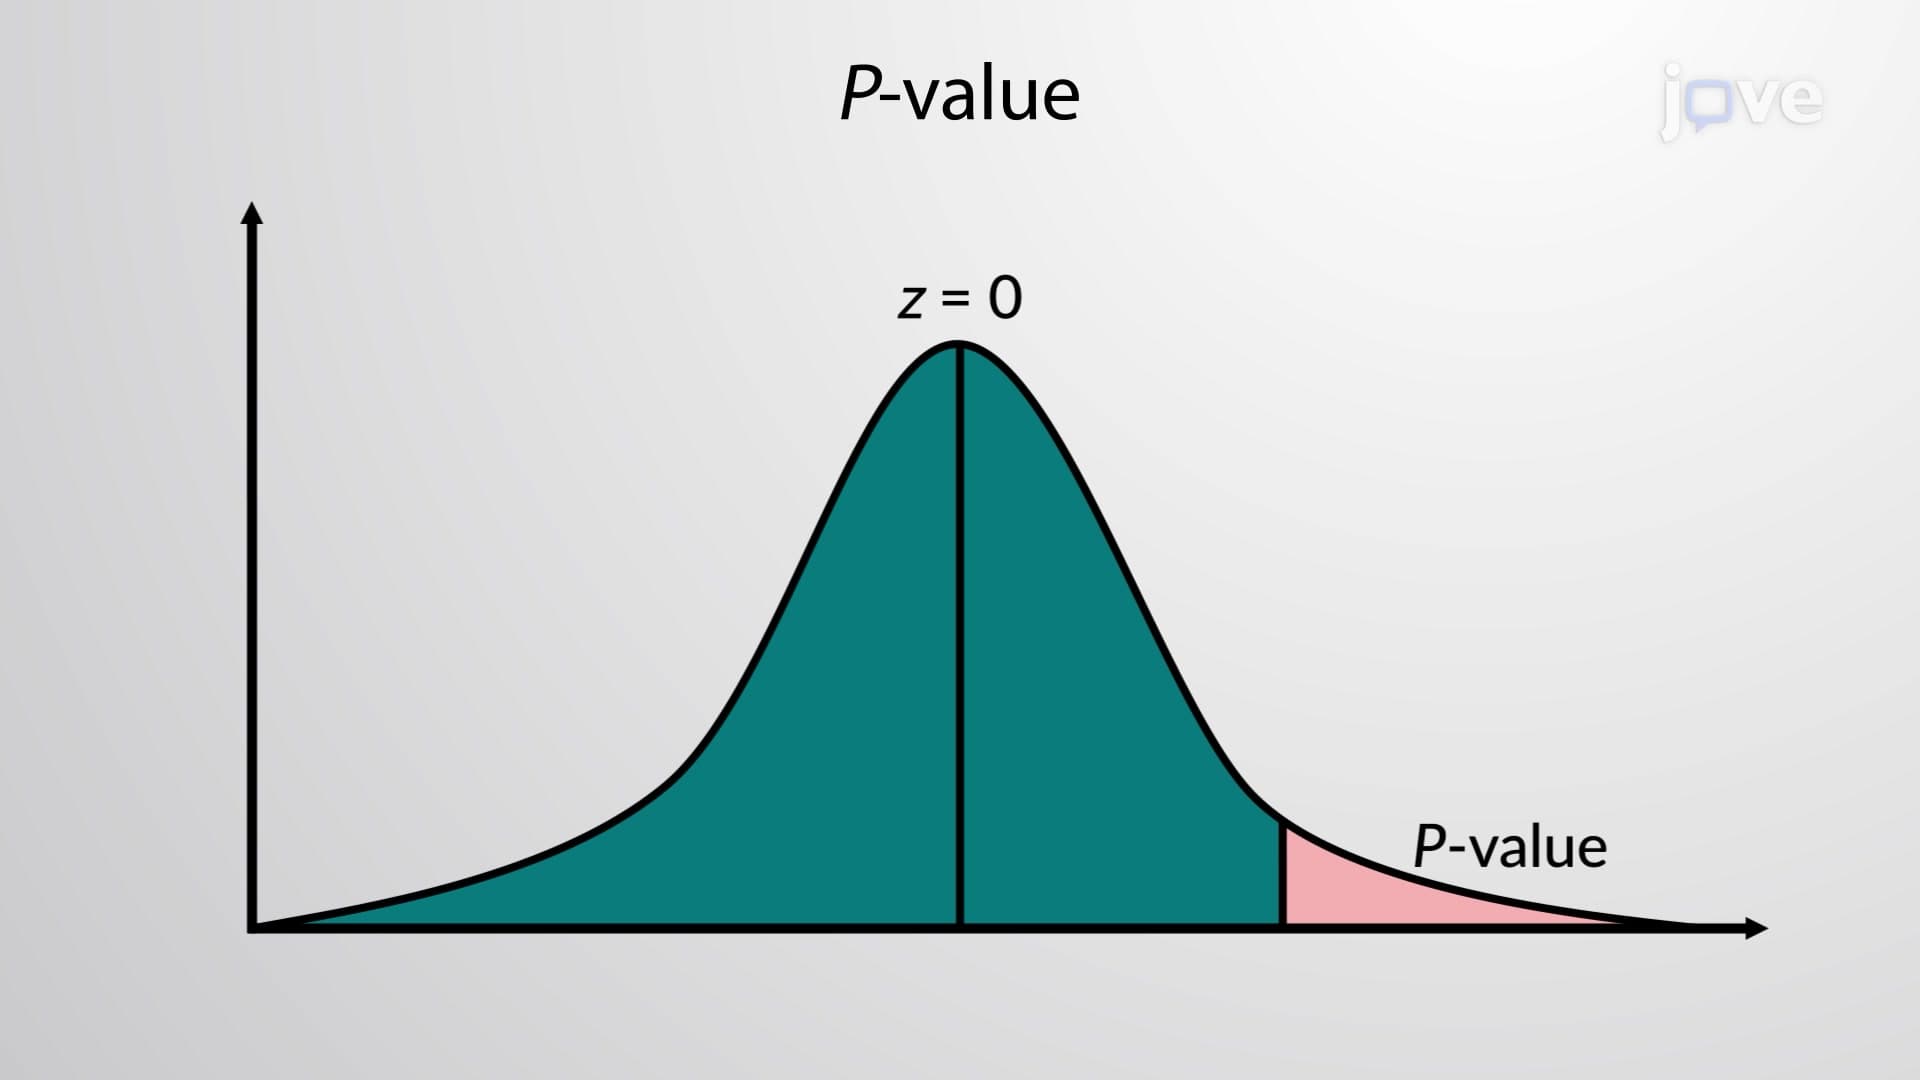
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:12
Observational Learning
 01:24
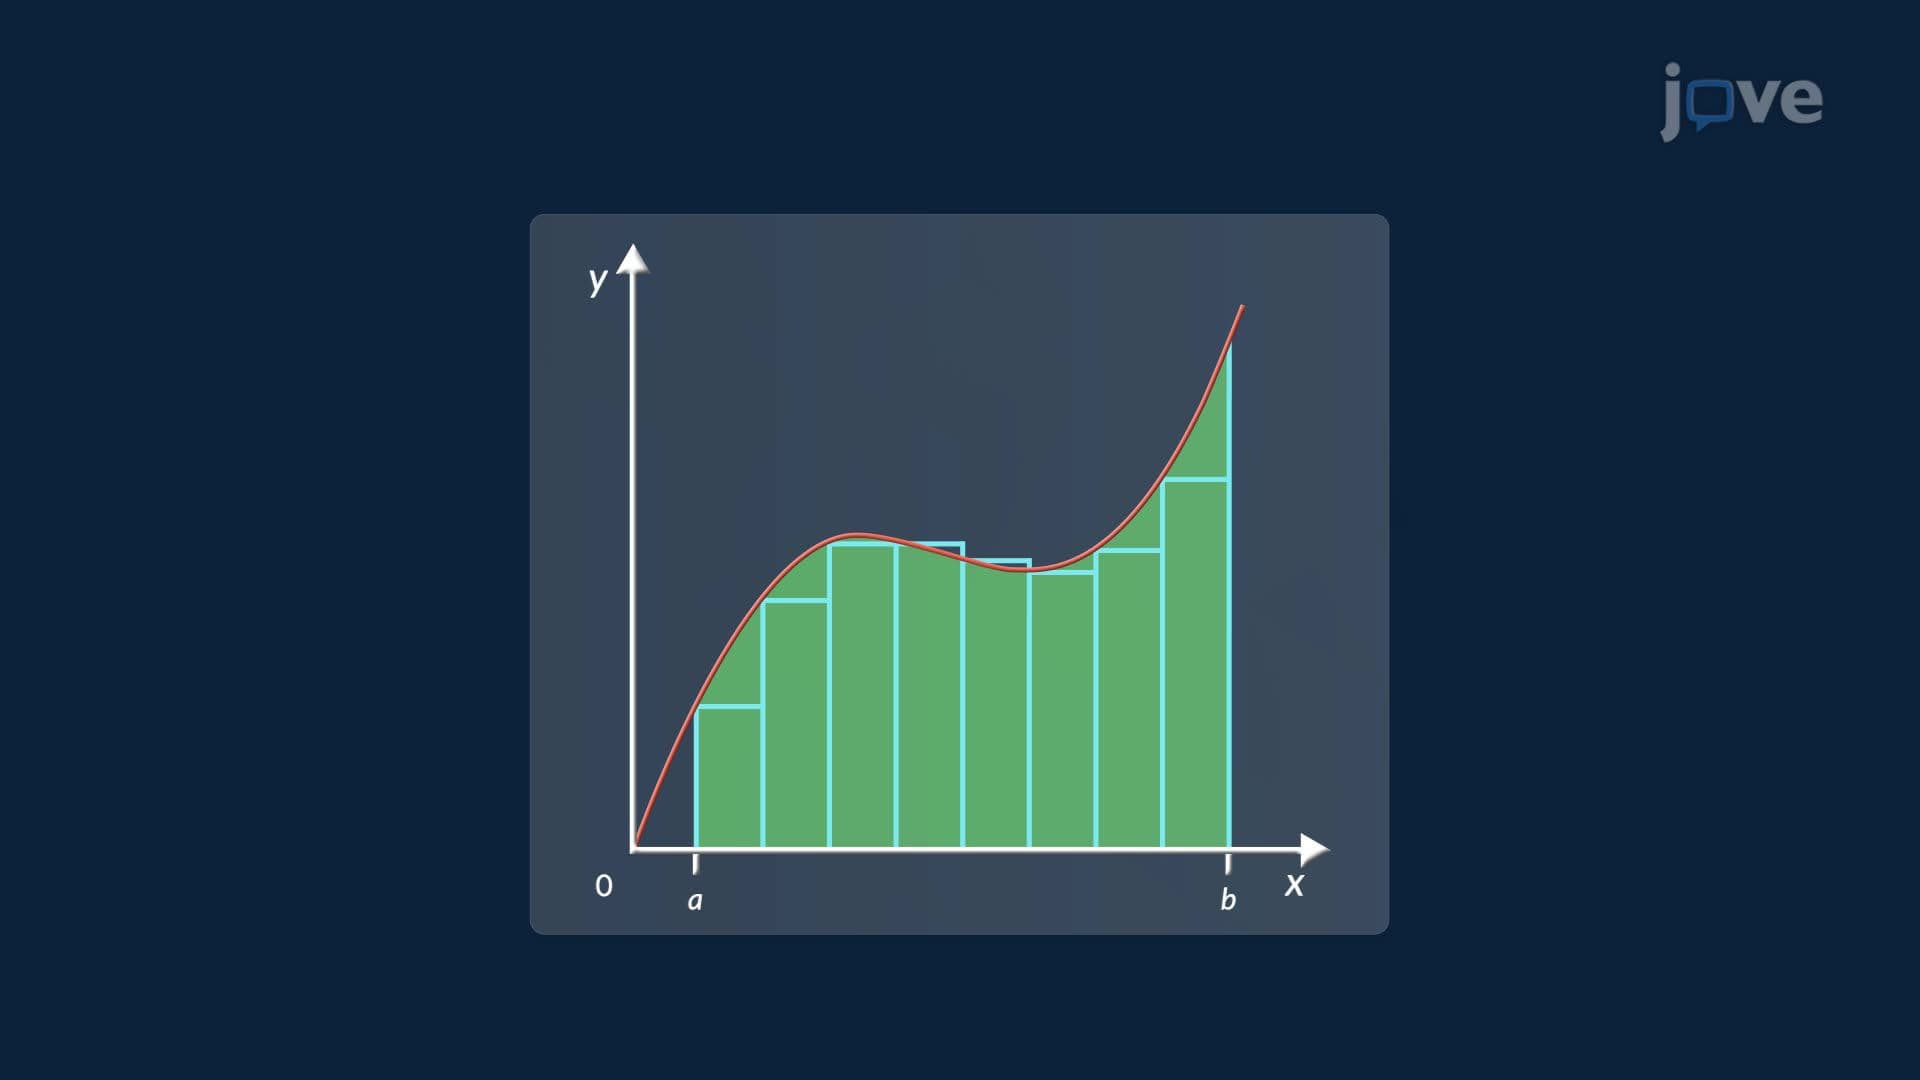
Approximate Integration
 01:14
Avoidance Learning and Learned Helplessness
Avoidance learning occurs when an organism learns that a specific behavior can prevent an unpleasant outcome. For example, a student who receives a bad grade may start studying harder to avoid future poor grades. This behavior persists even when the negative outcome is no longer present. Avoidance learning is powerful because it maintains behavior in the absence of the...
 01:29
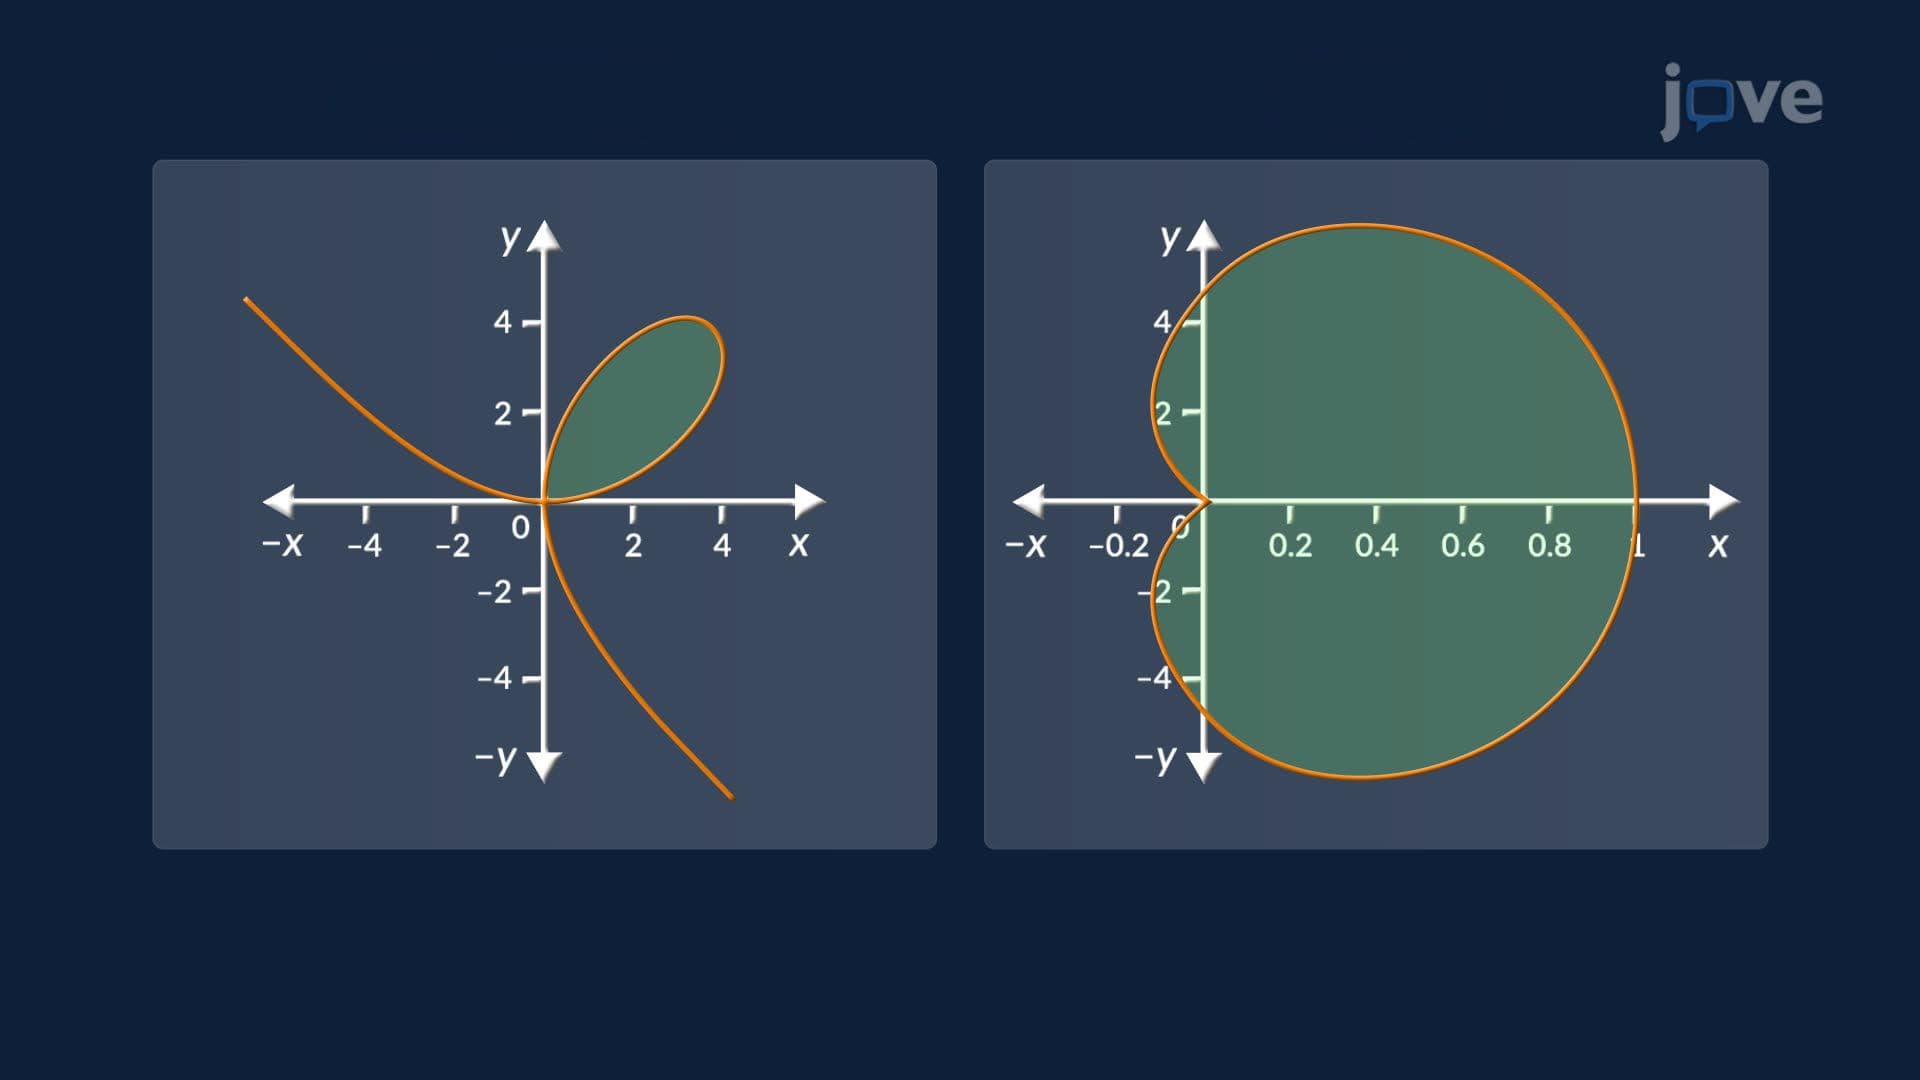
Implicit Differentiation: Problem Solving