Local-learning-based feature selection for high-dimensional data analysis
Related Experiment Video
Updated: Jun 10, 2026
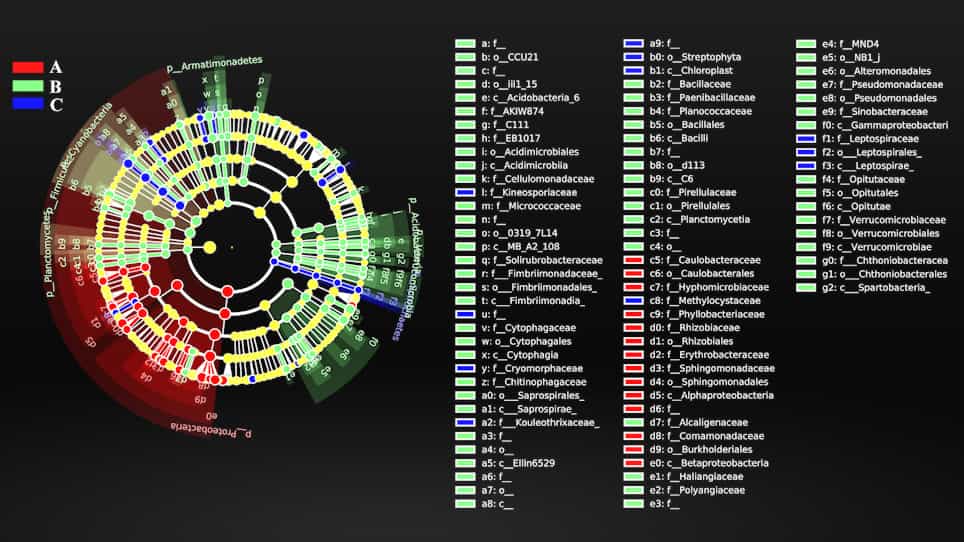
Assisted Selection of Biomarkers by Linear Discriminant Analysis Effect Size (LEfSe) in Microbiome Data
Published on: May 16, 2022
Yijun Sun1, Sinisa Todorovic, Steve Goodison
1Interdisciplinary Center for Biotechnology Research, University of Florida, PO Box 103622, Gainesville, FL 32610-3622, USA. sunyijun@biotech.ufl.edu

Abstract:
This paper considers feature selection for data classification in the presence of a huge number of irrelevant features. We propose a new feature-selection algorithm that addresses several major issues with prior work, including problems with algorithm implementation, computational complexity, and solution accuracy. The key idea is to decompose an arbitrarily complex nonlinear problem into a set of locally linear ones through local learning, and then learn feature relevance globally within the large margin framework. The proposed algorithm is based on well-established machine learning and numerical analysis techniques, without making any assumptions about the underlying data distribution. It is capable of processing many thousands of features within minutes on a personal computer while maintaining a very high accuracy that is nearly insensitive to a growing number of irrelevant features. Theoretical analyses of the algorithm's sample complexity suggest that the algorithm has a logarithmical sample complexity with respect to the number of features. Experiments on 11 synthetic and real-world data sets demonstrate the viability of our formulation of the feature-selection problem for supervised learning and the effectiveness of our algorithm.