Related Experiment Video
Updated: Jun 10, 2026

An Integrated Approach for Microprotein Identification and Sequence Analysis
Published on: July 12, 2022
More than 1,001 problems with protein domain databases: transmembrane regions, signal peptides and the issue of
Wing-Cheong Wong1, Sebastian Maurer-Stroh, Frank Eisenhaber
1Bioinformatics Institute (BII), Agency for Science, Technology and Research (A*STAR), Singapore. wongwc@bii-sg.org

Abstract:
Large-scale genome sequencing gained general importance for life science because functional annotation of otherwise experimentally uncharacterized sequences is made possible by the theory of biomolecular sequence homology. Historically, the paradigm of similarity of protein sequences implying common structure, function and ancestry was generalized based on studies of globular domains. Having the same fold imposes strict conditions over the packing in the hydrophobic core requiring similarity of hydrophobic patterns. The implications of sequence similarity among non-globular protein segments have not been studied to the same extent; nevertheless, homology considerations are silently extended for them. This appears especially detrimental in the case of transmembrane helices (TMs) and signal peptides (SPs) where sequence similarity is necessarily a consequence of physical requirements rather than common ancestry. Thus, matching of SPs/TMs creates the illusion of matching hydrophobic cores. Therefore, inclusion of SPs/TMs into domain models can give rise to wrong annotations. More than 1001 domains among the 10,340 models of Pfam release 23 and 18 domains of SMART version 6 (out of 809) contain SP/TM regions. As expected, fragment-mode HMM searches generate promiscuous hits limited to solely the SP/TM part among clearly unrelated proteins. More worryingly, we show explicit examples that the scores of clearly false-positive hits, even in global-mode searches, can be elevated into the significance range just by matching the hydrophobic runs. In the PIR iProClass database v3.74 using conservative criteria, we find that at least between 2.1% and 13.6% of its annotated Pfam hits appear unjustified for a set of validated domain models. Thus, false-positive domain hits enforced by SP/TM regions can lead to dramatic annotation errors where the hit has nothing in common with the problematic domain model except the SP/TM region itself. We suggest a workflow of flagging problematic hits arising from SP/TM-containing models for critical reconsideration by annotation users.


Related Concept Videos
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:29
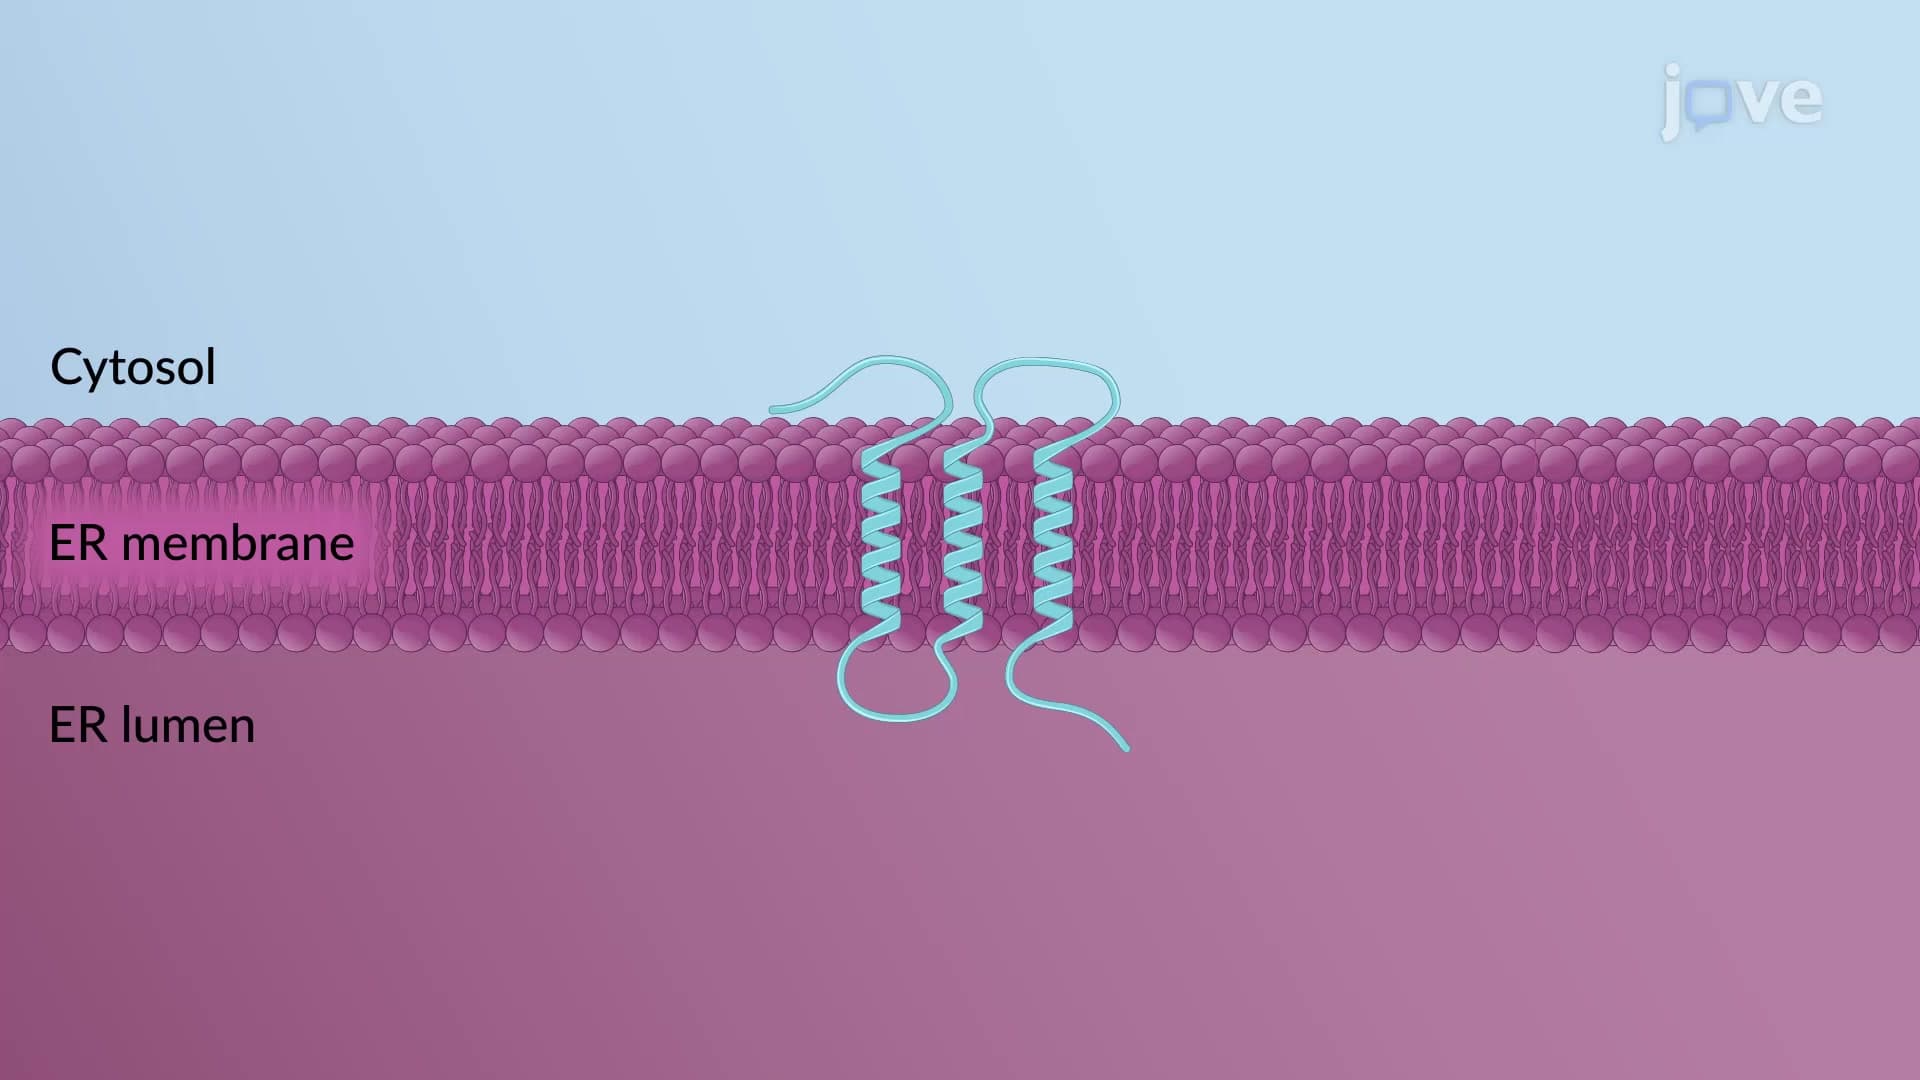
Insertion of Multi-pass Transmembrane Proteins in the RER
The multipass transmembrane proteins are the type IV integral membrane proteins with multiple topogenic sequences determining their spatial arrangement in the ER membrane. Nearly all multipass proteins lack a cleavable signal sequence and use...
 01:25
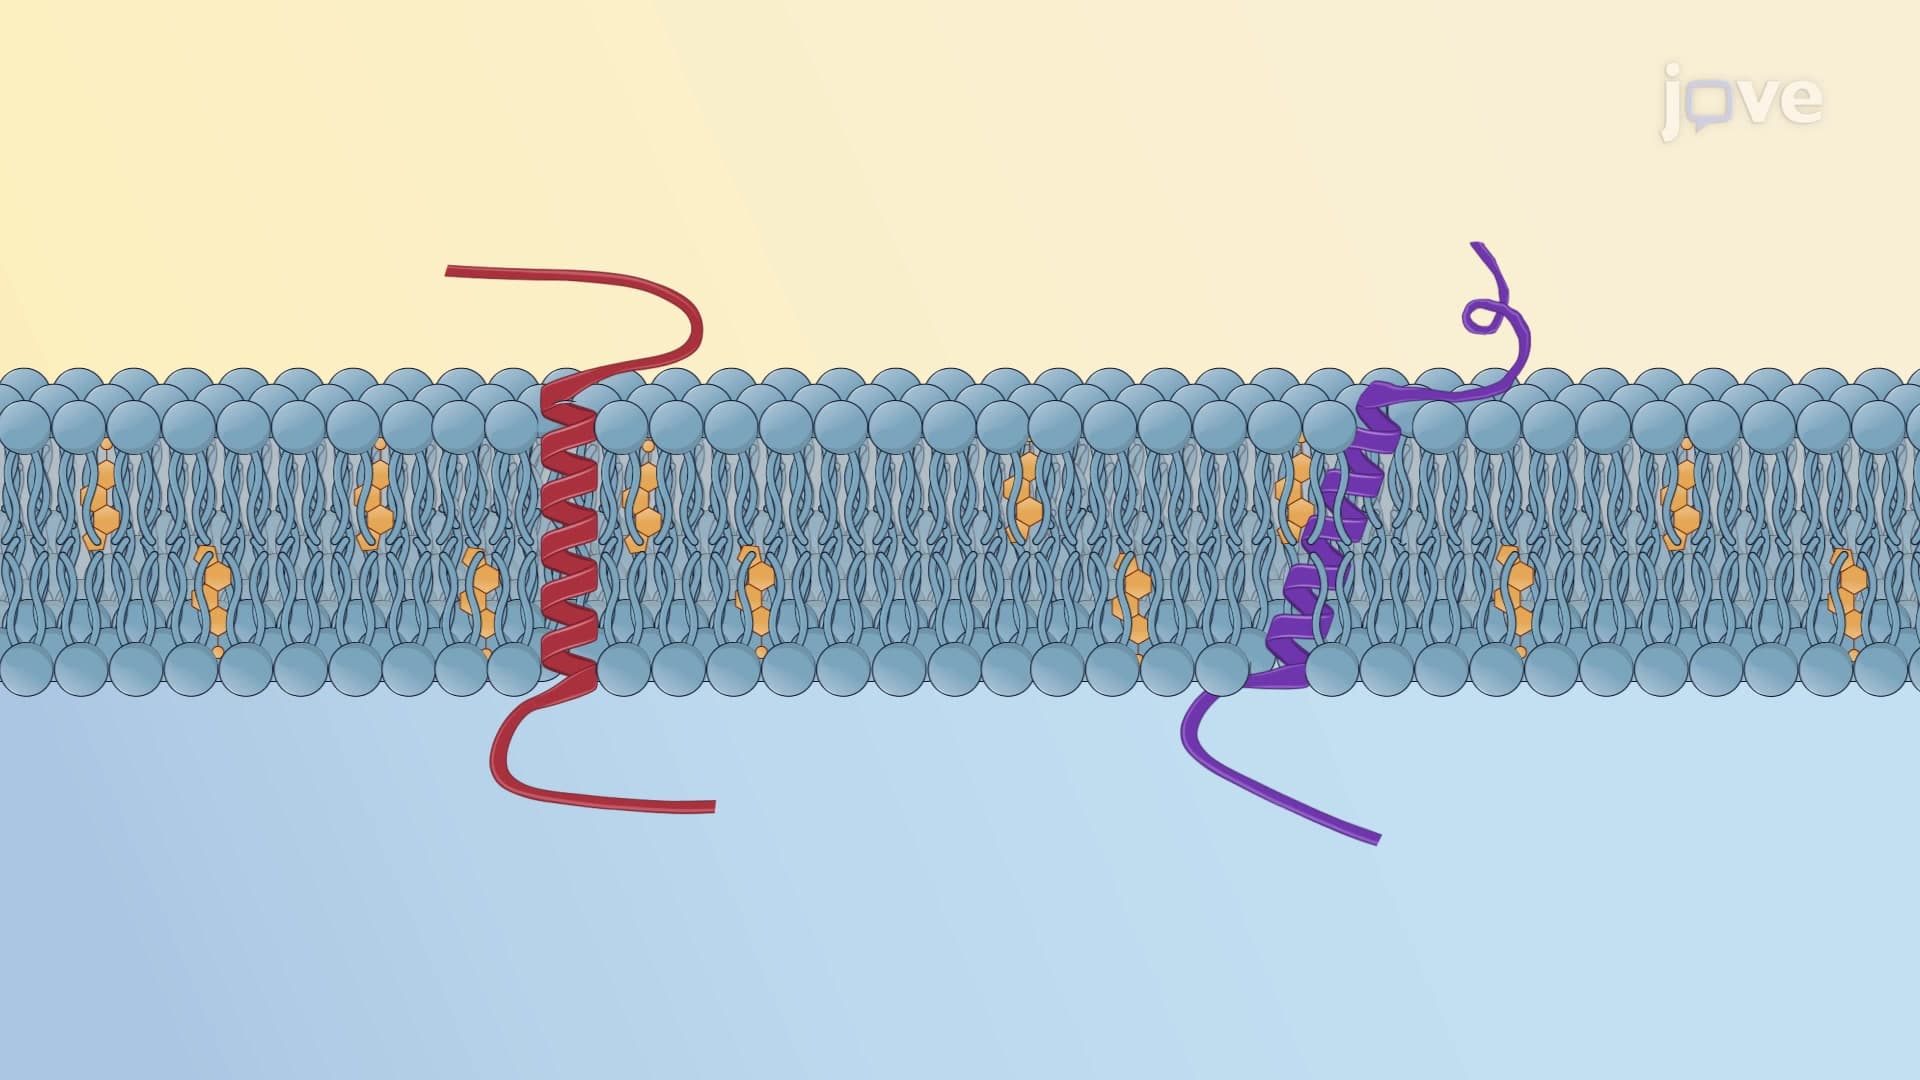
Single-pass Transmembrane Proteins
 02:47
Protein Families
 01:09
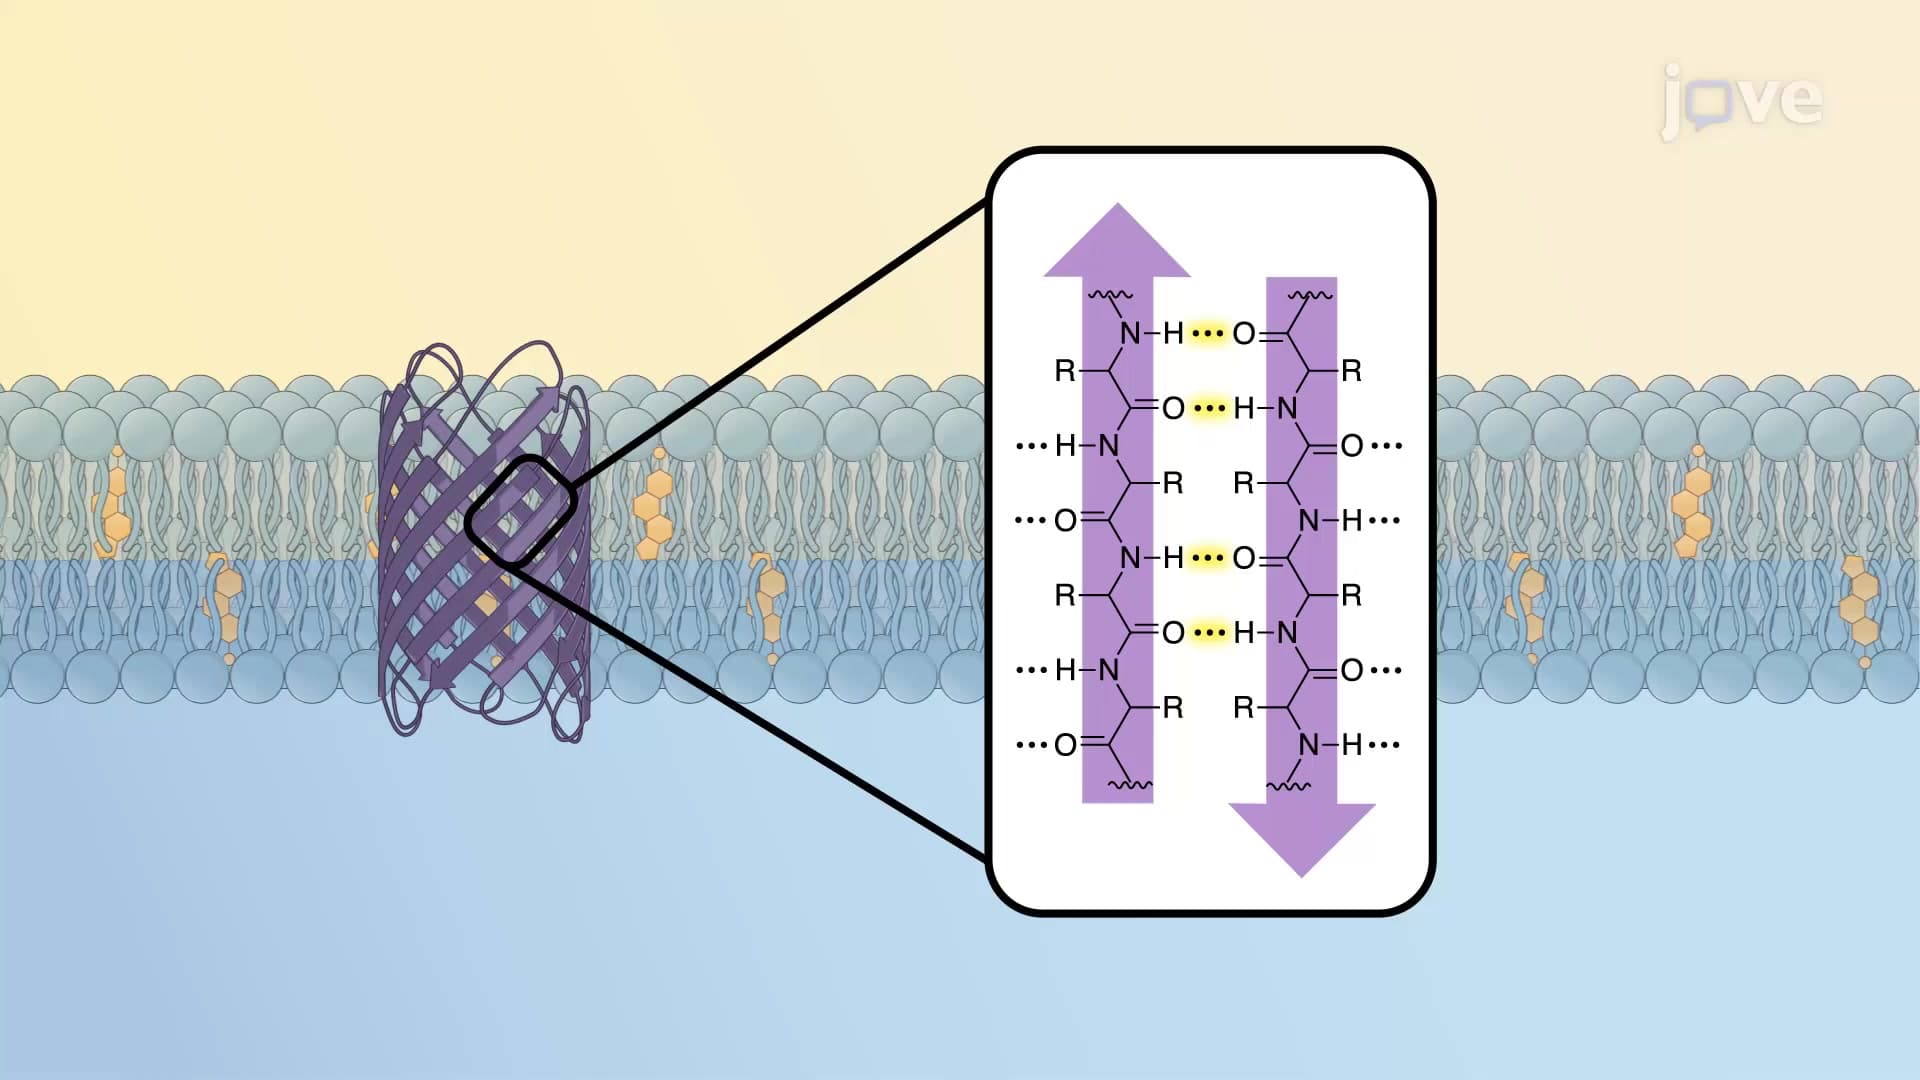
Multi-pass Transmembrane Proteins and β-barrels
α-Helix containing multi-pass transmembrane proteins
Multi-pass transmembrane proteins such as G-protein-linked receptors (GPCRs) and...
 01:41
Signal Sequences and Sorting Receptors