Related Experiment Video
Updated: Jun 6, 2026

Problem-Solving Before Instruction (PS-I): A Protocol for Assessment and Intervention in Students with Different Abilities
Published on: September 11, 2021
The cost of large numbers of hypothesis tests on power, effect size and sample size
1Department of Psychiatry and Behavioral Sciences, Stanford University School of Medicine, Stanford, CA 94305-5723, USA. lazzeroni@stanford.edu

Abstract:
Advances in high-throughput biology and computer science are driving an exponential increase in the number of hypothesis tests in genomics and other scientific disciplines. Studies using current genotyping platforms frequently include a million or more tests. In addition to the monetary cost, this increase imposes a statistical cost owing to the multiple testing corrections needed to avoid large numbers of false-positive results. To safeguard against the resulting loss of power, some have suggested sample sizes on the order of tens of thousands that can be impractical for many diseases or may lower the quality of phenotypic measurements. This study examines the relationship between the number of tests on the one hand and power, detectable effect size or required sample size on the other. We show that once the number of tests is large, power can be maintained at a constant level, with comparatively small increases in the effect size or sample size. For example at the 0.05 significance level, a 13% increase in sample size is needed to maintain 80% power for ten million tests compared with one million tests, whereas a 70% increase in sample size is needed for 10 tests compared with a single test. Relative costs are less when measured by increases in the detectable effect size. We provide an interactive Excel calculator to compute power, effect size or sample size when comparing study designs or genome platforms involving different numbers of hypothesis tests. The results are reassuring in an era of extreme multiple testing.
More Related Videos
Related Concept Videos
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...
 01:16
Statistical Hypothesis Testing
Statistical significance measures the probability that an observed result occurred by chance. If this probability, known as...
 01:14
Errors In Hypothesis Tests
 01:14
Decision Making: Traditional Method
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
 01:09
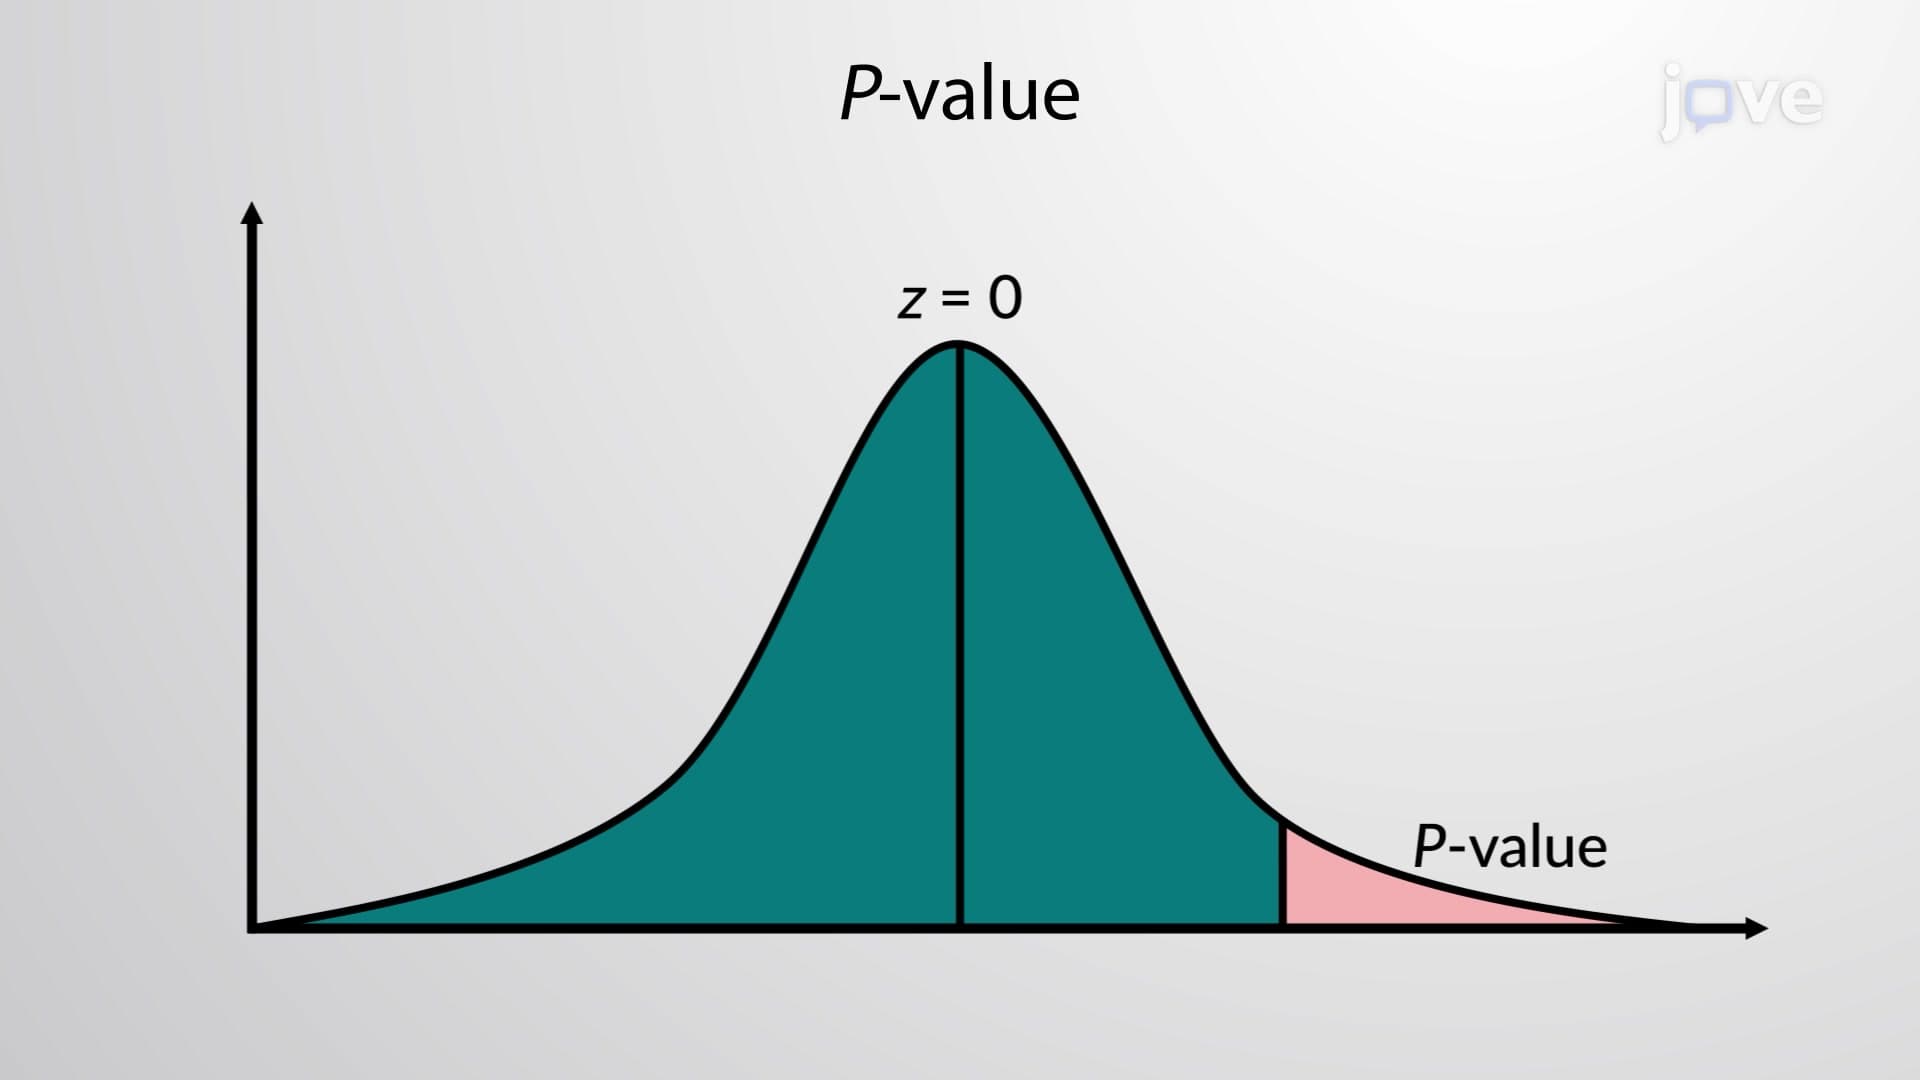
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:11
Types of Hypothesis Testing
When the null and alternative hypotheses are stated, it is observed that the null hypothesis is a neutral statement against which the alternative hypothesis is tested. The alternative hypothesis is a claim that instead has a certain direction. If the null hypothesis claims that p = 0.5, the alternative hypothesis would be an opposing statement to this and can be put either p > 0.5, p < 0.5, or p ≠ 0.5.