Related Experiment Video
Updated: Jun 6, 2026
04:52

Following the Dynamics of Structural Variants in Experimentally Evolved Populations
Published on: February 3, 2023
Reply to the comment by Bachmaier (2010) "On the misleading use of the term 'semivariance' in recent articles"
Rapid Communications in Mass Spectrometry : RCM
|November 13, 2010

Abstract
No abstract available in PubMed .

Related Concept Videos
 01:52
Regression Toward the Mean
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when researchers try to extrapolate results...
 01:11
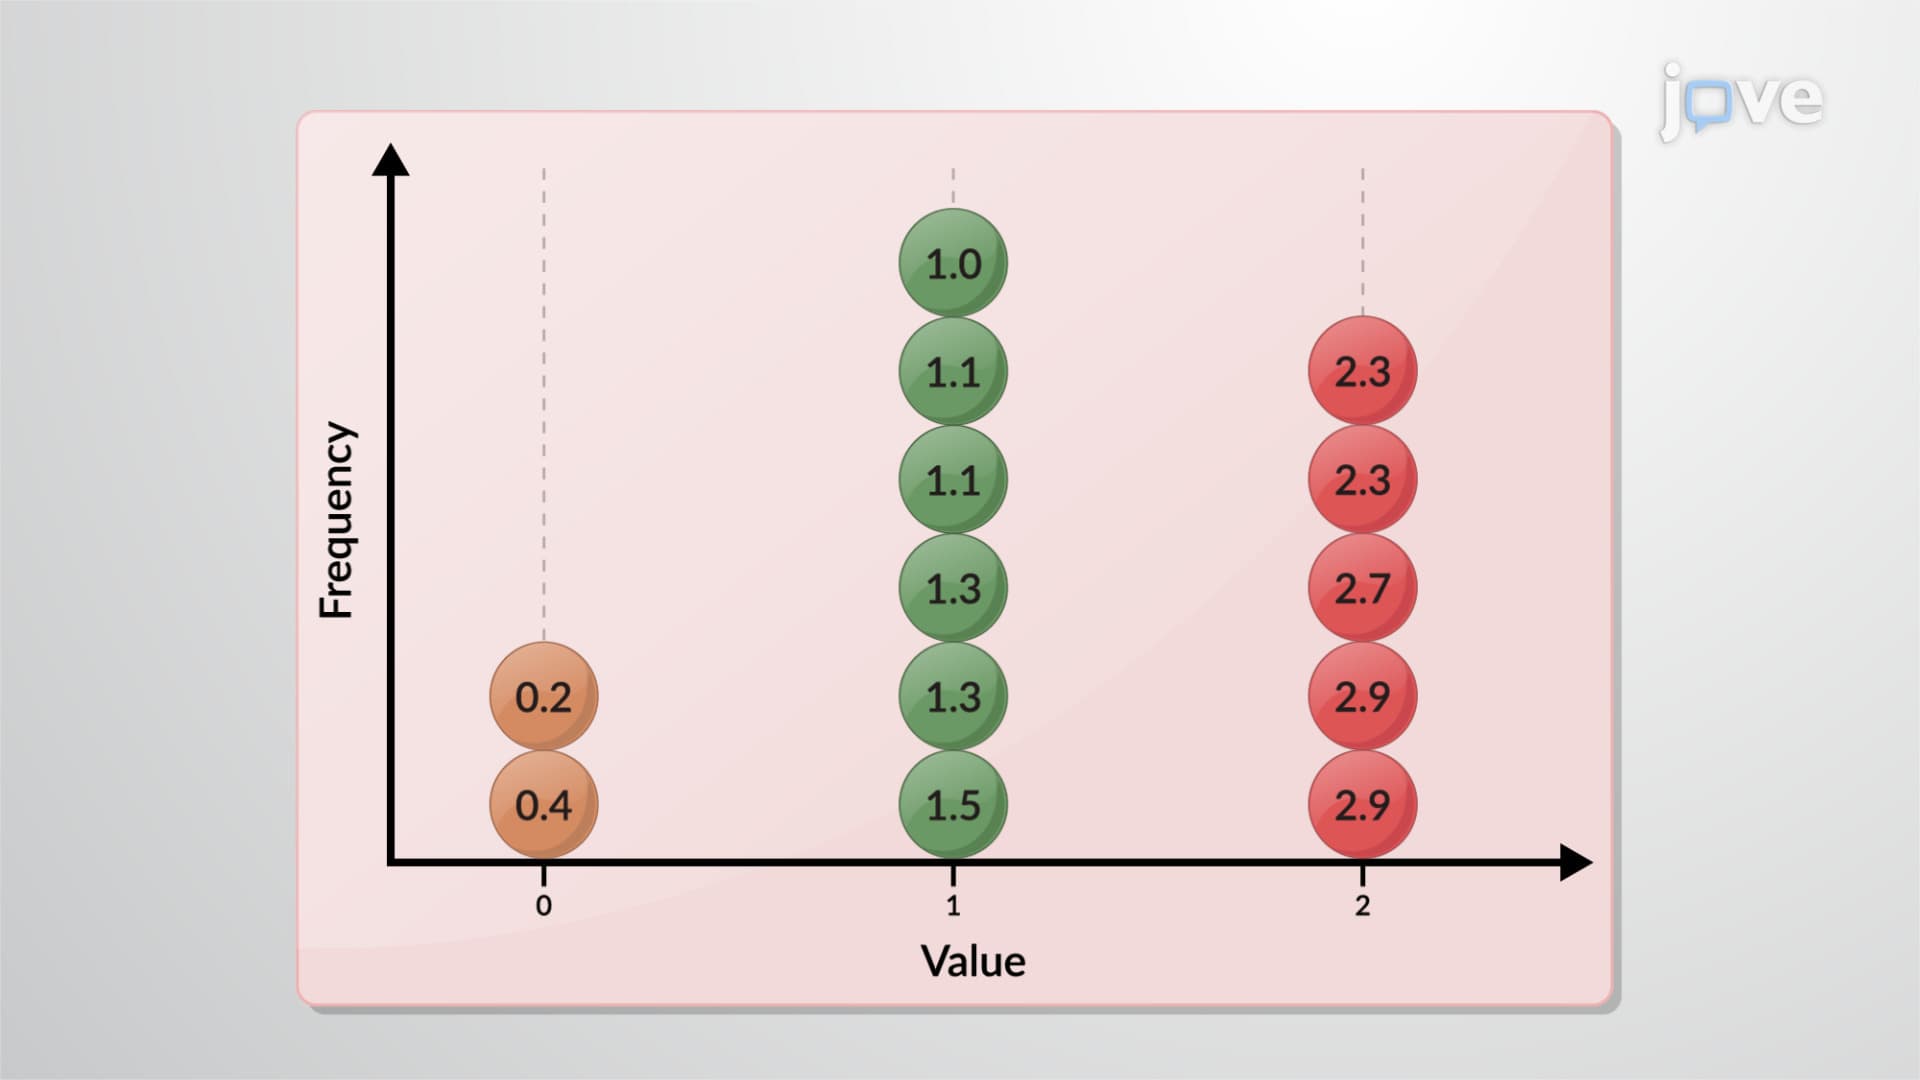
Variability: Analysis
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
 01:15
Variance
The deviations show how spread out the data are about the mean. A positive deviation occurs when the data value exceeds the mean, whereas a negative deviation occurs when the data value is less than the mean. If the deviations are added, the sum is always zero. So one cannot simply add the deviations to get the data spread. By squaring the deviations, the numbers are made positive; thus, their sum will also be positive.The standard deviation measures the spread in the same units as the data.
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Statistical inference techniques, paramount in hypothesis testing, differentiate into two broad categories: parametric and nonparametric statistics.
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
 01:21
Friedman Two-way Analysis of Variance by Ranks
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures from...
 01:09
Empirical Method to Interpret Standard Deviation
The empirical rule, also known as the three-sigma rule, allows a statistician to interpret the standard deviation in a normally distributed dataset. The rule states that 68% of the data lies within one standard deviation from the mean, 95% lies within two standard deviations from the mean, and 99.7% lies within three standard deviations from the mean. Additionally, this rule is also called the 68-95-99.7 rule.
This rule is used widely in statistics to calculate the proportion of data values...
This rule is used widely in statistics to calculate the proportion of data values...