Related Experiment Video
Updated: Jun 5, 2026


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
Robust linear regression methods in association studies
V M Lourenço1, A M Pires, M Kirst
1Department of Mathematics, Faculdade de Ciências e Tecnologia, Universidade Nova de Lisboa, 2829-516 Caparica, Portugal. vmml@fct.unl.pt

Motivation:
It is well known that data deficiencies, such as coding/rounding errors, outliers or missing values, may lead to misleading results for many statistical methods. Robust statistical methods are designed to accommodate certain types of those deficiencies, allowing for reliable results under various conditions. We analyze the case of statistical tests to detect associations between genomic individual variations (SNP) and quantitative traits when deviations from the normality assumption are observed. We consider the classical analysis of variance tests for the parameters of the appropriate linear model and a robust version of those tests based on M-regression. We then compare their empirical power and level using simulated data with several degrees of contamination.
Results:
Data normality is nothing but a mathematical convenience. In practice, experiments usually yield data with non-conforming observations. In the presence of this type of data, classical least squares statistical methods perform poorly, giving biased estimates, raising the number of spurious associations and often failing to detect true ones. We show through a simulation study and a real data example, that the robust methodology can be more powerful and thus more adequate for association studies than the classical approach.
Availability:
The code of the robustified version of function lmekin() from the R package kinship is provided as Supplementary Material.
Related Concept Videos
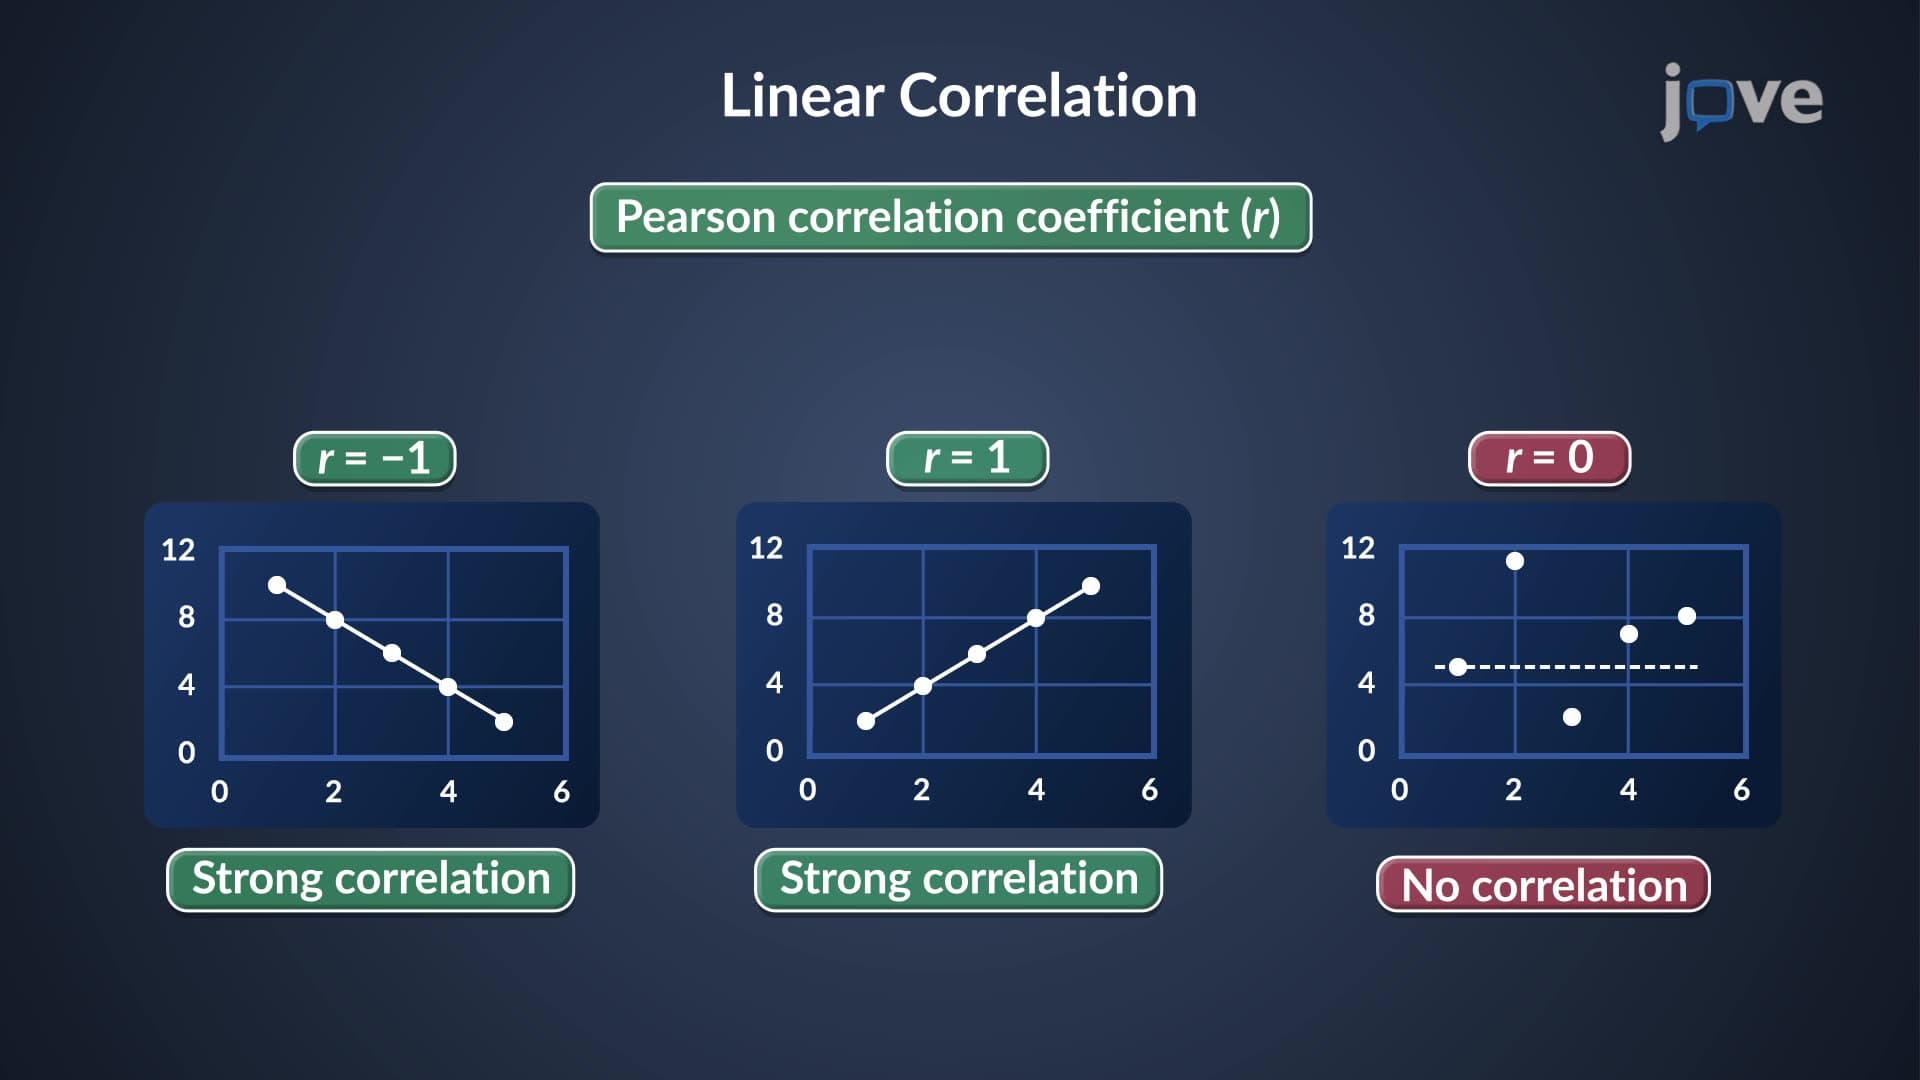 00:53
Correlation and Regression
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:25
Statistical Methods for Analyzing Epidemiological Data
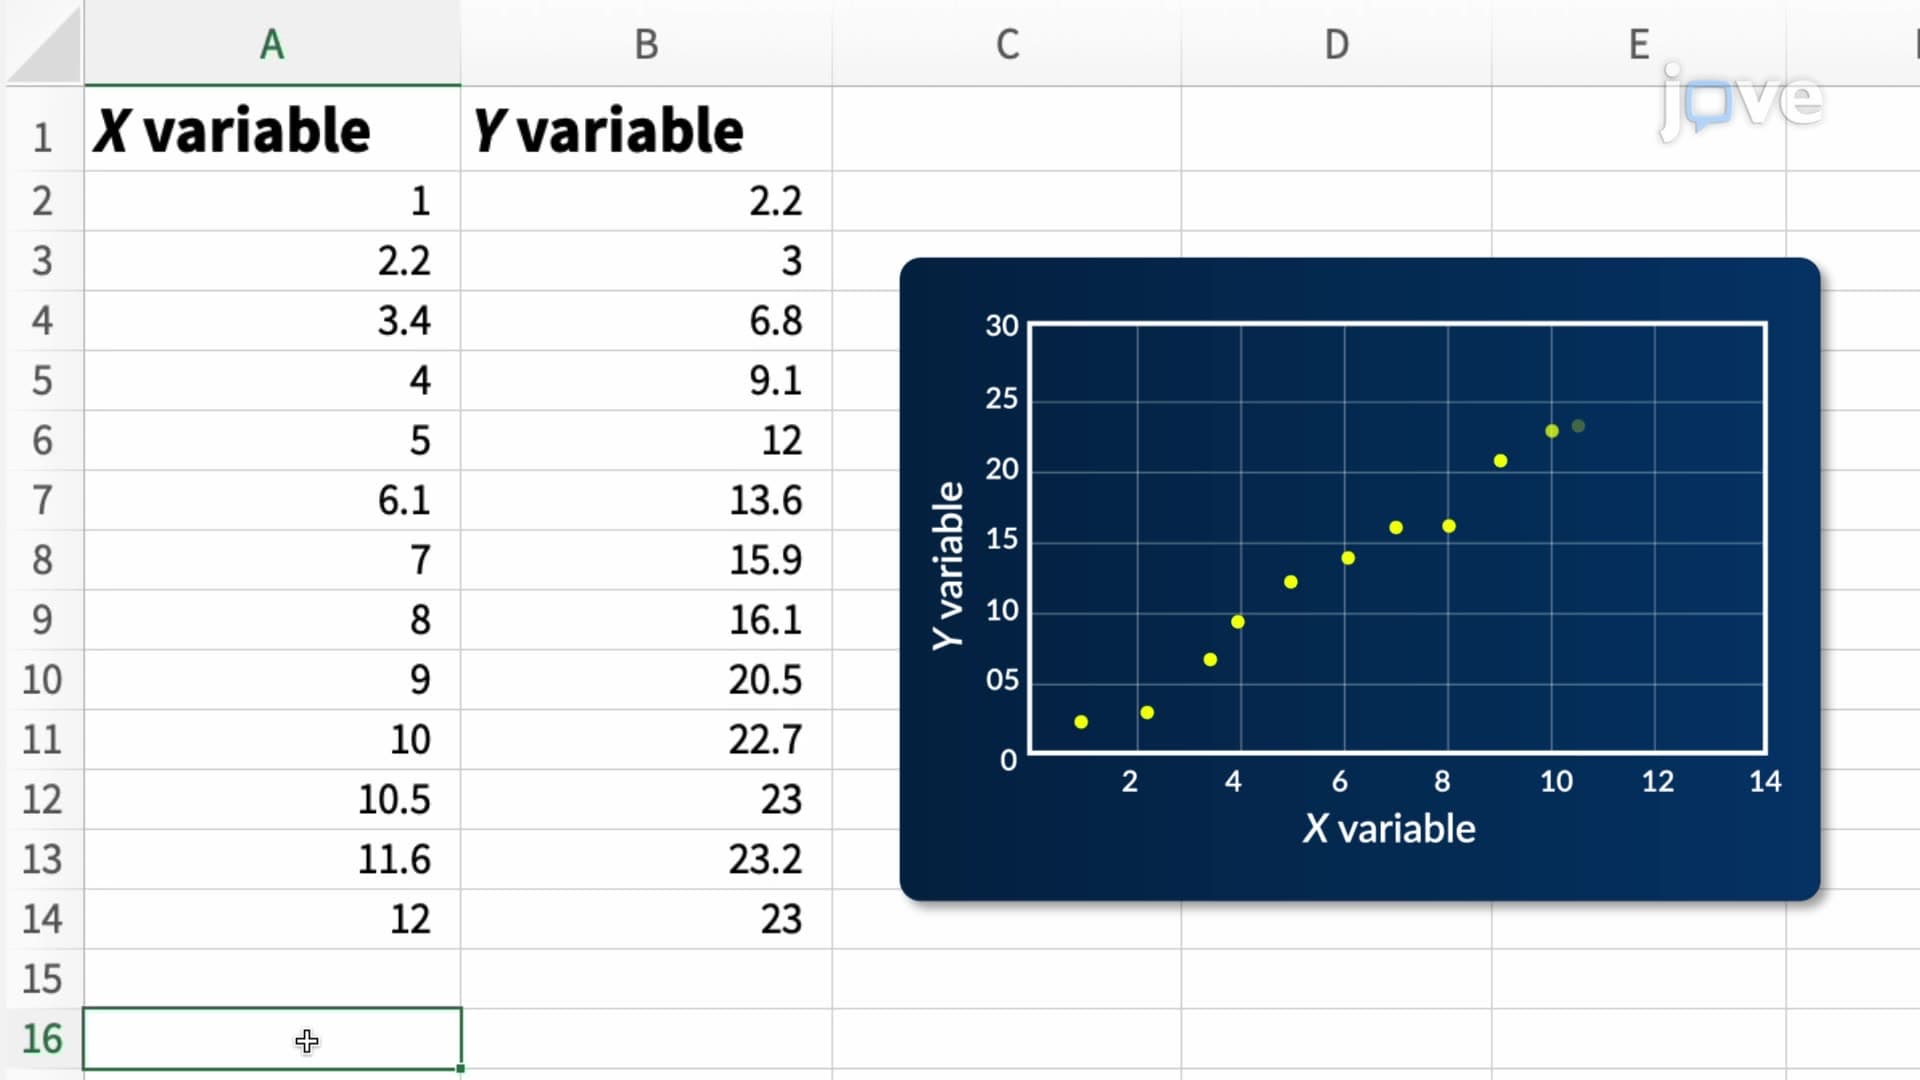 01:18
Microsoft Excel: Regression Analysis
To perform regression...