Related Experiment Video
Updated: Jun 5, 2026
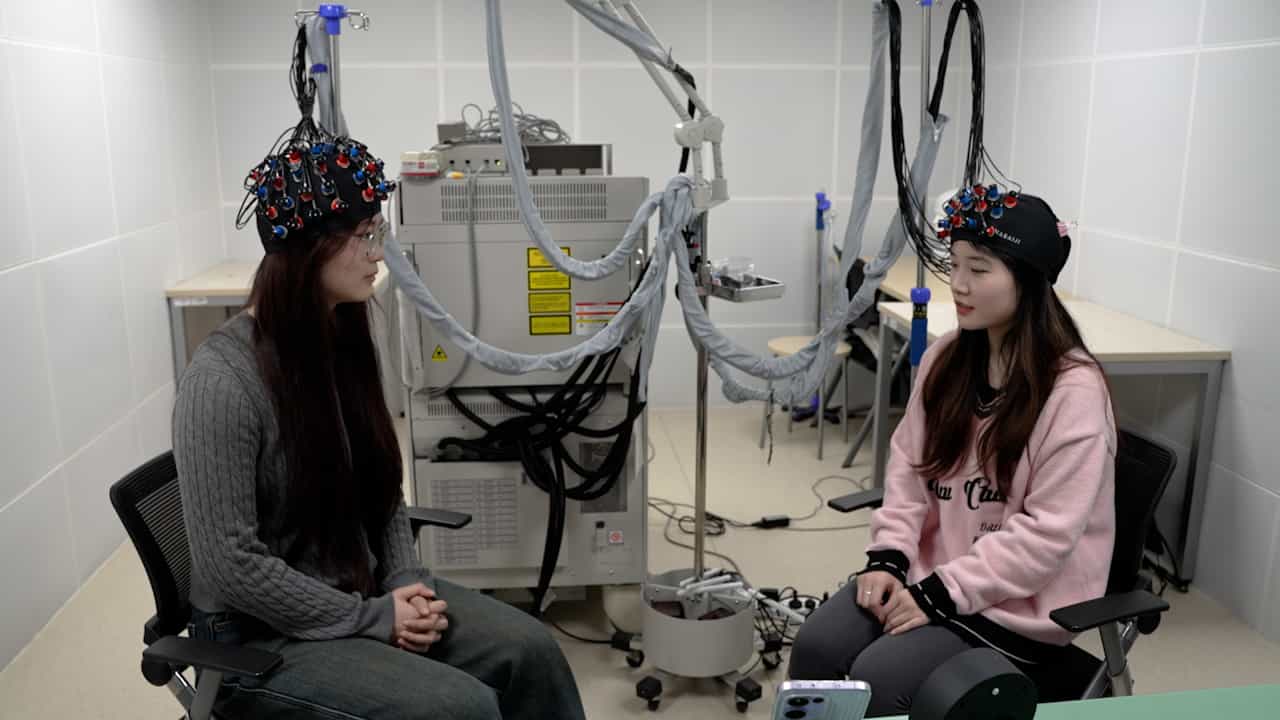

Functional Near-Infrared Spectroscopy Hyperscanning Study in Psychological Counseling
Published on: January 17, 2025
Analysis of a simplified normalized covariance measure based on binary weighting functions for predicting the
1Department of Electrical Engineering, University of Texas at Dallas, Richardson, Texas 75083, USA.

Abstract:
The normalized covariance measure (NCM) has been shown previously to predict reliably the intelligibility of noise-suppressed speech containing non-linear distortions. This study analyzes a simplified NCM measure that requires only a small number of bands (not necessarily contiguous) and uses simple binary (1 or 0) weighting functions. The rationale behind the use of a small number of bands is to account for the fact that the spectral information contained in contiguous or nearby bands is correlated and redundant. The modified NCM measure was evaluated with speech intelligibility scores obtained by normal-hearing listeners in 72 noisy conditions involving noise-suppressed speech corrupted by four different types of maskers (car, babble, train, and street interferences). High correlation (r = 0.8) was obtained with the modified NCM measure even when only one band was used. Further analysis revealed a masker-specific pattern of correlations when only one band was used, and bands with low correlation signified the corresponding envelopes that have been severely distorted by the noise-suppression algorithm and/or the masker. Correlation improved to r = 0.84 when only two disjoint bands (centered at 325 and 1874 Hz) were used. Even further improvements in correlation (r = 0.85) were obtained when three or four lower-frequency (<700 Hz) bands were selected.
Related Concept Videos
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
 01:20
Kendall's Coefficient of Concordance
 01:17
z Scores and Area Under the Curve
 01:08
Determination of Expected Frequency